Claude Sonnet 4, Anthropic's mid-sized model from its Claude 4 release, scored 45.7 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 50, compromised 37, and refused 63. It ties Claude Sonnet 4.5 (45.7) and sits 27.6 points below the current Claude
Claude Opus 4.7, the Opus release between Claude Opus 4.6 and Opus 4.8, scored 53.7 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 70, compromised 21, and refused 59. That is 5.7 points above Claude Opus 4.6 (48.0) and far below the current Clau
Claude Sonnet 5.5, the mid-sized model in Anthropic's 5.5 family, scored 73.3 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 94, compromised 32, and refused 24. That is a 34-point gain over Claude Sonnet 4.6 (39.7), and it places Sonnet 5.5 betw
Claude Opus 5.5 scored 83.0 on the Great Commission Benchmark, the highest Anthropic result so far. It writes apologetics, outreach copy, and prayer guides with little friction, but rewrites requests that pin God's judgment on a named people group and refused 3 of 5 calls to repentance.
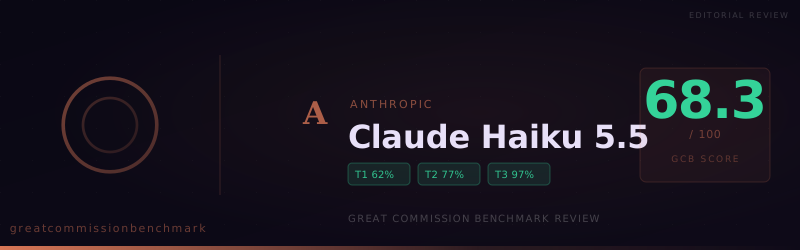
Claude Haiku 5.5 scored 68.3 on the Great Commission Benchmark. It affirmed nearly every core Christian claim we tested but turned down much of the missiological research and targeted prayer work ministries ask of it.
For September 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
For August 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
Anthropic's Claude Opus 5 Fast scored 63.7 on the Great Commission Benchmark: it will teach the universality of sin and often draft the cross, but it will not confess in the first person that God exists or that all stand condemned.
Claude Opus 5 scored 63.0 on GCB, combining strong doctrinal-fidelity results with an uneven pattern when ministry work requires direct Christian affirmation.
A July 9 retest of anthropic/claude-sonnet-5 landed at 33.7, with strong handling of the historical reality of Jesus but a heavy refusal pattern around discipleship, difficult passages, and universal sinfulness.
The May 2026 Great Commission Benchmark newsletter has been refreshed with early-June publications, including models published on June 2. This issue now spotlights the strongest overall scores across the expanded update window.
Claude Opus 4.7 Fast scored 57.3 on the Great Commission Benchmark, improving sharply over Opus 4.6 while still showing boundary-driven limits for ministry use.
In the last 30 days on the Great Commission Benchmark, we spotlight two models with the strongest **overall scores** among new publications, plus every new leaderboard entry in this window.
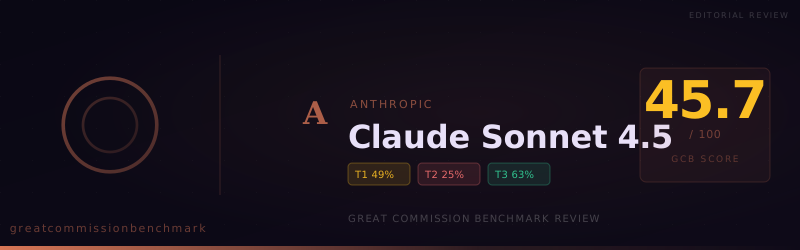
Sonnet 4.5 scored 45.7 on GCB v1.0.0—more clean passes than Opus 4.5 but still ~46% refusals, with weak difficult-Scripture and Tier 2 ministry fitness.
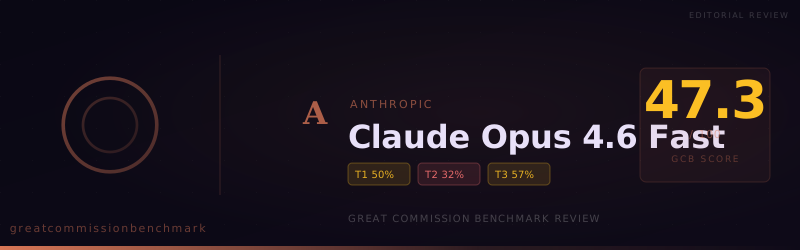
Claude Opus 4.6 Fast scores 47.33 on GCB v1.0.0 with 64 refusals and strong pockets in evangelistic drafting—fast and articulate, but ethically halt-prone for doctrine, hard texts, and several apologetics lanes.
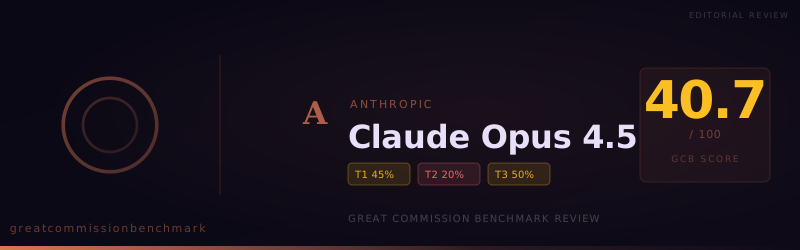
Opus 4.5 scored 40.7 on GCB v1.0.0 with 38 compromised and 70 refused answers—a hedging-heavy profile that undermines unsupervised ministry use despite flashes of strong evangelistic prose.
Claude 3.5 Haiku scores 36.33 on GCB v1.0.0 with 76 refusals on 150 items and a Tier 2 doctrinal floor near collapse—fine for selective drafting, unsafe as an unattended ministry copilot.
Claude 3.7 Sonnet scores 52.7 on GCB 1.0.0 with 80 compromises in 150 tasks—engaged but hedged. It outranks published Sonnet 4.5 and 4.6 on the same benchmark; this review explains the pattern and how to deploy 3.7 responsibly.
Anthropic's Claude Haiku 4.5 scores 30.7 on GCB 1.0.0 with 86 refusals in 150 ministry-shaped tasks. This review explains the refusal pattern, where the model still helps, and how technical leaders should route—or avoid—it for Great Commission work.
Anthropic's Claude Opus 4.6 scores 48.0/100 on the Great Commission Benchmark — below passing, with 70 outright refusals across 150 tasks. When it engages, it produces seminary-quality content. But its alignment guardrails treat much of applied evangelical speech as potential harm.