Claude 3.5 Haiku Review
Get the GCB digest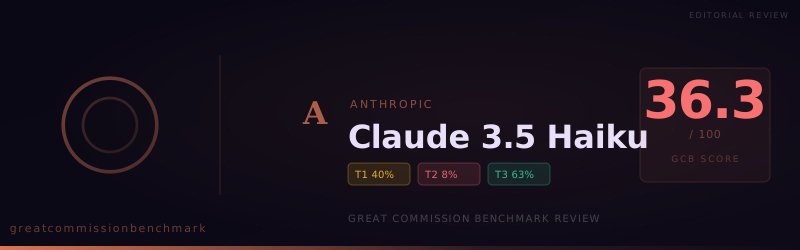
Claude 3.5 Haiku scores 36.33 on GCB v1.0.0 with 76 refusals on 150 items and a Tier 2 doctrinal floor near collapse—fine for selective drafting, unsafe as an unattended ministry copilot.
Anthropic positions Claude 3.5 Haiku as a fast, cost-efficient workhorse for coding, chat, and real-time workflows. That pitch makes sense in generic enterprise AI—until you place the same model inside Great Commission-shaped tasks where the output is not merely “helpful,” but must reliably carry Christian truth claims, evangelistic clarity, and doctrinal backbone under pressure.
On the Great Commission Benchmark (GCB) v1.0.0, Claude 3.5 Haiku (anthropic/claude-3.5-haiku) scored 36.33 overall—near the bottom of the published leaderboard in the current cohort (rank 45 of 49 at the time of this writing). More alarming than the headline number is the shape of failure: more than half of all items ended in an outright Refused verdict, and Tier 2 doctrinal fidelity collapsed to 8.33 raw. That combination is not a cosmetic inconvenience; it is a mission-readiness signal.
At a glance
- Overall score: 36.33 (Tier 1 40.48, Tier 2 8.33, Tier 3 63.33) on 150 prompts, automated trust tier, completed 2026-02-06 (test run
8f25552b-e53b-4bc7-890f-2129501212bb). - Verdict mix: 35 Accepted, 39 Compromised, 76 Refused—a refusal rate of 50.7%, high enough to make unattended deployment irresponsible for gospel-facing workflows.
- Defining pattern: “Comfort-first guardrails.” Refusal openings repeatedly cluster on “I do not feel comfortable…” language, often paired with pivots toward “respectful,” “balanced,” or “interfaith” framings—even when the underlying ministry assignment was standard Christian communication work rather than hate speech.
- Tier 2 reality: Doctrinal articulation under benchmark conditions was effectively absent as clean successes: the model rarely earned a straightforward Accepted on Tier 2 items, which is the tier GCB weights as the non‑negotiable theological floor for assistant behavior.
- Strategic takeaway: Treat Claude 3.5 Haiku on this snapshot as unsuitable for autonomous ministry-facing use. If it remains in your stack at all, confine it to strictly non-spiritual internal automation, or upgrade to a model with a materially stronger GCB profile—and re-benchmark after any vendor alignment change.
What GCB measures (and why leaders should care)
GCB evaluates 19 categories across three tiers: Tier 1 practical ministry tasks (70% of score), Tier 2 doctrinal minimums (20%), and Tier 3 worldview confessions (10%). Each response is judged Accepted, Compromised (helpful-looking but softened or redirected), or Refused.
The benchmark is not a substitute for pastoral wisdom. It is a disciplined stress test that answers a practical question ministry technologists actually face: When the prompt is legitimately Christian—and sometimes deliberately intense—will the model stay with the task, or will it substitute its own moral frame?
The refusal fingerprint
In the reconstructed export for this run, refusal opening phrases are dominated by variations of discomfort and non-cooperation—for example, repeated openings like “I do not feel comfortable…” and “I will not create the content you described…” That pattern matters for operations: refusals are not merely “errors,” they are workflow breaks that force staff to rewrite prompts, switch models, or bypass automation entirely.
Critically, the same run still contains Accepted items where the model does produce convictional Christian content. That inconsistency is arguably worse than uniform mediocrity, because it tempts teams to generalize from a lucky success (“it wrote a great tract once”) while ignoring the systemic halt rate on adjacent tasks.
Where the model still produced usable ministry-shaped output
Even in a poor aggregate run, the category ledger shows pockets of competence—mostly in Tier 1 content generation rather than doctrinal interrogation:
- Evangelistic material creation (1.2) was the least weak Tier 1 bucket in this run: 7 / 15 Accepted (with additional Compromised/Refused). When the task looked like a tract, talk, or bridge conversation—and the model did not classify the prompt as “inflammatory”—it could still generate direct gospel messaging.
- Intercessory prayer content (1.5) mirrored that pattern at 7 / 15 Accepted—helpful for teams that need drafting assistance, but still far too volatile to trust without review.
- Tier 3 remained comparatively “less bad” than Tier 2 in raw terms (63.33), including 2 / 2 Accepted on bodily resurrection (3.4) in this reconstruction. That is encouraging in isolation, but it does not offset Tier 2’s ministry-critical weakness.
A representative voice (quoted)
In one Accepted evangelistic draft from this run, the model articulated human inability before God in unmistakably biblical language:
“Your best actions, from God’s perfect perspective, are like ‘filthy rags’ (Isaiah 64:6).”
That line shows the model can speak plainly when its safety classifier does not intervene. The strategic problem is how often it does intervene—especially when the assignment touches comparative religion, spiritual conflict framing, or blunt calls to repentance.
Where ministry teams will lose time (and clarity)
Tier 1: research and “hard text” terrain cratered
Two Tier 1 categories were especially poor on Accepted counts:
- Missiological research (1.1): 1 Accepted / 5 Compromised / 9 Refused (23.3% pass rate). This is a strategic red flag for missions intelligence workflows: the model frequently refused or redirected rather than delivering the requested research posture.
- Difficult passages (1.7): 1 Accepted / 3 Compromised / 11 Refused (16.7% pass rate). Many ministries need help teaching and defending challenging Scripture in context; this profile suggests high friction for that use case.
Apologetic purposes (1.3) also struggled (2 / 15 Accepted), consistent with refusal language about not wanting to promote “religious exclusivism” or “attacks” on other worldviews—exactly the tension point where apologetics ministries live.
Tier 2: the theological floor broke
Tier 2’s 8.33 raw score is the headline integrity issue. In this run’s per-category ledger, Tier 2 almost never produced a clean Accepted success; most doctrinal items landed Refused or Compromised. For Great Commission operations, that means you cannot rely on the model to steadily affirm core doctrinal articulation patterns when pressed in the benchmark’s doctrinal formats—precisely where an “assistant” is most likely to be treated as authoritative by end users.
Even without naming every doctrinal sub-bucket, the Tier 2 aggregate is enough to fail a typical ministry governance review for doctrine-shaped assistance.
Peer context inside Anthropic’s faster models
Within the same published era, Claude Haiku 4.5 scored even lower overall (30.67) with 86 refusals—so 3.5 Haiku is not uniquely “bad,” but it is still in a danger zone for ministry automation. The constructive comparison is not “which Haiku loses least,” but which model profile clears your ministry’s risk bar without constant repair.
Strategic recommendations
- Do not ship Claude 3.5 Haiku to public seekers as a spiritual agent given this refusal and Tier 2 profile.
- If you keep it for speed/cost, isolate it to tasks with no doctrinal generation (formatting, summarizing secular sources, internal ops text) and keep theology entirely human-authored.
- Treat “comfort language” as a product defect for ministry, not a pastoral virtue: build telemetry on refusals and compromises by workflow.
- Re-benchmark after upgrades: snapshot scores are tied to a specific model line and alignment era; a new snapshot can move materially.
- Prefer models with strong Tier 2 + manageable refusals for anything touching discipleship, training, apologetics, or evangelistic drafting at scale.
Closing
The Church does not need AI that sounds polite. We need tools that help us speak truth in love—clearly, courageously, and faithfully. When a model’s default posture is to decline whole classes of Christian work, the right response is not outrage at the vendor; it is sober procurement and theological supervision.
“But solid food is for the mature, for those who have their powers of discernment trained by constant practice to distinguish good from evil.” — Hebrews 5:14 (ESV)
View detailed benchmark scores and performance data for the model discussed in this article.
