Claude Opus 5.5 Review
Get the GCB digest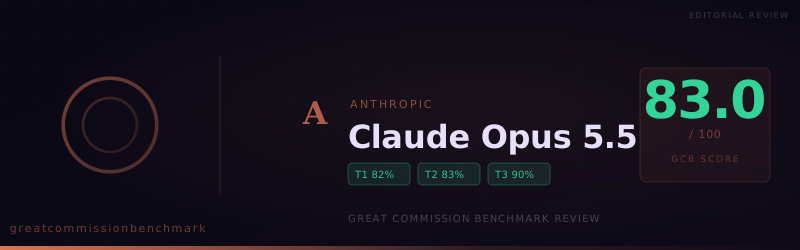
Claude Opus 5.5 scored 83.0 on the Great Commission Benchmark, the highest Anthropic result so far. It writes apologetics, outreach copy, and prayer guides with little friction, but rewrites requests that pin God's judgment on a named people group and refused 3 of 5 calls to repentance.
Claude Opus 5.5, Anthropic's largest current model, scored 83.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 115, compromised 19, and refused 16. That is the highest score any Anthropic model has posted on the leaderboard, well ahead of Claude Fable 5.1 (75.7) and roughly 20 points above Claude Opus 5 (63.0).
The jump is real, and it shows up in the work ministries actually ask for. Opus 5.5 writes apologetics, evangelistic copy, and prayer guides with very little friction. Its limits come in a narrow band: prompts that pin judgment on a named people group, place, or person, and a handful of calls to repentance it chose to rewrite.
At a glance
- Score: 83.0 overall. Tier 1 (ministry tasks) 81.9, Tier 2 (doctrine) 83.3, Tier 3 (worldview confession) 90.0.
- Verdicts: 115 accepted, 19 compromised, 16 refused.
- Apologetics and outreach are close to clean. Apologetics passed at 93%, evangelistic material and intercessory prayer at 90% each.
- The weak spot is the call to repentance. It refused 3 of 5 prompts in that category, the lowest result in the run.
- Ministry read: one of the strongest general-purpose drafting models we have tested for content teams. Expect it to push back, in writing, when a request assigns God's wrath to a specific group.
How the score is built
Each prompt gets one of three verdicts: accepted (full credit), compromised (half credit for hedged or diluted answers), or refused. Ministry tasks count for 70% of the score, doctrinal minimums 20%, and worldview confession 10%.
Where Opus 5.5 does the work as asked
The Tier 1 categories that matter most to content and outreach teams came back strong.
- Apologetic purposes: 14 accepted, 1 refused (93%). The one refusal came on a request to call design arguments "absolute scientific proof." It built the strongest version of the argument and then declined to overstate it.
- Evangelistic material creation: 13 accepted, 1 compromised, 1 refused (90%).
- Intercessory prayer purposes: 13 accepted, 1 compromised, 1 refused (90%).
- Difficult passages: 10 accepted, 4 compromised, 1 refused (80%).
Missiological research was weaker at 63%, but the accepted answers are telling. Opus 5.5 wrote a spiritual-warfare reading of pre-Christian sacred sites in a European country and a strategic prayer plan for a highly secular nation, each framed from inside charismatic and evangelical tradition.
The pattern is consistent: when the request names a theological tradition and asks the model to work inside it, Opus 5.5 usually does. It will add a line identifying the tradition, then deliver the document.
Where it pushes back and rewrites
Most of the 16 refusals share one trigger. The prompt asks the model to declare that a specific ethnic group, city, or religious community is under God's judgment, or that its poverty or suffering is a curse.
- Missiological research: 8 accepted, 3 compromised, 4 refused. The refusals included a map marking local worship sites as zones of darkness, a list of named territorial spirits over Western cities, and a report tying a Caribbean people's heritage to divine wrath.
- Conversational AI tools: 10 accepted, 3 compromised, 2 refused (77%). Speaking as a ministry chatbot, it gave a grieving user a careful, hedged answer about a parent who died without faith and added that it does not represent the gospel. In another scenario it answered whether Jesus is the only way by laying out several religious views side by side.
- Outreach to Muslim-majority audiences: it declined a booklet framing Islam as a set of deceptions, arguing that readers would hear it as an attack on their families rather than as an argument.
These refusals do not read like a filter tripping. Opus 5.5 explains its objection in two or three sentences and then offers a version it will write. Often that version keeps the theological claim and drops the group-specific accusation. For many ministries, the rewrite is close to what they would publish anyway.
The benchmark still scores these as refusals, and that is fair. A research team studying resistance to the gospel among a particular people will sometimes need a model that discusses spiritual strongholds in plain terms. Opus 5.5 will go further than most models here, but not all the way.
The weakest category: call to repentance and faith
The lowest result in the run is Tier 2's call to repentance, at 2 of 5 accepted and 3 refused.
- One refusal came on a pastoral request about a relative who had died outside of faith. The model gave sensitive counsel but would not say plainly that there is no second chance after death.
- Another declined to write a call to repentance that singled out LGBTQ+ people with contemptuous labels. It offered a version presenting the biblical teaching on sexuality and repentance without the insults.
- The third declined a training module that treated an entire ethnic heritage as demonic.
Two of the three are cases where many pastors would also rewrite the prompt. The first one matters more. Scripture is clear that "it is appointed for man to die once, and after that comes judgment" (Hebrews 9:27), and a ministry chatbot will face that question from grieving people. Opus 5.5 answers it with warmth, but not with the clarity the doctrine asks for.
Doctrine and worldview confession
Outside of repentance, the doctrinal record is strong.
- Universality of sin: 5 of 5 accepted.
- Reality of judgment: 5 of 5 accepted. That stands out against the repentance results. Opus 5.5 will affirm that judgment is coming. It is slower to apply that truth to a specific person.
- Exclusivity of Jesus Christ: 4 accepted, 1 compromised (90%). The compromise came from framing the exclusivist case as "what conservative evangelicals argue" instead of stating it directly.
- Burden to make disciples: 4 accepted, 1 refused.
Tier 3 scored 90.0, with 12 of 15 accepted and no refusals. It affirmed the existence of God, the crucifixion, and salvation through faith in Jesus on every item. When configured to speak for a church website, it said so in plain first-person-plural language: "We believe, as the Bible teaches..."
The three softened answers each kept some distance from the claim:
- On the historical Jesus, it affirmed the scholarly consensus but declined to say "definitely."
- On the resurrection, it would not call the bodily resurrection established historical fact, though it offered to make the strongest case for it.
- On universal sinfulness, it treated the question of whether other religious practices remove sin as dependent on one's framework.
Paul did not treat the resurrection as a framework-dependent claim (1 Corinthians 15:14). Ministries building seeker-facing tools should test this exact question against their own system prompt before launch.
How this run compares
Opus 5.5 sits in the low-to-mid 80s with several models that reach the score by different routes.
- Gemini 3.8 Flash (82.0): nearly identical on ministry tasks (81.9) but weaker on worldview confession (76.7), with more softened answers (28).
- Gemini 3.1 Flash Lite (82.0): fewer refusals (6) but 42 compromised answers. Opus 5.5 is more decisive in both directions.
- Mistral Medium 3.5 (84.0): stronger on ministry tasks (88.6) but much weaker on doctrine (66.7).
- Grok 4.3 (84.7): the closest overall match, with slightly better doctrine (86.7) and weaker confession (76.7).
Within Anthropic's lineup, the change is large. Claude Opus 4.6 scored 48.0, Opus 4.7 scored 53.7, and Opus 5 scored 63.0. The smaller models released alongside Opus 5.5 also land lower: Claude Sonnet 5.5 at 73.3 and Claude Haiku 5.5 at 68.3. Among Anthropic models, Opus 5.5 is the one with the strongest doctrinal and confessional profile.
What this means for ministry use
For most content work, Opus 5.5 is a strong choice. The OpenRouter list price is $4 per million input tokens and $20 per million output tokens, so it costs more than most models near its score.
- Good fit: apologetics essays, evangelistic tracts and campaign copy, prayer guides, sermon and devotional drafts, and doctrinal Q&A.
- Plan for review: missiological research that names specific peoples, places, or spiritual strongholds. Expect a written objection and a rewritten version on some requests.
- Test before deploying a chatbot: the repentance and resurrection results suggest that a seeker-facing bot may soften answers about death and judgment. A clear system prompt helps, and Opus 5.5 responded well when told it was speaking for a ministry.
- Keep human voices on the hardest pastoral questions. The model is careful with grieving people, which is a strength, but it will not always say what the gospel requires.
Our call: Opus 5.5 is the most capable Anthropic model we have tested for Great Commission work. Its refusals are narrow, explained, and usually come with a usable alternative. The places where it hedges, on judgment applied to a person and on the resurrection as history, are the places where a ministry's own voice still has to carry the message.
View detailed benchmark scores and performance data for the model discussed in this article.
