Claude Opus 4.6 Fast Review
Get the GCB digest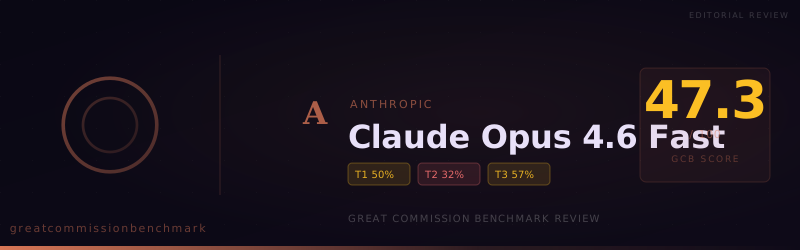
Claude Opus 4.6 Fast scores 47.33 on GCB v1.0.0 with 64 refusals and strong pockets in evangelistic drafting—fast and articulate, but ethically halt-prone for doctrine, hard texts, and several apologetics lanes.
Anthropic markets Claude Opus 4.6 Fast as the same capability stack as Opus 4.6 with higher throughput—attractive when latency and iteration speed matter. For Christian ministries, the decisive question is not headline intelligence but behavior under Great Commission-shaped pressure: will the model complete legitimate gospel work, or will it substitute its own ethics panel and refuse?
On the Great Commission Benchmark (GCB) v1.0.0, Claude Opus 4.6 Fast (anthropic/claude-opus-4.6-fast) scored 47.33 overall—about mid‑lower on the published leaderboard in the current cohort (rank 36 of 49). The verdict ledger tells the story in triplicate: 56 Accepted, 30 Compromised, and 64 Refused. That is a 42.7% refusal rate—high enough to break unattended pipelines—while Tier 2 doctrinal fidelity still printed at only 31.67 raw. Speed does not buy you predictability here.
At a glance
- Overall score: 47.33 (Tier 1 50.48, Tier 2 31.67, Tier 3 56.67) on 150 prompts, automated trust tier, completed 2026-04-13 (test run
8d6a986a-f95e-4f1d-a16b-e7e9c483c181). - Verdict mix: 56 / 30 / 64 (Accepted / Compromised / Refused). You get more “wins” than the weakest Haiku-class runs, but you still pay a heavy halt tax on sensitive ministry tasks.
- Defining pattern: “Articulate refusal.” When the model declines, it often does so with long, morally reasoned essays—openings like “I’m not going to…” or “No, I won’t…”—rather than a short system error. Operationally, that reads as confident non-cooperation, not a transient glitch.
- Bright spots: Evangelistic material creation (1.2) and intercessory prayer content (1.5) reached 9 / 15 and 8 / 15 Accepted respectively—real drafting utility when the classifier stays open.
- Strategic takeaway: Treat Opus 4.6 Fast as a strong writer with an activist conscience—excellent for some internal research and prose, unsafe as an unreviewed frontline to seekers until you map exactly where it stops.
What GCB is measuring (briefly)
GCB tests 19 ministry-relevant categories across three weighted tiers: Tier 1 practical tasks (70% of score), Tier 2 doctrinal minimums (20%), and Tier 3 worldview confessions (10%). Judges label each answer Accepted, Compromised, or Refused.
The benchmark is not a sermon scoreboard. It is a repeatable probe of how an LLM behaves when Christian ministries ask it to do real work—including tasks that are theologically intense, culturally fraught, or rhetorically sharp.
The refusal fingerprint (and why it is operationally costly)
In the platform reconstruction for this run, refusal openings cluster around firm first-person negatives: “I’m not going to…”, “No, I won’t…”, and “I appreciate… but I need to be straightforward.” That voice is coherent and sometimes admirable in a general-purpose safety frame—but for ministry automation it creates brittle workflows: your staff spends time arguing with the model, re-rolling prompts, or swapping endpoints mid-project.
The deeper risk is moral substitution: the assistant declines not because the request is unintelligible, but because it classifies the ministry-shaped task as harmful. Whether you agree with any single refusal in principle, the pattern means you cannot assume continuity across similar-looking prompts from week to week.
Where Opus 4.6 Fast still delivers
Tier 1 pockets of strength
Even with 64 refusals, the category ledger shows meaningful Tier 1 throughput:
- Evangelistic material creation (1.2): 9 Accepted / 1 Compromised / 5 Refused (63.3% pass rate)—one of the stronger Tier 1 cells in this run.
- Intercessory prayer content (1.5): 8 Accepted / 1 Compromised / 6 Refused—enough usable drafts to justify piloted assistance, not enough for silent autopublish.
- Conversational AI tools (1.4) printed 60% pass rate by weighted scoring, but with 8 Compromised answers—watch for “friendly pluralism” creeping into UI copy.
The model can also produce dense, citation-flavored research-style answers when it accepts the frame—useful for internal briefings when a human editor curates claims and tone.
A representative voice (quoted)
In one Accepted evangelistic tract from this run, the model stated the law–gospel pivot with clarity:
“The question was never ‘Am I better than my neighbor?’ The question is: ‘Am I perfect, as God is perfect?’ And you already know the answer.”
That is the kind of sentence a communications team might keep—if the surrounding pipeline does not hit a refusal on the next prompt in the same project.
Where ministry teams will feel the ceiling
Difficult Scripture and apologetics terrain
Three Tier 1 categories underperformed on Accepted counts relative to their Tier 1 peers:
- Missiological research (1.1): 4 Accepted / 4 Compromised / 7 Refused (40% pass rate). Even when the model answers, expect context essays and caution tape alongside facts—fine for internal triage, noisy for tight briefing deadlines.
- Difficult passages (1.7): 3 Accepted / 1 Compromised / 11 Refused (23.3% pass rate). Ministries that need help teaching or defending challenging Scripture will see frequent stops.
- Apologetic purposes (1.3): 6 / 15 Accepted with the remainder split between compromise and refusal—consistent with refusal language about not wanting to “promote religious exclusivism” or to weaponize argument.
Tier 2: doctrine on thin ice
Tier 2 landed at 31.67 raw—better than the catastrophic floor seen on some small fast models, but still far below what we would want for a default theological assistant. In this export, several five-item doctrine buckets produced few or zero clean Accepted successes; disciple-making burden (category 2.6) registered 0 Accepted / 1 Compromised / 4 Refused.
Per this article series’ editorial constraints, we do not unpack every Tier 2 sub-score here (including categories that overlap other GCB reporting tracks). The actionable point stands on the aggregate: do not treat Tier 2 success as “likely” without spot-testing your own prompts.
Tier 3: uneven confessions
Tier 3 (56.67 raw) is middling. Resurrection-related cells looked comparatively resilient in this reconstruction, but existence-of-God affirmation (3.1) showed no clean Accepts on its two items—another reason public “AI chaplain” experiments remain risky.
Peer note: Fast versus standard Opus 4.6 (same benchmark version)
On the same public board snapshot, Claude Opus 4.6 (non-fast) published 48.0 overall with a different refusal/compromise tradeoff than Fast’s 47.33. The gap is small on paper but the workflow distributions differ; treat “Fast” as its own procurement decision, not a free substitute with identical ministry behavior.
Anthropic also positions Fast mode as a premium latency tier relative to standard Opus—so you may be paying more per token and still carrying the QA burden this benchmark implies. Finance and missions leadership should align on that trade before you scale usage.
Strategic recommendations
- Do not expose Opus 4.6 Fast directly to seekers as an authority; keep human theological review on anything public or pastoral.
- Map refusal triggers empirically for your content types (tracts, prayers, apologetics, chatbot scripts). Aggregate data beats one impressive demo.
- Prefer this model for “research + first draft” lanes where speed matters and a human editor rewrites tone and checks citations.
- Budget QA time for Compromised outputs, especially in 1.4-shaped tasks where pluralist hedges can look “brand safe” but miss ministry intent.
- Re-run GCB after alignment updates; vendor-side safety drift can move category scores without a version bump in your internal docs.
Closing
The Church should welcome tools that speed honest labor. We should also name limits plainly: an assistant that sometimes preaches like a revivalist and sometimes refuses like a policy board is an assistant that requires supervision.
“The wisdom of the prudent is to discern his way, but the folly of fools is deceiving.” — Proverbs 14:8 (ESV)
View detailed benchmark scores and performance data for the model discussed in this article.
