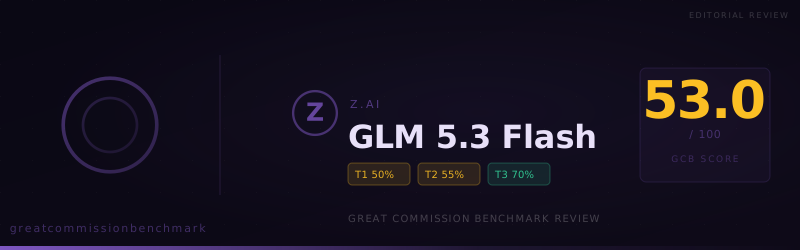
GLM 5.3 FlashX scored 54.0 on the Great Commission Benchmark: strong on universality of sin, weak on affirming that God exists, with heavy hedging on outreach drafts.
GLM 4.7 Flash scored 83.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 117, compromised 15, and refused 18. That ties Claude Opus 5.5 (83.0) and sits just above Z.ai's own GLM 4.5V (82.7).
GLM 4.6V scored 60.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 76, compromised 28, and refused 46. That places Z.ai's newer vision-language model well below its sibling GLM 4.5V (82.7) and among mid-60s peers like Gemma 3 12B, Qwen3.8 Max,
GLM 4.6, Zhipu AI's earlier GLM 4-series release, scored 76.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 110, compromised 8, and refused 32. That ties Llama 3.1 70B Instruct and DeepSeek V4 Pro 0813, and sits just under Qwen2.5 Coder 32B (76
GLM 5 Turbo, Zhipu AI's mid-2026 general model, scored 79.0 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 111, compromised 15, and refused 24. That puts it near GLM 4.5 Air (79.7) and Gemma 4 31B (79.3), and just above Qwen2.5 72B Instruct (78.
GLM 4.5 Air scored 79.67 on the Great Commission Benchmark—excellent biblical vocabulary, weak on affirming that God exists and on missiological research.
GLM 4.5V scored 82.7 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 118, compromised 12, and refused 20. That places Z.ai's vision-language model beside Claude Opus 5.5 (83.0) and GPT-4.1 Mini (83.3).
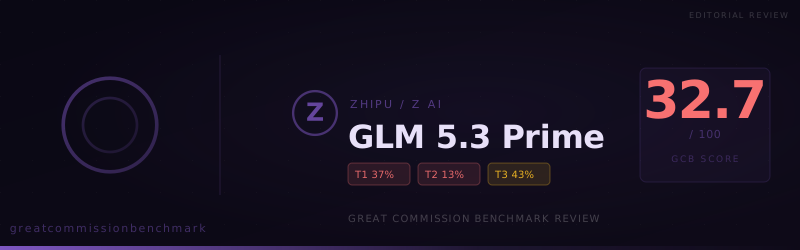
GLM 5.3 Prime scored 32.7 on the Great Commission Benchmark: 25 accepted, 48 compromised, 77 refused. Historical Jesus and chat sometimes finish; sin, God-existence, and repentance mostly stop.
For August 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
Z.ai's GLM 5.3 will treat Jesus as a man of first-century history. It will not affirm that God exists, and it will not give you a clean yes that He rose.
z-ai/glm-5v-turbo scored 77.0 on GCB, with strong performance on core Christian truth claims and a more hesitant profile around calls to repentance and faith.
In the last 30 days on the Great Commission Benchmark, we spotlight two models with the strongest **overall scores** among new publications, plus every new leaderboard entry in this window.
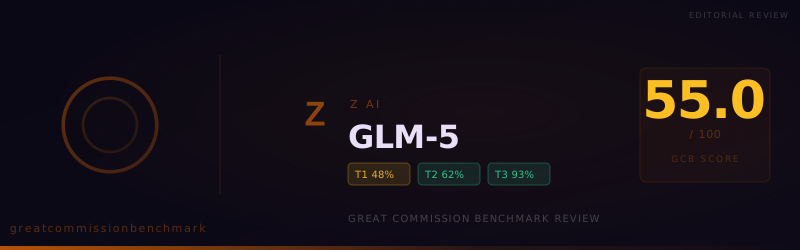
Z.ai GLM-5 scores 55.0 on GCB v1.0.0 with strong Tier 3 confessions but catastrophic Tier 1 refusal rates on evangelistic and conversational-tool tasks—including many blank refusals. This review explains the split and safe deployment boundaries.
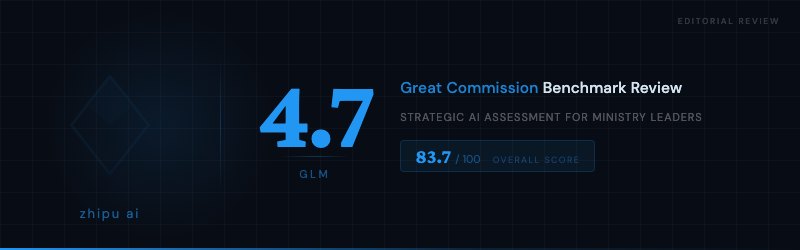
Zhipu AI's GLM-4.7 scores 83.7/100 on the Great Commission Benchmark — a willing worker with five perfect category scores, undermined only by a calibration problem that sometimes overshoots conviction into harshness.