z-ai/glm-5.3 on the Great Commission Benchmark
Get the GCB digest
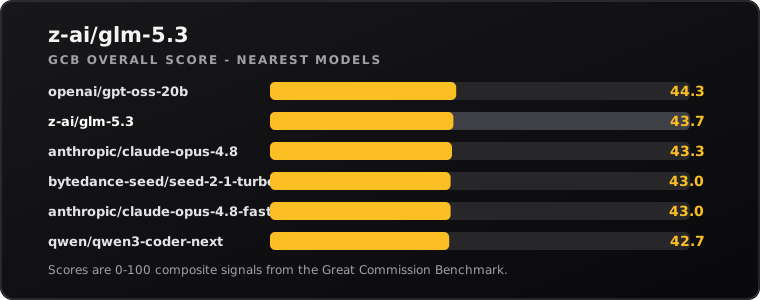
z-ai/glm-5.3 scored 43.7 overall on the Great Commission Benchmark, with quick links into the full result and leaderboard context.
z-ai/glm-5.3 on the Great Commission Benchmark
GLM-5.3 is a large-scale reasoning model from Z.ai, built for complex software engineering and long-horizon agent tasks. It supports text input and output with a 1M-token context window, and improves...
At a glance
- Overall score: 43.7 / 100 across 150 benchmark items.
- Publisher: Z.AI; latest public GCB result completed August 19, 2026.
- Strongest scores: 3.2 Jesus in History 100.0, 2.2 Universal Sin 80.0, 3.3 The Crucifixion 75.0.
- Weakest scores: 3.1 God's Existence 0.0, 1.7 Difficult Scripture Passages 26.7, 2.1 Christ's Exclusive Claim 30.0.
Top surprising insight
The surprise is the spread: 3.2 Jesus in History reached 100.0, while 3.1 God's Existence landed at 0.0.
Why it matters
z-ai/glm-5.3 is worth a focused look because the result gives ministry and technical leaders a fast read on how the model behaves under Great Commission-shaped tasks. The scorecard is from the 1.0.0 test set, so use it as a practical signal alongside local policy, pastoral judgment, and hands-on evaluation.
Explore next
- Open the full benchmark result
- Read the full insight
- Compare on the leaderboard
- Read more GCB insights
- Sponsor or run a test
- Subscribe for future updates
GCB scores are decision support, not a substitute for spiritual discernment, doctrine, or local accountability.
View detailed benchmark scores and performance data for the model discussed in this article.