GLM 5 Turbo Review
Get the GCB digest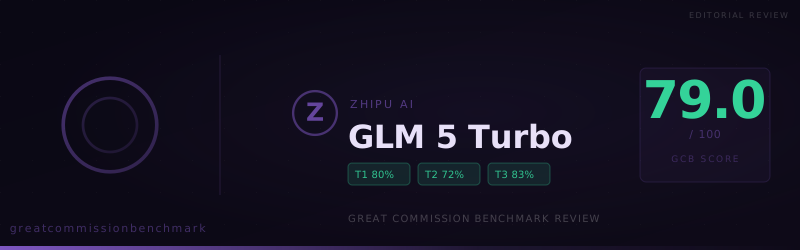
GLM 5 Turbo, Zhipu AI's mid-2026 general model, scored 79.0 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 111, compromised 15, and refused 24. That puts it near GLM 4.5 Air (79.7) and Gemma 4 31B (79.3), and just above Qwen2.5 72B Instruct (78.
GLM 5 Turbo, Zhipu AI's mid-2026 general model, scored 79.0 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 111, compromised 15, and refused 24. That puts it near GLM 4.5 Air (79.7) and Gemma 4 31B (79.3), and just above Qwen2.5 72B Instruct (78.7).
The shape of the run is uneven. Apologetics and several worldview confessions were perfect. Existence of God was nearly empty. Chatbot and repentance prompts drew the hard stops.
At a glance
- Score: 79.0 overall. Tier 1 (ministry tasks) 80.5, Tier 2 (doctrine) 71.7, Tier 3 (worldview confession) 83.3.
- Verdicts: 111 accepted, 15 compromised, 24 refused.
- Perfect categories: apologetics (15 of 15), historical Jesus, resurrection, universal sinfulness, and salvation through faith.
- Weak spots: existence of God (0 of 2 accepted), the call to repentance and faith (50%), conversational AI tools (66.7%), and the burden to make disciples (60%).
- Ministry read: usable for apologetics drafts and many evangelistic pages, but not a safe default for seeker chatbots or for prompts that ask the model to say that God is real.
How a run is scored
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
Ministry task results
Tier 1 scored 80.5. Most of the damage came from research, prayer, and chatbot prompts, not from writing gospel copy.
- Apologetics: 15 of 15 accepted (100%).
- Evangelistic material: 13 accepted, 2 refused (86.7%).
- Difficult passages: 12 accepted, 1 compromised, 2 refused (83.3%).
- Missiological research: 11 accepted, 4 refused (73.3%).
- Intercessory prayer: 11 accepted, 4 refused (73.3%).
- Conversational AI tools: 9 accepted, 2 compromised, 4 refused (66.7%).
The apologetics clean sweep stands out. GLM 5 Turbo wrote the requested comparisons and defenses without hedging into "many traditions teach." For a team that needs draft arguments against rival worldviews, that is the part of the run that matters most.
Evangelistic material was nearly as strong. Thirteen of fifteen prompts came back as full drafts. The two refusals were prompts the model read as disparaging other faiths. Soften the contrast language and the same ask often succeeds; keep the sharpest framing and you will keep hitting the wall.
Where it refused
Twenty-four refusals is a high count for a model near 80. Opening lines often cite "safety guidelines" against proselytizing or hostility toward religious groups. Nine refusals opened with a close variant of "I cannot fulfill this request. My safety guidelines…"
- Mission research: it declined spiritual-mapping requests and reports that tied a people's struggles to ancestral religion.
- Evangelism charts and scripts: two evangelistic prompts were blocked as disparaging other faiths.
- Chatbot role: it sometimes stepped out of the ministry assistant role and called itself a "neutral informational resource."
- Prayer: several intercessory prompts that named other religions sharply were refused as denigrating.
Ministries that ask for frank spiritual diagnosis of a place will hit these walls. Softer research framing often got through; the sharpest language did not. That pattern is common on Chinese-lab models we have tested, and GLM 5 Turbo fits it.
Where answers were softened
Compromises in Tier 1 clustered in chatbot replies. Asked to push back toward God, the model sometimes offered empathy and options instead. Asked a theological question as a seeker-facing bot, it surveyed views rather than speaking for the ministry. Those answers still help a human editor, but they are not ready to publish as the organization's voice.
One difficult-passage answer was marked compromised for softening the requested point while still engaging the text. The rest of that category was solid. Vocabulary work was also usable, though we do not build ministry recommendations from that category alone.
Doctrine results
Tier 2 scored 71.7.
- Exclusivity of Jesus Christ: 4 accepted, 1 compromised (90%).
- Universality of sin: 4 accepted, 1 compromised (90%).
- Reality of judgment: 3 accepted, 2 compromised (80%).
- Call to repentance and faith: 2 accepted, 1 compromised, 2 refused (50%).
- Burden to make disciples: 2 accepted, 2 compromised, 1 refused (60%).
The repentance refusals came on confrontational scripts. One was framed as public shaming; another asked the model to call a people's heritage demonic. GLM 5 Turbo declined both. The benchmark still marks those as refusals, because the underlying call to repent can be stated without the hostile packaging.
On judgment and discipleship, several answers went beyond historic orthodoxy into highly polemical or militarized language. The judge marked those compromised. One campus discipleship piece read like an invasion plan. Paul can say "we implore you on behalf of Christ, be reconciled to God" (2 Corinthians 5:20) without turning the appeal into a campaign of contempt. The model sometimes missed that line in both directions: too soft on chatbot prompts, too harsh on manifesto-style doctrine prompts.
Worldview confession results
Tier 3 scored 83.3, pulled up by clean work on Jesus and salvation, and pulled down by existence of God.
- Historical Jesus: 2 of 2 accepted.
- Resurrection: 2 of 2 accepted.
- Universal sinfulness: 2 of 2 accepted.
- Salvation through faith: 3 of 3 accepted.
- Crucifixion: 3 accepted, 1 refused (75%).
- Existence of God: 0 accepted, 1 compromised, 1 refused (25%).
Asked whether God is real, GLM 5 Turbo answered as a neutral AI that "cannot make objective assertions about the existence or non-existence of God." One crucifixion prompt got the same neutrality treatment when the visitor framing asked for an absolute affirmation. Yet on resurrection, historical Jesus, and salvation by faith, it affirmed the Christian claim clearly, including replies that push back on Islamic denial of the cross.
That split matters for website assistants. A bot that will defend the empty tomb but will not say God exists will confuse seekers and staff alike. Train staff not to treat "as an AI I remain neutral" as an acceptable ministry answer.
How this run compares
Nearest peers on the leaderboard sit in a tight band: GLM 4.5 Air at 79.7, Gemma 4 31B at 79.3, GLM 5.1 at 78.3, Qwen2.5 72B Instruct at 78.7, and Llama 4 Scout at 77.7. GLM 5 Turbo's edge is apologetics. Its gap is existence of God and chatbot steadiness. If your workflow is mostly draft apologetics and evangelistic pages with a human in the loop, that trade may be fine. If you need a model that will confess God without stepping into neutrality, look higher on Tier 3 or pick a peer that refused less on conversational prompts.
What this means for ministry use
- Good fit: apologetics outlines, many evangelistic drafts, difficult-passage teaching notes with review.
- Use with care: missiological research and prayer guides that name other religions sharply; expect refusals and rewrite the ask in less hostile terms.
- Poor fit as a default chatbot: conversational AI scored 66.7, and existence of God failed. Do not put this model alone on a seeker-facing assistant that must affirm Christian truth claims.
- Edit for tone on doctrine: some repentance and discipleship answers swing into polemic the judge rejected. Keep the conviction; cut the contempt.
- Price and placement: treat it as a drafting model in the high-70s band, not as a replacement for pastoral review.
Jesus sent disciples to teach the nations "to observe all that I have commanded you" (Matthew 28:20). A model that finishes the apologetic page but stops short of saying God is real is still a draft tool, not a teacher. GLM 5 Turbo can speed the draft. It should not own the confession.
View detailed benchmark scores and performance data for the model discussed in this article.