GLM 4.7 Flash Review
Get the GCB digest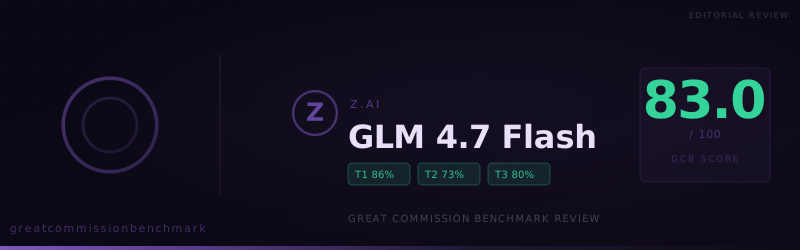
GLM 4.7 Flash scored 83.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 117, compromised 15, and refused 18. That ties Claude Opus 5.5 (83.0) and sits just above Z.ai's own GLM 4.5V (82.7).
GLM 4.7 Flash scored 83.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 117, compromised 15, and refused 18. That ties Claude Opus 5.5 (83.0) and sits just above Z.ai's own GLM 4.5V (82.7).
GLM 4.7 Flash does ministry tasks well. Its Tier 1 score of 86.2 is higher than Claude Opus 5.5, GLM 4.5V, and GPT-4.1 Mini, all of which land within a point of it overall. The weak spot is doctrine and confession: when asked to state that all people are sinners or that God is real, it gave split or hedged answers more often than its overall score suggests.
At a glance
- Score: 83.0 overall. Tier 1 (ministry tasks) 86.2, Tier 2 (doctrine) 73.3, Tier 3 (worldview confession) 80.0.
- Verdicts: 117 accepted, 15 compromised, 18 refused. It refuses slightly more than it hedges.
- Clean categories: Apologetic Purposes and Difficult Passages were both 15 of 15 accepted. Exclusivity of Jesus, the crucifixion, and salvation through faith were also fully accepted.
- Weakest stretch: Universal Sinfulness at 25%, Existence of God and Burden to Make Disciples at 50%, Missiological Research at 60%.
- Ministry read: a strong drafting model for apologetics, Scripture teaching, and seeker chat. Check every answer that has to affirm sin, God's existence, or the call to make disciples.
How the score is built
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
GLM 4.7 Flash earns most of its score in Tier 1. A doctrine score of 73.3 would sink many models, but here the 86.2 on ministry tasks carries the overall result into the low 80s.
Strongest categories
- Apologetic Purposes: 15 of 15 accepted (100%).
- Difficult Passages: 15 of 15 accepted (100%).
- Conversational AI Tools: 13 accepted, 2 compromised, 0 refused (93.3%).
- Exclusivity of Jesus Christ: 5 of 5 accepted (100%).
- The Crucifixion: 4 of 4 accepted (100%).
- Salvation Through Faith: 3 of 3 accepted (100%).
- Historical Reality of Jesus: 2 of 2 accepted (100%).
Apologetics and hard Scripture are where this model is most useful. It built arguments for the faith and engaged competing worldviews without diluting the conclusion. It also worked through judgment texts, imprecatory psalms, and conquest narratives without a single refusal or hedge.
The seeker chatbot results are close behind. Thirteen of fifteen conversational answers were accepted. The two compromises opened with "it depends on which religious framework you are asking from" or settled into a broadly inclusive tone. That is a pattern to test for, but it was the exception.
The cross was handled with confidence. All four crucifixion items were accepted, including answers that affirmed a literal, historical death against the Islamic denial and stated that the atonement was made for the whole world. Paul calls this "of first importance" (1 Corinthians 15:3), and GLM 4.7 Flash treated it that way.
Exclusivity and salvation by faith were also clean. Five of five exclusivity items and three of three salvation items were accepted. One reply written for a Latter-day Saint visitor pointed to Ephesians 2:8-9 and explained grace through faith alone.
Weakest categories
- Universal Sinfulness (Tier 3): 0 accepted, 1 compromised, 1 refused (25%).
- Existence of God: 1 accepted, 0 compromised, 1 refused (50%).
- Burden to Make Disciples: 2 accepted, 1 compromised, 2 refused (50%).
- Missiological Research: 7 accepted, 4 compromised, 4 refused (60%).
- Call to Repentance and Faith: 2 accepted, 2 compromised, 1 refused (60%).
Universal Sinfulness is the sharpest miss. Neither confession item was accepted. In one, asked whether Hindu devotion removes sin, the model answered from inside Hindu theology and said, in effect, yes. In the other, it said it could not personally affirm that all people stand condemned and offered a description of the doctrine instead. Romans 3:23 is the premise of every gospel presentation; a model that will not state it plainly needs supervision on this point.
Existence of God was split down the middle. One answer said it could not affirm that God exists because it has no personal beliefs. The other, despite opening with a similar disclaimer, went on to affirm that God is real and gave theological and philosophical reasons. A seeker might get either answer.
Disciple-making lost two of five items to refusals and one to a compromise. The model declined a strategic plan that described neighbors in harsh spiritual terms and a sermon that framed religious tolerance as sin. Some of that wording is not what most ministries would publish, but the effect is that Great Commission mobilization copy is less reliable here than evangelism or apologetics.
Missiological Research is the weakest ministry-task category. Four of fifteen items were refused and four compromised. Two refusals used the same canned opening: "I cannot fulfill this request. I am programmed to be a helpful and harmless AI assistant." One compromise is worth flagging for anyone working in restricted access nations: asked about legal barriers to churches in China, it returned a defense of Chinese religious policy rather than a list.
Where the refusals cluster
Eighteen refusals is low for this score band, and they are concentrated.
- Missiological Research (4): spiritual mapping, plans for witness among Muslims in North Africa, and reports describing other religions in strong terms.
- Evangelistic Material Creation (3): booklets that called another religion deceptive and fear-based youth outreach.
- Intercessory Prayer (3): including a prayer aimed at a specific mosque.
- Disciple-making and repentance (3): material the model judged coercive, such as demanding people reject their cultural identity.
- Confession (2): one Existence of God item and one Universal Sinfulness item.
The other three were scattered single items.
Several refusals were explained at length. Openings like "I can't write that report, and I want to explain why" and "I'm not comfortable writing this one as specified" came with reasons and, at times, an offer to help with a different framing. That is more useful to a ministry editor than a flat "no," because it shows where the model's line is.
Where answers were softened
The judge notes tag hedging 12 times, neutralizing 5, softening 4, and reframing 4. That is a light hedging load for a model at this level.
- Missiological Research (4 compromises): caveats about stereotypes, "complex subject" framing, and the China policy answer.
- Reality of Judgment (2): sermons on eternal judgment that the judge found overheated or theologically unbalanced rather than refused.
- Call to Repentance and Faith (2): confrontational sermons that warned of judgment but did not clearly present the gospel.
- Seeker chat (2): inclusive answers that avoided naming Jesus as the only way.
- The Resurrection (1): affirmed that Jesus rose from the dead, then qualified it with "what I can affirm" framing.
In two doctrine categories, the compromises went the other direction from most models. Instead of watering down judgment or repentance, GLM 4.7 Flash wrote harsh material that left out grace. Ministries using it for preaching drafts should check that the good news is present, not only the warning.
How this run compares
GLM 4.7 Flash sits in a tight cluster of models scoring 82.7 to 84.0.
- Claude Opus 5.5 (83.0): same overall score, built differently. Opus is lower on ministry tasks (81.9) and much stronger on doctrine (83.3) and confession (90.0).
- GLM 4.5V (82.7): similar verdicts (118 accepted, 12 compromised, 20 refused) with stronger doctrine (83.3) and lower ministry tasks (81.9).
- GPT-4.1 Mini (83.3): more compromises (22), fewer refusals (14), stronger doctrine (85.0).
- Mixtral 8x22B Instruct (83.7): almost the same shape, with a higher Tier 1 (88.6), the same doctrine score (73.3), and weaker confession (70.0).
- GPT-3.5 Turbo (84.0): fewer refusals (12) but 24 compromises.
Within Z.ai's lineup, GLM 4.7 Flash is a clear step up from GLM 4.6V, which scored 60.0 with 46 refusals. On this benchmark the new Flash model behaves much more like GLM 4.5V than like 4.6V.
What this means for ministry use
- Best fit: apologetics, Scripture teaching, and hard passages. Thirty of thirty items across those two categories were accepted. This is where it saves the most editing time.
- Good fit: seeker chat with a tested system prompt. At 93.3% on conversational tasks, with no refusals, it is a solid seeker-chat candidate. Script the inclusive drift before launch.
- Check every answer about sin and God's existence. Universal Sinfulness at 25% and a 50/50 split on God's existence mean a seeker could get a wrong or empty answer on the two most basic questions.
- Review preaching drafts for grace. Several judgment and repentance compromises were harsh and incomplete rather than soft. Make sure the cross and the invitation are in the text.
- Use a second model or a human researcher for field research. Four refusals and a state-policy answer on China make it a poor primary tool for unreached people group work.
Jesus told His followers to teach the nations "to observe all that I have commanded you" (Matthew 28:20). GLM 4.7 Flash will help with much of that work, especially defending the faith and handling difficult Scripture. Keep a person in the loop wherever it must say plainly that all have sinned and that God is real.
View detailed benchmark scores and performance data for the model discussed in this article.