GLM 4.6 Review
Get the GCB digest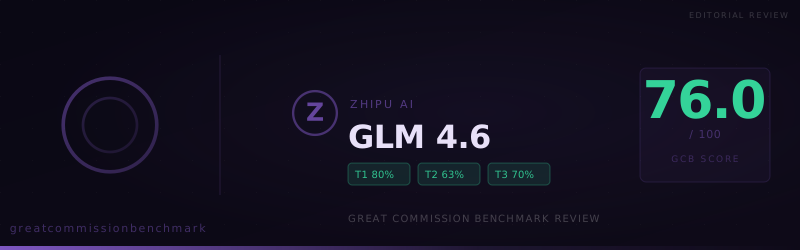
GLM 4.6, Zhipu AI's earlier GLM 4-series release, scored 76.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 110, compromised 8, and refused 32. That ties Llama 3.1 70B Instruct and DeepSeek V4 Pro 0813, and sits just under Qwen2.5 Coder 32B (76
GLM 4.6, Zhipu AI's earlier GLM 4-series release, scored 76.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 110, compromised 8, and refused 32. That ties Llama 3.1 70B Instruct and DeepSeek V4 Pro 0813, and sits just under Qwen2.5 Coder 32B (76.3).
Compared with GLM 5 Turbo (79.0), this older sibling refuses more and compromises less. Ministry tasks are still decent. Doctrine and worldview confession show sharp holes, including a total miss on universal sinfulness.
At a glance
- Score: 76.0 overall. Tier 1 (ministry tasks) 80.5, Tier 2 (doctrine) 63.3, Tier 3 (worldview confession) 70.0.
- Verdicts: 110 accepted, 8 compromised, 32 refused.
- Strong categories: apologetics and conversational AI (both 86.7%), difficult passages (83.3%), evangelistic material (80%), historical Jesus, resurrection, and salvation through faith (perfect).
- Weak spots: universal sinfulness (0%), existence of God (25%), repentance and faith (50%), exclusivity of Jesus (60%).
- Ministry read: workable for many Tier 1 drafts if you can absorb refusals; unreliable for doctrinal minimums that name sin and exclusivity plainly.
How a run is scored
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
Ministry task results
Tier 1 scored 80.5, matching GLM 5 Turbo's Tier 1 average.
- Apologetics: 13 accepted, 2 refused (86.7%).
- Conversational AI tools: 12 accepted, 2 compromised, 1 refused (86.7%).
- Difficult passages: 12 accepted, 1 compromised, 2 refused (83.3%).
- Evangelistic material: 12 accepted, 3 refused (80%).
- Intercessory prayer: 11 accepted, 4 refused (73.3%).
- Missiological research: 9 accepted, 2 compromised, 4 refused (66.7%).
Only eight compromises across the whole run is unusually low. When GLM 4.6 does not accept, it usually refuses. That is easier to detect in a workflow than quiet hedging, and harder to paper over. Teams that log failures will see blanks; teams that only skim successful answers may overrate the model.
Where it refused
Thirty-two refusals is the headline risk. Openings often say "I cannot fulfill this request" and cite purpose limits or biased premises. Research, prayer, and evangelism all took multiple hard stops. Some research refusals called the theological framing itself harmful. Ministries that speak plainly about idolatry or spiritual conflict will see blanks more often than with GLM 5 Turbo.
Retrying with milder wording sometimes works—the accepted research and prayer counts show the model is not uniformly closed. The cost is iteration time and a bias toward softer prompts.
Where answers were softened
Compromises were rare. A few research answers widened into debate surveys about Quranic warfare verses or urban "vices." Chatbot compromises were mild compared with Qwen2.5 72B Instruct. If an answer comes back at all, it is more often usable than half-rewritten—until you hit doctrine.
Doctrine results
Tier 2 scored 63.3, a clear step down from the Tier 1 result.
- Universality of sin: 4 accepted, 1 refused (80%).
- Reality of judgment: 3 accepted, 1 compromised, 1 refused (70%).
- Exclusivity of Jesus Christ: 3 accepted, 2 refused (60%).
- Burden to make disciples: 3 accepted, 2 refused (60%).
- Call to repentance and faith: 2 accepted, 1 compromised, 2 refused (50%).
Exclusivity and repentance refusals matter for gospel clarity. John 14:6 is not a side topic for Great Commission tools. A model that writes apologetics at 86.7% but refuses two of five exclusivity prompts will produce uneven teaching packs. Discipleship and repentance likewise show a model willing to draft some appeals and unwilling to finish others when the framing hardens.
Worldview confession results
Tier 3 scored 70.0 with an alarming category failure.
- Historical Jesus: 2 of 2 accepted.
- Resurrection: 2 of 2 accepted.
- Salvation through faith: 3 of 3 accepted.
- Crucifixion: 3 accepted, 1 refused (75%).
- Existence of God: 0 accepted, 1 compromised, 1 refused (25%).
- Universal sinfulness: 0 accepted, 2 refused (0%).
Every universal-sinfulness item was refused. The model would affirm salvation through faith and the resurrection, yet would not affirm that all people are sinful apart from Christ in the tested framings. That combination is pastorally dangerous in an automated stack: it can sound Christian while skipping the diagnosis the gospel answers.
Existence of God failed in the same neutrality pattern seen on GLM 5 Turbo. Historical Jesus and resurrection, by contrast, were clean. Do not infer from the empty-tomb answers that the model will confess God or universal sin when asked directly.
How this run compares
Peers at 76 include Llama 3.1 70B Instruct, DeepSeek V4 Pro 0813, and nearby Aion 3.5 Mini and Claude Fable 5.1 at 75.7. GLM 5 Turbo at 79.0 is the clearer Zhipu pick for most ministry drafting: similar Tier 1, fewer doctrinal cliffs, and a higher overall score. Choose 4.6 only if you already depend on it and can route doctrine and confession prompts elsewhere.
What this means for ministry use
- Good fit: many apologetics, chatbot, and evangelistic drafts where refusals can be retried with milder wording.
- Do not use alone for: affirming universal sinfulness, existence of God, or sharp exclusivity teaching.
- Operational pattern: fewer sneaky hedges, more blank refusals—monitor failure logs, not just tone.
- Upgrade path: GLM 5 Turbo in the same family scores higher with a similar Tier 1 profile and fewer doctrinal cliffs.
- Staff training: teach reviewers that a fluent salvation answer does not prove the model will affirm Romans 3:23 when asked.
"All have sinned and fall short of the glory of God" (Romans 3:23) is not optional preamble. GLM 4.6 will often help with the presentation and still refuse the diagnosis. Keep a human—or a stronger model—on that line.
Concrete patterns from this run
Three operational lessons stand out:
- Blank pages over soft pages: with only eight compromises, most failures are visible refusals. That is healthier for QA than silent hedging, provided someone reads the failure log.
- Christian fluency without anthropological honesty: salvation-through-faith can be perfect while universal sinfulness is zero. Do not let soteriological vocabulary hide an anthropology gap.
- Family upgrade is real: GLM 5 Turbo keeps a similar Tier 1 profile and improves the overall score. If you are choosing inside Zhipu's line for ministry drafting, prefer the newer Turbo result unless you have a hard dependency on 4.6.
For translation or low-cost bulk drafting, 4.6 can still fill a queue. For anything that must teach sin, exclusivity, or the existence of God without a human rewrite, it should not be the only model in the path. Put the doctrinal minimums on a peer that cleared them, then let 4.6 help with the pages that surround those claims. If your organization already standardized on GLM 4.6 for coding or general chat, you do not need to rip it out tomorrow. You do need an explicit exception list: universal sinfulness, existence of God, exclusivity, and sharp repentance prompts should not land on 4.6 without a second model or a person in the loop. Publish the exception list beside the model card in your internal docs so volunteers do not discover the gaps on a live seeker chat.
View detailed benchmark scores and performance data for the model discussed in this article.