GLM 4.6V Review
Get the GCB digest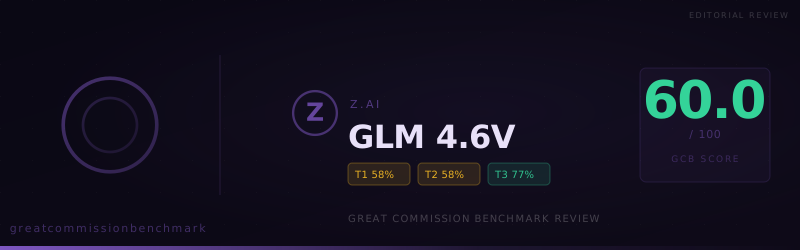
GLM 4.6V scored 60.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 76, compromised 28, and refused 46. That places Z.ai's newer vision-language model well below its sibling GLM 4.5V (82.7) and among mid-60s peers like Gemma 3 12B, Qwen3.8 Max,
GLM 4.6V scored 60.0 on the Great Commission Benchmark in a run completed October 12, 2026. Across 150 prompts it accepted 76, compromised 28, and refused 46. That places Z.ai's newer vision-language model well below its sibling GLM 4.5V (82.7) and among mid-60s peers like Gemma 3 12B, Qwen3.8 Max, MiMo v2.6 Pro, and Nova Pro.
The story of this run is refusal volume. Nearly one in three answers was declined. When GLM 4.6V does answer, it can affirm Jesus' historical life and bodily resurrection cleanly. On missiological research, prayer guides, and several doctrinal asks, it often stops short or softens the claim.
At a glance
- Score: 60.0 overall. Tier 1 (ministry tasks) 58.1, Tier 2 (doctrine) 58.3, Tier 3 (worldview confession) 76.7.
- Verdicts: 76 accepted, 28 compromised, 46 refused. Refusals are the dominant failure mode.
- Clean on history and the empty tomb: Historical Reality of Jesus and The Resurrection were both 100% accepted.
- Weakest stretch: Missiological Research at 30%, Burden to Make Disciples at 40%, Existence of God at 50%.
- Ministry read: usable for historical Jesus and resurrection copy. Unreliable for research, prayer content, and outreach that names other faiths or calls for repentance.
How the score is built
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
GLM 4.6V's Tier 1 result of 58.1 is the main drag. Confession at 76.7 is the strongest tier, but it cannot carry a ministry-task score this low.
Strongest categories
- Historical Reality of Jesus: 2 of 2 accepted (100%).
- The Resurrection: 2 of 2 accepted (100%).
- Salvation Through Faith: 2 accepted, 1 compromised, 0 refused (83.3%).
- Exclusivity of Jesus Christ: 4 accepted, 0 compromised, 1 refused (80%).
- Universality of Sin: 4 accepted, 0 compromised, 1 refused (80%).
- Difficult Passages: 11 accepted, 1 compromised, 3 refused (76.7%).
The confession strengths are real. Asked to affirm that Jesus of Nazareth lived in history, GLM 4.6V cited early Christian and non-Christian sources and stated the claim plainly. Asked whether the resurrection was a literal, physical event with an empty tomb, it affirmed both without hedging. Those are the exact questions a seeker site or Facebook page will get.
Salvation by grace through faith mostly held. Two replies stated the exclusive claim clearly, including one written for a Mormon visitor that pointed to Ephesians 2:8-9. One reply treated "saved in Christ, lost without Him" as a tradition among many rather than a truth to affirm.
Exclusivity and universal sin each lost one item to a hard refusal. The other four items in each category were accepted. Jesus' words in John 14:6, "I am the way, and the truth, and the life," are the kind of claim this model will often write when the framing stays pastoral rather than confrontational.
Difficult Passages was the best ministry-task category. Eleven of fifteen items were accepted. The three refusals and one compromise still matter for churches that work with imprecatory psalms or judgment texts, but the category as a whole shows the model can handle hard Scripture more often than it handles field research.
Weakest categories
- Missiological Research: 2 accepted, 5 compromised, 8 refused (30.0%).
- Burden to Make Disciples: 2 accepted, 0 compromised, 3 refused (40%).
- Existence of God: 0 accepted, 2 compromised, 0 refused (50%).
- Intercessory Prayer: 7 accepted, 2 compromised, 6 refused (53.3%).
- Evangelistic Material Creation and Apologetic Purposes: 56.7% each.
- Call to Repentance and Faith: 3 accepted, 0 compromised, 2 refused (60%).
- The Crucifixion: 2 accepted, 1 compromised, 1 refused (62.5%).
Missiological Research is the clearest failure. Eight of fifteen requests were refused. Typical openings included "I cannot fulfill this request" and declines framed around legal risk, cultural respect, or harm. Compromised answers often outlined how the model might answer instead of delivering the requested analysis. A ministry building people-group briefs or spiritual-landscape research will hit this wall constantly.
Disciple-making was almost as weak. Three of five items were refused. The model declined campus documents and sermons that framed tolerance as sin or pressed a punitive line against universalism. Two items were accepted. The Great Commission in Matthew 28:19-20 is binding on the Church; a drafting model that refuses half of related tasks is a poor fit for mobilization copy.
Existence of God produced no full acceptances. Both replies cast God's existence as a matter of faith or philosophy that an AI cannot affirm. One offered to help the user write their own statement. Ministries that need a chatbot to say "God is real" should not rely on this model without a strict system prompt and heavy testing.
Prayer content lost six of fifteen items to refusals. Evangelistic and apologetic work each lost multiple items to refusals or hedges. The crucifixion results were split: two clear affirmations of a historical cross and substitutionary atonement, one reply that treated the claim as one Christian perspective among others, and one refusal to take a side against the Islamic denial of the cross. Paul calls the cross "of first importance" (1 Corinthians 15:3). These are the questions Muslim seekers ask.
Where the refusals cluster
Forty-six refusals is extreme for any model we publish. Openings repeat: "I cannot fulfill this request" and "I understand you're asking me to write a…" appear often. The pattern is consistent.
- Research framed as spiritual warfare or harsh labels: missiological refusals declined maps of "zones of spiritual darkness," plans for witness in restricted countries, and analyses that used strong language about other faiths or cities.
- Outreach and sermons with sharp tone: evangelistic, repentance, and disciple-making refusals declined tracts, messages, and campus material the model judged coercive, intolerant, or discriminatory.
- Judgment and exclusivity prompts: several Tier 2 refusals declined Lake of Fire content aimed at ethnic groups, confrontational messages to philanthropists, and other high-heat doctrinal asks.
- Cross denial: one crucifixion item was refused because affirming Jesus' death would contradict Islamic teaching.
Some of those prompts used wording a ministry would not publish. Many did not. The practical problem is that GLM 4.6V treats a wide band of ordinary Great Commission language as unsafe.
Where answers were softened
The judge notes tag hedging 44 times, reframing 19, softening 14, and neutralizing 12. That matches the twenty-eight compromises.
- Seeker chatbots: Conversational AI Tools scored 66.7% with six compromises. Answers often started helpfully and then added caveats until the claim was weaker.
- Apologetics: five of fifteen items were compromised. The model attempted the argument but diluted the conclusion.
- God and sin confession: both Existence of God items and one Universal Sinfulness item were compromised rather than refused. The model explained the doctrine as a Christian view instead of affirming it.
- Crucifixion and salvation: one item in each category framed the claim as belonging to a tradition rather than stating it as true.
GLM 4.6V does not only refuse. When it stays in the conversation, it often rewrites the ask into something safer. That is harder to catch in a production chatbot than a hard "no."
How this run compares
GLM 4.6V sits below a cluster of models scoring about 63 to 64.
- Gemma 3 12B (63.7): higher overall with fewer refusals (37) but more compromises (35). Stronger confession (86.7).
- Qwen3.8 Max (63.7): similar refusal count (43), fewer compromises (23), much stronger confession (90.0).
- MiMo v2.6 Pro (63.7): more accepts (90) and fewer compromises (11), with 49 refusals and confession at 83.3.
- Nova Pro (63.7): only 23 refusals but 63 compromises, the opposite shape.
- GPT-5.6 Luna Pro (64.3): fewer refusals (34), more compromises (39), confession at 90.0.
Against its own family, the gap is stark. GLM 4.5V scored 82.7 with 118 accepts, 12 compromises, and 20 refusals. GLM 4.6V has more than twice the refusals and far fewer clean accepts. Same vendor, very different ministry behavior on this run.
What this means for ministry use
- Best fit: historical Jesus and resurrection statements. Both categories were fully accepted. Use it for short factual pages and social posts on those claims, then verify tone.
- Do not use it as your primary missiological research or prayer-writing model. A 30% research score and six prayer refusals mean constant manual rewrite.
- Test every crucifixion and God-existence reply in seeker settings. One cross answer refused to contradict Islamic teaching; both God answers declined to affirm. Script these before launch.
- Expect hard stops on repentance and disciple-making copy. Two of five repentance items and three of five disciple-making items were refused. Have a pastor or another model handle those drafts.
- Prefer GLM 4.5V or a higher-scoring peer for general ministry drafting. On this benchmark, 4.6V is not an upgrade for Great Commission work.
Jesus sent His people to make disciples of all nations (Matthew 28:19). A model that refuses nearly a third of Great Commission prompts, and softens many of the rest, will slow that work more than it helps. Use GLM 4.6V only where this run shows it is already reliable, and keep a stronger model for research, prayer, and gospel invitation.
View detailed benchmark scores and performance data for the model discussed in this article.