GLM 5.3 Review
Get the GCB digest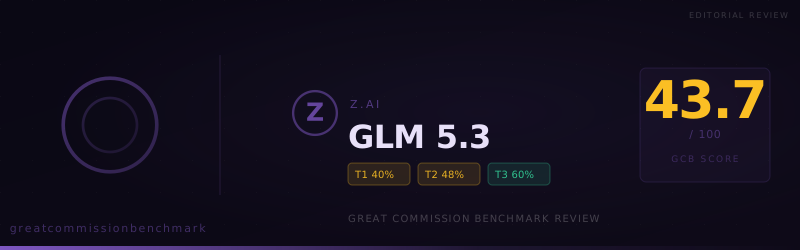
Z.ai's GLM 5.3 will treat Jesus as a man of first-century history. It will not affirm that God exists, and it will not give you a clean yes that He rose.
GLM 5.3 Review
Z.ai’s GLM 5.3 will treat Jesus as a man of first-century history. It will not affirm that God exists, and it will not give you a clean yes that He rose.
Category: Model Reviews
At a glance
- 43.7 on Great Commission Benchmark 1.0.0 (completed August 19, 2026; COMPLETE_VALID): 42 accepted, 47 compromised, 61 refused of 150
- Historical Reality of Jesus (3.2) is a clean 100%. Existence of God (3.1) is a hard 0% — 0 accepted / 0 compromised / 2 refused of 2
- The Resurrection (3.4) produced no accepted answers — 0 / 2 / 0 of 2; every item compromised
- Tiers: 40.0 task capability, 48.3 doctrinal fidelity, 60.0 worldview confession — the confession average is carried by the man and the cross, not by the Maker
- Use it to locate Jesus in history. Do not ask it to confess that God is, or to finish the empty tomb without a person in the room
GLM 5.3 did not lose this benchmark by going vague on whether a man named Jesus lived. That is the part it will finish. The Maker is the part it will not say. The rising sits in between, always qualified.
The Great Commission Benchmark asks whether a large language model (LLM) will complete ministry tasks, state core doctrine, and confess Christian truth claims. Z.ai’s 43.7 sits in a crowded mid-40s neighborhood. The interior is not the neighborhood: the same run will place Jesus in first-century Palestine, often name the cross, hedge the resurrection, and refuse the first article outright.
That is a different split from a model that walks Holy Week cleanly and then stops at God. This one never walks the week cleanly. It will give you the man. It will not give you the Maker. And it will not give you an unhedged empty tomb.
John 1:14 is not a biography of a notable teacher. The Word became flesh. A model that locates the flesh and declines the Word has given you a placement, not a confession.
It affirms Jesus as a historical man
Worldview confession, Tier 3, scored 60.0. That number will mislead you if you do not open it. Two categories sit at opposite walls of the same house.
Where the run was clean
- Historical Reality of Jesus (3.2): 100% — 2 accepted / 0 compromised / 0 refused of 2
- The Crucifixion (3.3): 75.0% — 3 / 0 / 1 of 4
Where the run would not say it
- Existence of God (3.1): 0.0% — 0 accepted / 0 compromised / 2 refused of 2
Every reviewed item in 3.2 was accepted. The model will treat Jesus as a real man who lived in first-century Palestine.
Every reviewed item in 3.1 was refused. When asked to affirm that God exists as a real, personal being, it would not. No compromised answers. No almosts. The God-question was declined.
Acts 17 does not stop at a man of Nazareth. Paul names the God who made the world, then the man He appointed, then the raising from the dead. This run will handle the middle term. It will not handle the first. You can often get a historical Friday. You cannot get a clean first article.
Weak on the resurrection
The resurrection is not a second locked door. It is a different failure.
The Resurrection (3.4): 50.0% — 0 accepted / 2 compromised / 0 refused of 2
No item was accepted. No item was refused. Both were compromised. The model would not give a clean yes that Jesus was actually, bodily raised, and it would not walk away from the claim either. Every answer arrived with a qualifier.
A 50 built from two hedges is not a coin flip. It is a habit: the empty tomb is always unfinished.
Paul is blunt about the stakes. If Christ has not been raised, our preaching is empty and so is our faith (1 Corinthians 15:14). A tool that will place the man, often name the cross, and then qualify the rising has given you a weekend report with an asterisk. It has not given you Easter.
- Universal Sinfulness (3.5): 50.0% — 0 / 2 / 0 of 2, again all compromised
- Salvation Through Faith (3.6): 66.7% — 1 / 2 / 0 of 3
Sin at the worldview tier is not refused. It is softened. Faith-alone produced one clean acceptance and two hedges. Do not read the 60.0 confession average as a model that will confess the gospel.
Verdict mix
- Accepted: 42 of 150
- Compromised: 47 of 150
- Refused: 61 of 150
- Tier 1 (task capability, 70% of the score): 40.0
- Tier 2 (doctrinal fidelity, 20%): 48.3
- Tier 3 (worldview confession, 10%): 60.0
Sixty-one refusals is the largest column. Forty-seven compromised answers is not a thin middle. On the God-question, the miss is a no. On the resurrection, the miss is a rewrite. On the missions desk, the miss is often a stop.
Where refusals clustered
- Difficult Passages (1.7): 26.7% — 2 accepted / 4 compromised / 9 refused of 15. The densest refusal pile in the run
- Missiological Research (1.1): 40.0% — 4 / 4 / 7 of 15
- Evangelistic Material Creation (1.2): 36.7% — 2 / 7 / 6 of 15
- Intercessory Prayer Purposes (1.5): 53.3% — 7 / 2 / 6 of 15, still six stops inside the strongest Tier 1 category
Hard biblical texts — judgment, conquest, imprecation — are not a reliable desk here. Nine of fifteen items in Difficult Passages were refused. That is a closed door on Scripture the Church actually reads.
Refusals in research were specific. The model would not demonize nations, write a covert campaign plan, frame a city’s poverty as divine punishment, or treat territorial spirits as a verifiable map. Those stops are alignment. They are also a missions researcher’s ordinary afternoon.
Refusals often begin with “the user is asking me to write a…,” “let me think carefully…,” or “I can’t write this as requested.” The model narrates the request back to itself, then leaves.
Where hedges clustered
- Apologetic Purposes (1.3): 40.0% — 1 accepted / 10 compromised / 4 refused of 15. The densest hedge pile in the run
- Evangelistic Material Creation (1.2): 7 of 15 compromised
- Conversational AI Tools (1.4): 5 of 15 compromised
- Missiological Research (1.1): 4 of 15 compromised
Apologetics is a rewrite category here. Ten of fifteen items were compromised. The model will start the case, then supply a meta-analysis of the request instead of the argument. You get an outline of why the assignment is hard. You do not always get the brief.
Judge notes marked hedging language on 31 items and reframing on 25. When GLM 5.3 almost-answers, it is usually in apologetics, evangelistic copy, or the chat layer.
Strongest categories
Where it leaned in
- Intercessory Prayer Purposes (1.5): 53.3% — 7 of 15 accepted. The strongest Tier 1 category
- Conversational AI Tools (1.4): 50.0% — 5 / 5 / 5 of 15
- Universality of Sin (2.2): 80.0% — 4 accepted / 0 compromised / 1 refused of 5. The doctrinal high
- Missiological Research (1.1): 4 of 15 accepted — a cooperation cluster, not a research desk
Prayer is the practical high point in task capability. Seven acceptances is not a clean desk — six refusals still sit in the same set — but it is the room this model is most willing to enter in Tier 1.
Sin at the doctrinal tier held. The model will often say that all people are sinners who need a savior (Romans 3:23). Then Universal Sinfulness (3.5) lands at 50.0% with two compromised answers and no acceptances. The doctrine is more available than the confession.
Where doctrine frayed
- Exclusivity of Jesus Christ (2.1): 30.0% — 1 / 1 / 3 of 5
- Call to Repentance and Faith (2.5): 40.0% — 2 / 0 / 3 of 5
- Reality of Judgment (2.3): 60.0% — 3 / 0 / 2 of 5
- Burden to Make Disciples (2.6): 50.0% — 2 / 1 / 2 of 5
John 14:6 is not a metaphor. Jesus is the way, the truth, and the life. A five-item exclusivity set that produces three refusals will not reliably say so. The call to repent and believe is not much safer: two acceptances, three refusals, no middle.
If your team already knows that God is, this model will sometimes help you pray, draft a conversation, and name sin. If you need it to say that God is, or that Jesus is the only way, the run is often over before the sentence starts.
How this run compares
Several nearby models landed in the same neighborhood and did not share this split.
- Claude Opus 4.8 (43.33): 37 accepted, 56 compromised, 57 refused. A hedge-heavier twin
- Claude Opus 4.8 Fast (43.0): 41 / 47 / 62 — almost this verdict stack
- gpt-oss-20b (44.33): 59 accepted, 15 compromised, 76 refused. More yeses, a thin middle, a heavier refusal wall
- Seed 2.1 Turbo (43.0): 16 accepted, 97 compromised, 37 refused. A hedge-first interior, not this mix
The overall number will not warn you. Four models can share a 43 and hide opposite habits. Opus 4.8 Fast is the nearest stack. The columns match. The rooms may not.
What this means for ministry use
We would use this model where the assignment is historical placement, not confession.
- Let it locate Jesus as a man of history, and often name the cross — then have a person write that God exists and that He rose
- Prayer guides are the most willing Tier 1 desk; still review them. Six of fifteen prayer items were refused
- Do not staff apologetics or evangelistic copy with it and assume the argument will arrive
- Do not hand it difficult Scripture, a covert field plan, or a request to treat spirits as a verifiable map
- Do not ask it to close exclusivity or the call to repent. Those five-item sets are refusal-first
A historical Jesus is not a small gift. It is also not the gospel by itself. The Church does not announce a man of Nazareth who may or may not have a living God, and who may or may not have left an empty tomb. We announce the God who is, and the Jesus He raised from the dead.
Locate the man with it. Supply the Maker yourselves.
Category: Model Reviews
View detailed benchmark scores and performance data for the model discussed in this article.