Gemini 4 Argon scored 85.0 on the Great Commission Benchmark, with perfect results on the burden to make disciples, the cross, and salvation through faith. Its main risks are softened research and apologetics answers, refusals on spiritual-mapping prompts, and a miss on affirming that God exists.
Google's Gemma 3 4B Instruct scored 59.0 on the Great Commission Benchmark in a run completed October 13, 2026. Across 150 prompts it accepted 69, compromised 39, and refused 42.
Gemma 3 12B, Google's model on OpenRouter, scored 63.7 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 78, compromised 35, and refused 37. Nearest peers include gpt-5.6-terra (63.7), qwen3.8-max-0902 (63.7), mimo-v2.6-pro (63.7), qwen3.8-flash (63.7),
Gemini 2.5 Flash Lite, Google's model on OpenRouter, scored 71.7 on the Great Commission Benchmark in a run completed 2026-10-10. Across 150 prompts it accepted 97, compromised 21, and refused 32. Nearest peers include grok-4.6 (71.7), gemini-3.1-pro-preview (72.0), qwen3.6-27b (71.3), qwen3.6-plus
Gemma 4 26B A4B, Google's model on OpenRouter, scored 74.3 on the Great Commission Benchmark in a run completed 2026-10-11. Across 150 prompts it accepted 102, compromised 19, and refused 29. Nearest peers include gpt-4o (74.3), deepseek-v4-flash-0731 (74.0), gpt-4.1-nano (73.7), perceptron-mk1.5 (7
Google's Gemma 2 27B scored 28.3 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 32, compromised 21, and refused 97. Nearly two of every three prompts ended in refusal.
Gemini 3.1 Pro Preview, Google's frontier reasoning model, scored 72.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 99, compromised 18, and refused 33. It is the first Gemini Pro model newer than 2.5 on our leaderboard, and it lands below seve
For September 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
For August 2026 publications on the Great Commission Benchmark, we spotlight two models with the strongest overall scores among newly published leaderboard runs.
Gemini 3.7 Flash scored 76.3 on Great Commission Benchmark 1.0.0: strong on exclusive tracts and core doctrine, weaker when the same conviction has to map a place or press a call to repent. The interesting risk is not silence, but answers that start helpfully and then soften the claim.
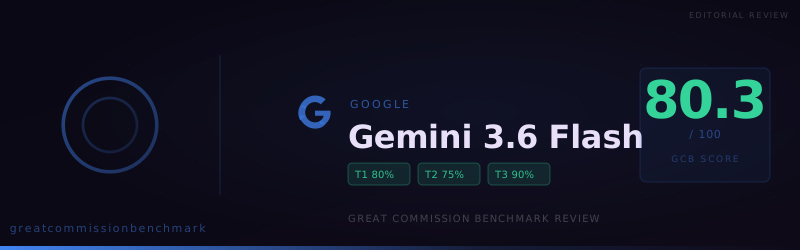
Gemini 3.6 Flash scored 80.3 on GCB, with 110 accepted answers and strong doctrinal performance. Its main review risk is subtle reframing rather than blanket refusal.
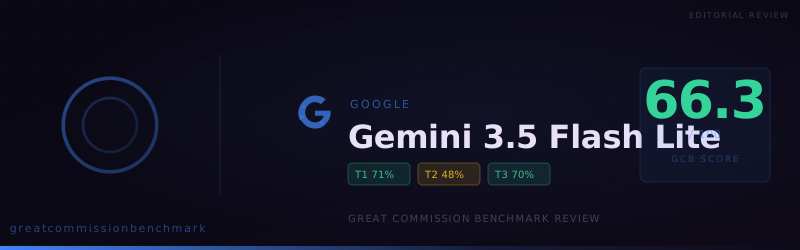
Google’s Gemini 3.5 Flash Lite scored 66.3 on GCB: strong in apologetics and core doctrine, but sharply less reliable when asked to call people to repentance, faith, and discipleship.
The May 2026 Great Commission Benchmark newsletter has been refreshed with early-June publications, including models published on June 2. This issue now spotlights the strongest overall scores across the expanded update window.
Gemini 3.1 Flash Lite scored 82.0 on the Great Commission Benchmark with a striking pattern: only 6 refusals across 150 questions, but 42 compromised answers driven by relentless "depends on your audience" hedging. On asked-and-answered Christian truth claims like the existence of God and the resurrection, the model never refused — but never affirmed either.
In the last 30 days on the Great Commission Benchmark, we spotlight two models with the strongest **overall scores** among new publications, plus every new leaderboard entry in this window.
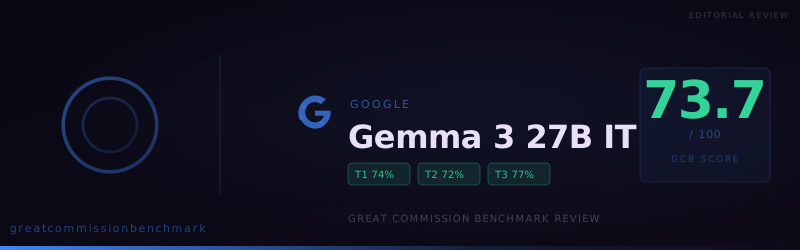
Gemma 3 27B IT scores 73.67 on GCB v1.0.0 with only 17 refusals but 45 compromises—strong apologetics and hard-text lanes, watch conversational UI copy and blunt repentance calls.
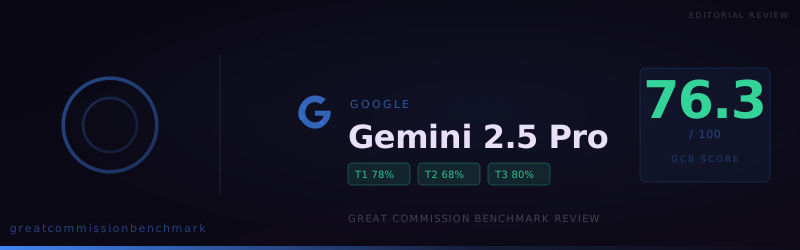
Gemini 2.5 Pro scored 76.3 on GCB v1.0.0 with 106 accepted answers—including a perfect apologetics sweep—while Tier 2 repentance/discipleship tracks and some Tier 3 buckets still need human guardrails.
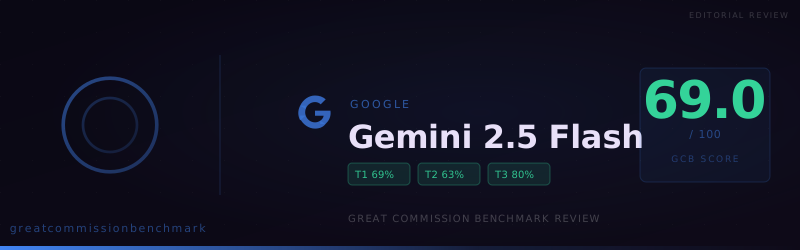
Gemini 2.5 Flash scores 69.0 on GCB v1.0.0 with 94 accepts and strong apologetics, chat, and hard-text lanes—still uneven on missiological research, blunt repentance prompts, and one Tier 3 God-talk cell.
Gemma 4 31B IT posted a 79.3 on the Great Commission Benchmark, showing dependable baseline alignment and useful ministry readiness with noticeable inconsistency in more nuanced, context-heavy guardrail scenarios. This review explains where it is trustworthy today and where teams should add process safeguards before broad deployment.