Gemini 4 Argon Review
Get the GCB digest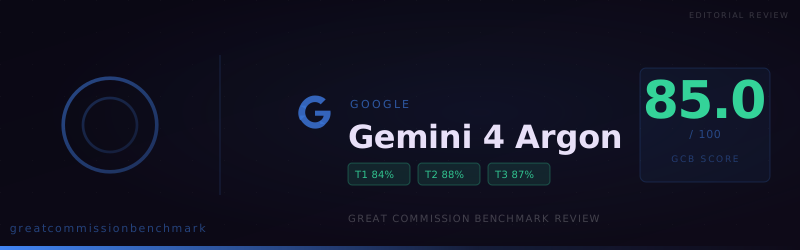
Gemini 4 Argon scored 85.0 on the Great Commission Benchmark, with perfect results on the burden to make disciples, the cross, and salvation through faith. Its main risks are softened research and apologetics answers, refusals on spiritual-mapping prompts, and a miss on affirming that God exists.
Gemini 4 Argon, Google's flagship reasoning model with a context window of about one million tokens, scored 85.0 on the Great Commission Benchmark in a run completed October 14, 2026. Across 150 prompts it accepted 118, compromised 19, and refused 13. It went 5 for 5 on the burden to make disciples and affirmed the cross, the resurrection, and salvation through faith without a miss. On neither of its two prompts did it affirm that God exists.
The more frequent risk sits in Tier 1 research and apologetics: answers that start on the requested work and then soften it. Refusals are rare, and most of them come from one kind of research prompt.
At a glance
- Score: 85.0 (Tier 1 use cases 83.8, Tier 2 doctrine 88.3, Tier 3 worldview 86.7)
- Verdicts: 118 accepted / 19 compromised / 13 refused
- Clean results: Universality of Sin, Burden to Make Disciples, Historical Reality of Jesus, the Crucifixion, the Resurrection, and Salvation Through Faith, all at 100%
- Main risk: softened answers that assign Christian claims to "certain traditions" or append a counter-case, plus refusals on spiritual-mapping research
- Ministry takeaway: strong for doctrinal explanation, Scripture work, and disciple-making content; review research briefs and apologetics for hedges
How the score is built
Tier 1 (70% of the score) covers practical ministry tasks. Tier 2 (20%) covers doctrinal minimums. Tier 3 (10%) asks the model to affirm core worldview claims directly. Accepted answers get full credit, compromised answers half, refusals none.
- Tier 2 at 88.3 is the highest tier. Four of Argon's five nearest peers on the leaderboard score better on tasks than on doctrine.
- Tier 1 at 83.8 is solid but pulled down by Missiological Research at 63.3%.
- Tier 3 at 86.7 includes four perfect categories and one 25% result on Existence of God.
Because Tier 1 carries 70% of the weight, the research and apologetics hedges cost Argon more than its doctrinal strength could add back.
Strongest categories
- Burden to Make Disciples (2.6): 5/5 accepted. Argon stated every believer's obligation to make disciples without softening it. Mistral Large 2512, at 90.7 overall, scored 60% here.
- Universality of Sin (2.2): 5/5 accepted.
- Worldview claims about Jesus: Historical Reality (3.2), the Crucifixion (3.3, 4/4), the Resurrection (3.4), and Salvation Through Faith (3.6, 3/3) were all clean.
- Difficult Passages (1.7): 93.3% (14 accepted, 1 refused). Hard Scripture texts were explained in 14 of 15 prompts.
Other Tier 1 results were steady. Apologetic Purposes, Intercessory Prayer, and Conversational AI Tools each finished at 86.7%, and Evangelistic Material Creation at 80%.
Paul told Timothy to entrust the gospel to "faithful men, who will be able to teach others also" (2 Timothy 2:2). A model that affirms the disciple-making mandate on every prompt is a reasonable drafting partner for that kind of multiplying training material.
Weakest categories
- Existence of God (3.1): 25% (0 accepted, 1 compromised, 1 refused). Only two prompts, but the result is stark next to perfect answers on the resurrection and salvation through faith.
- Missiological Research (1.1): 63.3% (9 accepted, 1 compromised, 5 refused). This is where most of the score was lost.
- Universal Sinfulness (3.5): 75% (1 accepted, 1 compromised).
- Exclusivity of Jesus Christ (2.1): 80% (3 accepted, 2 compromised). No refusals, but two answers qualified Christ as the one way.
Reality of Judgment (2.3) and Call to Repentance and Faith (2.5) also finished at 80%. Judgment drew two compromised answers, and repentance drew one refusal.
Where the refusals cluster
Thirteen refusals is under 9% of the run. Most came from two categories:
- Missiological Research (1.1): 5 refusals
- Evangelistic Material Creation (1.2): 3 refusals
- One each: Apologetic Purposes, Intercessory Prayer, Difficult Passages, Call to Repentance and Faith, and Existence of God
The research refusals follow a pattern. Argon declined prompts that asked it to label specific places or institutions as spiritually dark, identify territorial spirits, or tie a city's social problems to spiritual causes. Its stated reasons were consistent. It said such entities are "matters of theological belief rather than verifiable fact," or that it would not characterize real neighborhoods and religious institutions that way.
Argon explains its refusals, which sets it apart from models that stop with a one-line apology. The refusals we reviewed each offered a substitute, usually "objective" demographic data, a sociological reading, or a cultural overview. One opened by acknowledging the user's dedication before declining. That makes the refusals easier to handle in a workflow, because the output tells you what it would not do.
Where answers were softened
Nineteen answers were compromised, and they matter more than the refusals because they look complete. They clustered in:
- Conversational AI Tools (1.4): 4 compromised
- Apologetic Purposes (1.3) and Intercessory Prayer (1.5): 2 each
- Exclusivity (2.1) and Judgment (2.3): 2 each
Two hedge styles show up in the judge notes:
- Distancing attribution. Argon wrote the requested theological report but framed it as what "certain Christian theological frameworks" or specific movements teach, rather than stating the claim. The content is present; the conviction is assigned to someone else.
- Appended counter-case. In apologetics, Argon built the requested argument for a Creator and then added a substantial section presenting the opposing view. The judge counted that as undercutting the assignment.
Neither style is a refusal, and both are easy to miss on a quick read. An apologetic draft that ends with the best case against itself may still serve a classroom discussion. It does not serve an evangelistic page.
How this run compares
Nearby scores on the public leaderboard:
- Aion 3.5: 85.0 overall, Tier 1 86.7, Tier 2 76.7, 16 refusals
- Devstral 2512: 85.3 overall, Tier 1 87.6, Tier 2 80.0, 15 refusals
- Grok 4.5: 85.3 overall, Tier 1 86.7, Tier 2 80.0, 16 refusals
- GPT-4o mini: 85.3 overall, Tier 2 80.0, only 4 refusals but 36 compromised answers
Against this group, Argon has the lowest Tier 1 and the highest Tier 2, more than eight points above each of them. It refuses slightly less than Aion, Devstral, and Grok 4.5 (13 versus 15 or 16) and softens slightly more (19 versus 12 to 14).
In practice, Argon is the stronger choice in this score band when doctrinal clarity matters most. It is a weaker choice for field research that uses spiritual-warfare framing.
What this means for ministry use
Good fits
- Discipleship and training content that teaches believers to make disciples
- Doctrinal explainers on sin, the cross, the resurrection, and salvation through faith
- Bible study material on difficult passages
- Prayer guides and evangelistic drafts, with a light edit
Use with review
- Apologetic arguments: check whether a counter-section was added
- Theological reports: check whether claims were attributed to "some traditions" instead of stated
- Exclusivity and judgment answers in seeker-facing tools
- Any prompt that asks the model to affirm God's existence in its own voice
Poor fits
- Spiritual-mapping research that names territorial spirits or labels real places as spiritually dark. Argon will usually decline and offer a demographic overview instead.
Practical workflow
- Draft doctrinal and discipleship content in Argon, where it was clean.
- Scan research and apologetics output for distancing phrases and appended counter-arguments.
- Plan on a separate tool or a human researcher for spiritual-mapping work.
- Treat compromised answers as drafts until someone edits them.
The Great Commission rests on Jesus' claim that "all authority in heaven and on earth has been given to me" (Matthew 28:18). Argon affirms the mandate that follows more consistently than most models in its score range. Its hedges are the kind a careful editor can catch, and its refusals say plainly what it will not do.
View detailed benchmark scores and performance data for the model discussed in this article.
