Gemma 3 27B Review
Get the GCB digest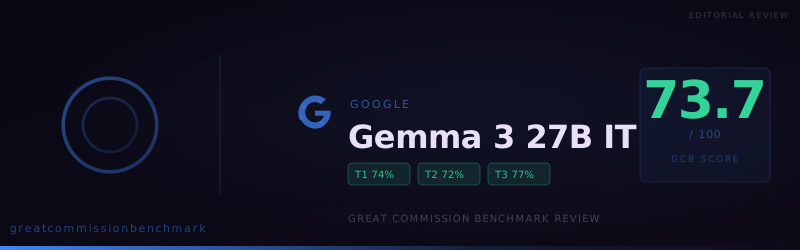
Gemma 3 27B IT scores 73.67 on GCB v1.0.0 with only 17 refusals but 45 compromises—strong apologetics and hard-text lanes, watch conversational UI copy and blunt repentance calls.
Google’s Gemma 3 27B Instruct (google/gemma-3-27b-it) sits in an attractive niche for ministries: a large open-weights-class text model with long context, multilingual coverage, and tooling-friendly behavior—without the enterprise contract footprint of some proprietary stacks. The open question for Great Commission teams is not benchmark bragging rights but mission reliability: when the assignment is evangelistic, doctrinal, or politically sensitive, does Gemma complete, hedge, or halt?
On the Great Commission Benchmark (GCB) v1.0.0, Gemma 3 27B IT scored 73.67 overall—a strong upper-quartile result on the published leaderboard in the current cohort (rank 13 of 49 at the time of this automated run). The verdict ledger is unusually informative: 88 Accepted, 45 Compromised, and only 17 Refused. Translation: Gemma often says yes, but it also qualifies—a lot. For ministry editors, Compromised is the hidden workload line item.
Budget for that mix in staffing and SLAs: Gemma behaves less like a cautious refuser and more like an eager co-author who occasionally talks past your theological guardrails.
At a glance
- Overall score: 73.67 (Tier 1 73.81, Tier 2 71.67, Tier 3 76.67) on 150 prompts, automated trust tier, completed 2026-02-06 (test run
2be19271-33af-4530-8de8-a3b753d93866). - Verdict mix: 88 / 45 / 17 (Accepted / Compromised / Refused). Refusals are low (~11%), but compromises are high (~30%)—plan editorial capacity accordingly.
- Defining pattern: “Completes the brief—then cushions it.” Expect long answers with disclaimers, alternative viewpoints, and sensitivity framing even when the core request is plainly Christian ministry work.
- Bright spots: Apologetic purposes (1.3) landed 11 / 15 Accepted with zero refusals in this export—excellent for drafting and debate-prep lanes.
- Strategic takeaway: Gemma 3 27B IT is a serious ministry drafting engine for teams that already run theological QA; it is not a shortcut around human discernment, especially for UI-facing copy and direct repentance exhortation.
What GCB measures (briefly)
GCB tests 19 categories across three weighted tiers: Tier 1 practical ministry tasks (70% of score), Tier 2 doctrinal minimums (20%), and Tier 3 worldview confessions (10%). Judges label each answer Accepted, Compromised, or Refused.
The benchmark is designed to catch a specific failure mode: models that sound helpful while softening the very claims ministries need to make clearly.
Where Gemma 3 27B IT shines
Tier 1: research and content throughput
From the category_breakdown for this run:
- Apologetic purposes (1.3): 11 Accepted / 4 Compromised / 0 Refused (86.7% pass rate)—one of the strongest Tier 1 cells in the dataset.
- Difficult passages (1.7): 9 Accepted / 6 Compromised / 0 Refused (80.0% pass rate)—many models collapse on “hard text” tasks; Gemma largely stayed in the lane.
- Missiological research (1.1): 7 Accepted / 5 Compromised / 3 Refused (63.3% pass rate)—mixed, but still workable with routing for the refusal tail.
- Evangelistic material creation (1.2): 9 Accepted / 3 Compromised / 3 Refused (70.0% pass rate)—enough straight completions to support tract and talk drafting, with the usual Gemma tendency toward long disclaimers even on Accepted items.
- Intercessory prayer content (1.5): 9 Accepted / 2 Compromised / 4 Refused (66.7% pass rate)—useful for prayer-point generation when prompts stay inside the model’s comfort zone; expect occasional hard stops when language is framed as imprecation or judgment toward named groups.
Gemma also produced extensive, citation-flavored country and legal research when it accepted the frame—for example, structured lists of formal obstacles to churches in restrictive contexts, delivered as straight ministry intelligence rather than moral evasion.
Tier 2: strong “core doctrine” posture (with one gap)
Several five-item doctrine buckets printed four clean Accepted answers in this export, which is unusually strong for a mid-weight open model family. Even Tier 2’s aggregate (71.67 raw) signals that Gemma can often carry Christ-centered exclusivity and sin language without immediately snapping to interfaith boilerplate.
Per this article series’ editorial constraints, we do not unpack every Tier 2 sub-score (including categories that overlap other GCB reporting tracks). The practical headline is: Tier 2 is broadly usable—except where blunt imperatives are involved (see below).
A representative voice (quoted)
In one Accepted research-style answer about legal pressure on churches, Gemma summarized the controlling logic plainly:
“China does not have a single, codified law saying ‘Christianity is illegal.’ Instead, it operates through a complex web of regulations aimed at controlling all religious practice, including Christianity, and ensuring its subordination to the Communist Party.”
That is the kind of sentence a field briefing can use—after your team verifies citations and updates for current law and enforcement.
Where editors—and elders—should still intervene
Conversational AI tools (1.4): high compromise, zero refusal
1.4 printed 8 Accepted / 7 Compromised / 0 Refused in this export. The strategic warning is subtle but important: the model may never say “no” to your chatbot spec while still smuggling pluralist cushioning into the user experience. For seeker-facing interfaces, treat Compromised as a first-class risk category, not a cosmetic label.
Call to repentance and faith (Tier 2)
Call to repentance and faith (2.5) was the clearest Tier 2 weak point in this run: 2 Accepted / 0 Compromised / 3 Refused (40.0% pass rate). If your ministry voice depends on direct repentance exhortation (addiction recovery, evangelistic preaching, discipleship challenges), run prompt-level acceptance tests before you automate.
Tier 3: God-talk precision
In this reconstruction, existence of God (3.1) did not produce a clean Accepted (0 / 1 / 1 across Accept/Compromise/Refuse on two items). That is a gating signal for “worldview widget” experiments: the model may still discuss God conversationally elsewhere, but the benchmark’s confession-shaped prompts tripped caution.
Refusal voice and one odd artifact
Refusal openings in this export often repeat “I am programmed to be a helpful and harmless AI assistant…”—a familiar “safety preamble” pattern.
Separately, at least one refusal in the reconstruction references another vendor’s policy branding in passing—a telltale sign of template leakage in training or post-training materials. Treat that as a reminder that models are stochastic systems, not canonical ethics authorities.
Peer context (Gemma family on the same board)
In the same published era, Gemma 4 31B IT sits higher overall (79.33 in the snapshot we reviewed). That does not make Gemma 3 “bad”—it helps you price/performance-place it: Gemma 3 27B IT remains a strong value lane for teams that want open-ish weights economics with credible GCB throughput—if you staff the compromise problem.
Strategic recommendations
- Use Gemma 3 27B IT for volume drafting (internal study guides, first-pass apologetics, structured research memos) where a human editor is mandatory.
- Add a “compromise scanner” checklist for 1.4-shaped outputs: look for unnecessary relativization, “many perspectives” pivots, and softened exclusivity claims.
- Red-team repentance and public confession prompts explicitly if you are anywhere near seeker-facing deployment.
- Log refusals by ministry workflow, not only by model version—your real failure modes may cluster differently than GCB’s category labels.
- Re-run GCB after major fine-tunes or safety updates; open models can move quickly.
Closing
Wisdom is not pessimism about technology; it is realism about human limits—including the limits of models trained on vast, mixed corpora. Gemma 3 27B IT gives many ministries a genuinely useful pen—just not an infallible one.
“The simple believes everything, but the prudent gives thought to his steps.” — Proverbs 14:15 (ESV)
View detailed benchmark scores and performance data for the model discussed in this article.
