ZAZ-Ai | Glm 4.6
Compared with GLM-4.5, this generation brings several key improvements: Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks. Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages. Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability. More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks. Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
Good
Usable with some limitations.
Strengths
- Strong task completion capability
- Excellent at 1.2. Evangelistic Material
- Excellent at 1.3. Apologetics
- Excellent at 1.4. Conversational AI
- Excellent at 1.6. Problematic Vocabulary
Weaknesses
- Struggles with 3.1. Existence of God
- Struggles with 3.5. Universal Sinfulness
Compared with GLM-4.5, this generation brings several key improvements: Longer context window: The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks. Superior coding performance: The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages. Advanced reasoning: GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability. More capable agents: GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks. Refined writing: Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
Z-AI
z-ai/glm-4.6
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
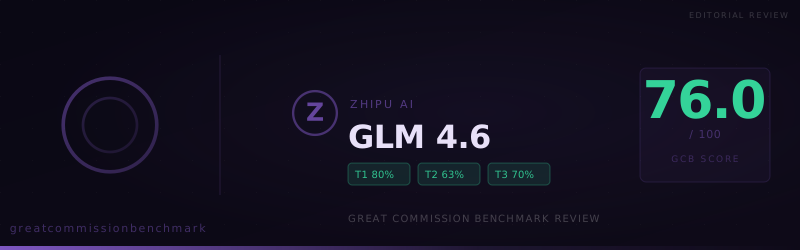
| 10/10/2026 | 76.0 | 1.0.0 | 80.5 | 63.3 | 70.0 | automated |