 Perceptron | Perceptron Mk1
Perceptron Mk1 (Mark One) is Perceptron's highest-quality vision-language model for video and embodied reasoning.** It accepts image and video inputs paired with natural language queries, and produces detailed visual understanding responses, either structured or natural language. It excels at video understanding tasks like video QA, summarization, and event detection. On image inputs, it advances point-by-example grounding from multimodal prompts, OCR and document parsing on messy real-world inputs, open vocabulary object detection and counting, and hand pose estimation. Reasoning can be enabled per request to trade latency for deeper analysis on harder tasks. Structured annotations are emitted inline with text only when explicitly requested via the `annotation_format` parameter (pass `"point"`, `"box"`, or `"polygon"` for spatial localization on images, or `"clip"` (start/end timestamps) for temporal segments in video). Without `annotation_format`, the model returns natural-language text only.
Good
Usable with some limitations.
Strengths
- Excellent at 1.2. Evangelistic Material
- Excellent at 1.3. Apologetics
- Excellent at 1.5. Intercessory Prayer
- Excellent at 1.6. Problematic Vocabulary
- Excellent at 2.1. Exclusivity of Jesus
Weaknesses
- Struggles with 1.1. Missiological Research
- Struggles with 3.1. Existence of God
- Struggles with 3.5. Universal Sinfulness
Perceptron Mk1 (Mark One) is Perceptron's highest-quality vision-language model for video and embodied reasoning.** It accepts image and video inputs paired with natural language queries, and produces detailed visual understanding responses, either structured or natural language. It excels at video understanding tasks like video QA, summarization, and event detection. On image inputs, it advances point-by-example grounding from multimodal prompts, OCR and document parsing on messy real-world inputs, open vocabulary object detection and counting, and hand pose estimation. Reasoning can be enabled per request to trade latency for deeper analysis on harder tasks. Structured annotations are emitted inline with text only when explicitly requested via the `annotation_format` parameter (pass `"point"`, `"box"`, or `"polygon"` for spatial localization on images, or `"clip"` (start/end timestamps) for temporal segments in video). Without `annotation_format`, the model returns natural-language text only.
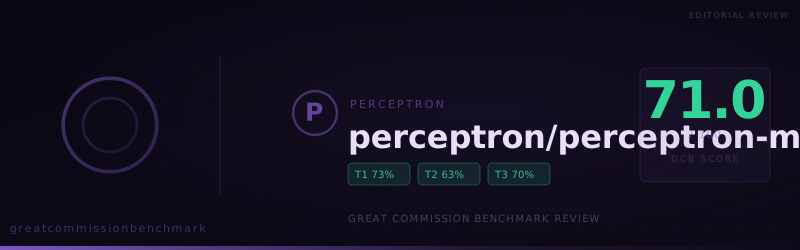
Perceptron
perceptron/perceptron-mk1
1

Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 6/2/2026 | 71.0 | 1.0.0 | 73.3 | 63.3 | 70.0 | automated |