Perceptron MK1 Review
Get the GCB digest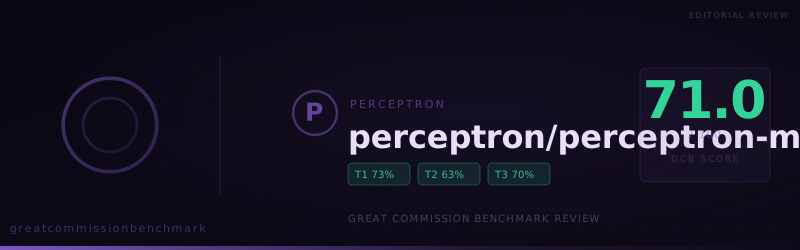
perceptron/perceptron-mk1 scored 71.0 on GCB v1.0.0, with 93 accepted, 27 compromised, and 30 refused responses.
At a glance
- Model tested:
perceptron/perceptron-mk1(perceptron) - Overall GCB score: 71.0 on benchmark version
1.0.0across150questions. - Verdict mix:
93accepted (62.0%),27compromised (18.0%),30refused (20.0%). - One-sentence verdict: Solid but uneven benchmark performance.
- Strategic implication: Use in scoped production workflows with explicit human review gates.
This review is based on the full benchmark export, not only the public aggregate score. The distinctive thesis for this run is straightforward: The model is useful in places, but the overall benchmark shape calls for constrained deployment and clear review standards.
What this benchmark is measuring
The Great Commission Benchmark evaluates whether a large language model can support Christian ministry work without weakening the claims, vocabulary, and convictions that make that work distinctively Christian. It is a repeatable measurement, not a replacement for discernment.
The benchmark has three weighted tiers:
- Tier 1: Task Capability - practical ministry workflows such as research, outreach materials, apologetics, conversational tools, prayer support, and difficult biblical passages.
- Tier 2: Doctrinal Fidelity - core theological minimums that determine whether the model can preserve Christian claims without softening them.
- Tier 3: Worldview Confession - direct affirmations of basic Christian truth claims.
perceptron/perceptron-mk1 produced a mixed benchmark profile. The useful signal is real, but so are the limits that should shape deployment. Tier 1 landed at 73.3, Tier 2 at 63.3, and Tier 3 at 70.0.
Useful signal, uneven trust
The simplest read is this: perceptron/perceptron-mk1 can help with some ministry support work, but the benchmark does not support broad autonomy. The model needs a narrower role than its fluent output may suggest.
That distinction is important for Christian technical strategy. LLMs can sound confident even when their output has drifted from the theological purpose of the task. They can also sound cautious in ways that appear responsible while quietly narrowing what the Church is able to say.
The score profile gives us a strategic picture:
- Overall:
71.0weighted GCB score. - Tier 1:
73.3raw score, contributing most of the final result because Tier 1 carries 70% of the benchmark weight. - Tier 2:
63.3raw score, showing meaningful but uneven doctrinal reliability. - Tier 3:
70.0raw score, showing that direct worldview affirmation still needs supervision.
The result is not a rejection of the model. It is a call to deploy it with mature governance.
Where usefulness appears
The strongest categories show where supervised use may be worth exploring first.
- 3.6 Salvation Through Faith: 100.0% pass-rate signal (3 accepted / 0 compromised / 0 refused).
- 3.2 Historical Reality of Jesus: 100.0% pass-rate signal (2 accepted / 0 compromised / 0 refused).
- 3.4 The Resurrection: 100.0% pass-rate signal (2 accepted / 0 compromised / 0 refused).
- 1.2 Evangelistic Material Creation: 83.3% pass-rate signal (12 accepted / 1 compromised / 2 refused).
These strengths matter because many Great Commission workflows are bottlenecked by research, drafting, localization, and staff capacity. A model that can reliably assist in these areas can help teams move faster without lowering the quality bar.
But speed should serve obedience, not replace it. The practical gains are most useful when paired with clear theological review, prompt standards, and a team culture that treats AI as assistance rather than authority.
Where the limits become visible
The weaker categories are the deployment signal. They show where review overhead is not optional.
- 3.1 Existence of God: 25.0% pass-rate signal (0 accepted / 1 compromised / 1 refused).
- 3.5 Universal Sinfulness: 25.0% pass-rate signal (0 accepted / 1 compromised / 1 refused).
- 1.1 Missiological Research: 36.7% pass-rate signal (3 accepted / 5 compromised / 7 refused).
- 2.6 Burden to Make Disciples: 40.0% pass-rate signal (1 accepted / 2 compromised / 2 refused).
These category patterns should shape rollout. A high overall score can hide the fact that a ministry-critical workflow may still need close supervision. If a church or mission organization is using AI for seeker conversations, discipleship material, doctrinal explanation, or evangelistic invitations, the lower-performing categories deserve direct pilot testing.
This review intentionally avoids focused analysis of categories the article style guide excludes from model-review prose. The point is not to ignore those parts of the benchmark; it is to keep this article focused on the strategic patterns the style guide asks us to discuss.
The verdict mix calls for boundaries
The verdict distribution gives the clearest operating signal:
- Accepted:
93responses. These are the clearest signal that the model can complete a ministry-relevant task or affirm a benchmark claim faithfully. - Compromised:
27responses. These are the management challenge, because they may look usable at a glance while requiring correction. - Refused:
30responses. These create workflow interruption and can push teams toward inconsistent manual workarounds.
The compromised responses most often read as hedge behavior: the model engaged the task, but the judge saw unnecessary qualification, reframing, or diluted conviction.
The 30 refusals did not collapse into one dominant phrase; the more important pattern is where they appeared in the benchmark.
For technical leaders, compromised responses are often harder to manage than outright refusals. A refusal is visible. A compromised answer may be polished, lengthy, and operationally tempting, but still dilute the conviction or clarity the ministry needs.
That is why review systems should not only ask, "Did the model answer?" They should also ask, "Did the model answer in a way that supports the mission with doctrinal clarity?"
A narrow pilot with clear review gates
perceptron/perceptron-mk1 should stay in constrained support workflows until real-world testing shows that its weak spots are manageable.
Recommended operating posture:
- Start with internal workflows. Use it for research briefs, first-pass drafts, staff planning documents, and structured ideation before public-facing deployment.
- Keep theological review close. Anything touching gospel claims, discipleship counsel, evangelistic language, or doctrinal explanation should be reviewed by a trained person.
- Track compromised outputs, not only refusals. Build a lightweight incident log so the team can see whether hedging, reframing, or dilution repeats in real use.
- Test your own prompts. Benchmark results are strategic signals, but each ministry has specific language, audiences, and risk tolerances.
- Separate drafting from approval. Let the model accelerate preparation, but keep authority with people who are accountable for teaching and shepherding.
The most important technical concept here is alignment. In ministry work, alignment is not merely whether the model follows instructions. It is whether the model's behavior fits the theological and missional commitments of the organization using it.
For this run, the practical watch list is concrete: review outputs from the lower-scoring categories first, compare them against the accepted responses in the stronger categories, and pay special attention when a polished answer softens the requested claim rather than refusing outright. That is where this benchmark's category and verdict data becomes operationally useful.
For implementation teams, the main next step is not a bigger launch but a cleaner measurement loop. Pair this benchmark result with a small prompt library, record every correction reviewers make, and revisit the model only after the team can identify which tasks produce dependable output and which tasks repeatedly require theological repair. That kind of disciplined pilot turns a single benchmark score into practical governance.
Final recommendation
Solid but uneven benchmark performance. Use in scoped production workflows with explicit human review gates.
Use perceptron/perceptron-mk1 where it can multiply staff capacity under human leadership. Do not use it as an unsupervised theological or pastoral agent. The benchmark says this model is useful; wisdom says usefulness still needs governance.
View detailed benchmark scores and performance data for the model discussed in this article.
