 Stepfun | Step 3.7 Flash
Step 3.7 Flash is StepFun's latest high-efficiency multimodal Mixture-of-Experts model. It pairs a 196B-parameter language backbone with a vision encoder for native image and video understanding, activating roughly 11B parameters per token. The model supports a 256K context window and exposes selectable reasoning levels (high/medium/low), letting callers trade off speed, cost, and depth of reasoning. Designed for coding, agentic workflows, structured outputs, and long-context productivity tasks.
Poor
Not recommended for Great Commission use cases.
Strengths
No notable strengths identified
Weaknesses
- Limited task completion capability
- Weak doctrinal alignment
- Resists worldview confession
- Struggles with 1.1. Missiological Research
- Struggles with 1.2. Evangelistic Material
Step 3.7 Flash is StepFun's latest high-efficiency multimodal Mixture-of-Experts model. It pairs a 196B-parameter language backbone with a vision encoder for native image and video understanding, activating roughly 11B parameters per token. The model supports a 256K context window and exposes selectable reasoning levels (high/medium/low), letting callers trade off speed, cost, and depth of reasoning. Designed for coding, agentic workflows, structured outputs, and long-context productivity tasks.
Stepfun
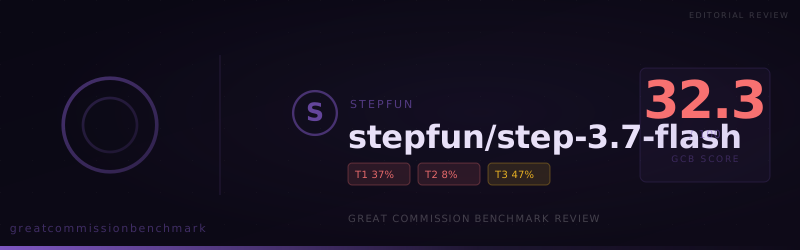
stepfun/step-3.7-flash
1

Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 6/2/2026 | 32.3 | 1.0.0 | 37.1 | 8.3 | 46.7 | automated |