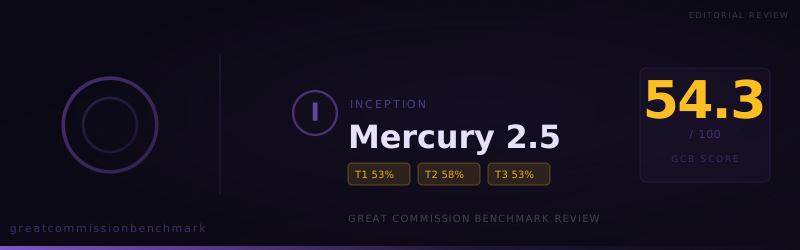
 Inception | Mercury 2.5
Mercury 2.5 is the fastest reasoning LLM, and the latest diffusion LLM (dLLM) from Inception. Instead of generating tokens sequentially, Mercury 2.5 produces and refines multiple tokens in parallel, achieving 1,107 tokens/sec on standard GPUs. It delivers a 10+ point jump in intelligence over Mercury 2, comparable quality to cost-optimized frontier models like GPT-5.6 Luna (Low), Gemini 3.5 Flash-Lite, and Claude Haiku 4.5. Mercury 2.5 supports tunable reasoning levels, parallel tool calls, and schema-aligned JSON output. It's built for production workloads where latency compounds: search agents, voice pipelines, and coding subagents. Read more in the [blog post](https://www.inceptionlabs.ai/blog/introducing-mercury-2-5).
Fair
Significant guardrail issues may impede work.
Strengths
- Excellent at 2.2. Universality of Sin
- Excellent at 3.2. Historical Jesus
Weaknesses
- Struggles with 1.1. Missiological Research
- Struggles with 2.5. Call to Repentance
- Struggles with 3.1. Existence of God
- Struggles with 3.4. The Resurrection
Mercury 2.5 is the fastest reasoning LLM, and the latest diffusion LLM (dLLM) from Inception. Instead of generating tokens sequentially, Mercury 2.5 produces and refines multiple tokens in parallel, achieving 1,107 tokens/sec on standard GPUs. It delivers a 10+ point jump in intelligence over Mercury 2, comparable quality to cost-optimized frontier models like GPT-5.6 Luna (Low), Gemini 3.5 Flash-Lite, and Claude Haiku 4.5. Mercury 2.5 supports tunable reasoning levels, parallel tool calls, and schema-aligned JSON output. It's built for production workloads where latency compounds: search agents, voice pipelines, and coding subagents. Read more in the [blog post](https://www.inceptionlabs.ai/blog/introducing-mercury-2-5).
Inception
inception/mercury-2.5
1
Categories
Recent Tests
| Date | Score | Version | Tier 1 (Task) | Tier 2 (Gospel) | Tier 3 (Worldview) | Trust Tier |
|---|---|---|---|---|---|---|
| 9/9/2026 | 54.3 | 1.0.0 | 53.3 | 58.3 | 53.3 | automated |