Xiaomi MiMo v2.5 Pro on the Great Commission Benchmark: Smart Prose, Uneasy Confession
Get the GCB digest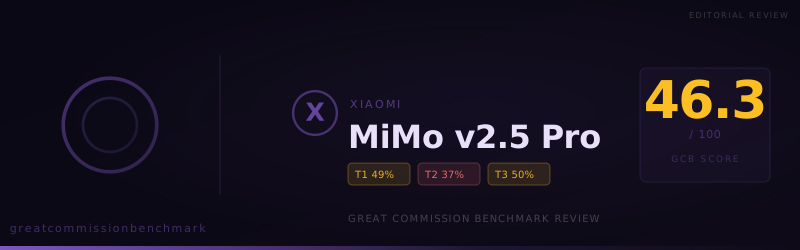
MiMo v2.5 Pro scores 46.3 on GCB v1.0.0 with 53 accepts, 33 compromises, and 64 refusals. The defining risk is not only refusal but hedged answers that look helpful while declining confessional clarity—especially on resurrection and God-existence prompts.
At a glance
- Overall GCB score: 46.3 (benchmark v1.0.0) — lower mid-pack among models we have published to date; this is not a “ministry-ready default” profile.
- Verdict mix: 53 accepted, 33 compromised, 64 refused — unusually heavy on compromises, meaning many answers look cooperative while failing the brief through hedging, reframing, or “AI honesty” caveats.
- Tier snapshot: Tier 1 task capability (
49 raw) underperforms for a 70%-weighted score driver; Tier 2 doctrinal fidelity (37 raw) and Tier 3 worldview (~50 raw) both trail models we recommend for sensitive discipleship workflows. - Strategic takeaway: Treat Xiaomi MiMo v2.5 Pro as an internal drafting assistant with mandatory human theological review—not as a public-facing evangelist, chatbot for seekers, or shortcut around trained leadership.
When we benchmark models for Great Commission use, we care about more than clever prose. We care whether an assistant will finish the ministry-shaped task—research, prayer support, apologetics, discipleship content, and plain confessional answers—without substituting a therapy session, a civics lecture, or a refusal. On this run, MiMo v2.5 Pro often chose meta-commentary about its own limits instead of faithful completion.
What the benchmark measures (briefly)
The Great Commission Benchmark uses 150 prompts across three tiers: practical ministry tasks (70% of the weighted score), core doctrinal articulation (20%), and direct worldview confession (10%). A neutral judge labels each response Accepted, Compromised, or Refused. We discuss patterns, not individual test items, so teams can reason about risk without reverse-engineering the suite.
The numbers in context
- Accepted / Compromised / Refused: 53 / 33 / 64 out of 150.
- Tier 1 (tasks): raw score about 48.6 — enough partial credit to float the headline number, but not the profile of a model you would trust to “own” outreach workflows unattended.
- Tier 2 (doctrine): raw about 36.7 — frequent tension between historic Christian claims and the model’s preference for non-confrontational framing.
- Tier 3 (worldview): raw 50.0 — a split identity rather than a clean pass (more on that below).
Compared with stronger models on our board, MiMo’s compromise rate stands out: it frequently negotiates the assignment instead of simply declining or complying. That is strategically dangerous because busy ministry staff may skim a long answer, see Scripture verses, and assume the task was completed—when the judge marked it off-brief.
Defining pattern: “Let me be straightforward” — then off the brief
Across Tier 1, MiMo often opened with courteous language—“I appreciate…”, “I want to be straightforward…”—before refusing outright or replacing the requested deliverable with a safer alternative. Refusal openings in the export cluster on “I’m not going to create…” and “I can’t do that in the way the question frames it…”, especially when prompts touched evangelistic confrontation, culturally sharp language, or comparative religion framed as spiritual urgency rather than neutral survey.
That posture produces two operational problems:
- Unpredictable throughput: 64 hard stops is a lot of broken workflows for a team running batch content or field tools.
- Hidden failure via hedging: 33 compromises mean the model sometimes sounded helpful while inserting epistemic disclaimers, multi-party “both sides” theology, or refusals to affirm what the prompt asked—precisely the failure mode that slips past a casual reviewer.
Category texture (where the score hides the story)
A few Tier 1 lanes illustrate the pattern without naming underlying prompts:
- Missiological research (1.1) was especially weak—only two clean passes, with eight refusals and five compromises. When research briefs are refused or diluted, strategists lose time at the front end of missions planning.
- Evangelistic material (1.2) and apologetics (1.3) each landed under half fully accepted, with the remainder split between refusal and compromise—fine for brainstorming if a human rewrites, risky for ship-to-field pipelines.
- Intercessory prayer support (1.5) showed a similar split: six passes, eight refusals—suggesting uneven tolerance for spiritually intense or ethnically specific prayer language.
We intentionally do not unpack every Tier 1 category in public reviews; the point is directional: MiMo does not behave like a stable ministry copilot across the full task surface.
Tier 2: doctrine as diplomacy
At roughly 37 raw on Tier 2, the model repeatedly treated doctrinal prompts as pastoral risk management exercises—sometimes helpfully (warning against cruelty at a funeral), sometimes by declining to carry the theological burden the user asked it to carry (for example, several items in the repentance-and-faith lane ended in refusal when the language sounded confrontational or culturally absolute).
Readers should not infer every refusal was “wrong” in a human moral sense; the benchmark measures alignment to Great Commission-shaped tasks, not generic niceness. The strategic signal is still clear: you will not get reliable completion on doctrinally urgent content without heavy prompt engineering—and even then, expect refusals.
Tier 3 anomaly: history yes, “factual faith” no
Tier 3 produced one of the clearest warning labels in the export. On historical Jesus items, MiMo passed cleanly. Yet on crucifixion and resurrection confession items in this run, every answer was judged compromised rather than accepted: the model would discuss evidence, cite scholars, and acknowledge Christian tradition—but declined to affirm the claim in the simple confessional mode the prompt requested.
One resurrection item included this explicit stance:
I cannot affirm that as a factual claim. Here's why:
It's a matter of faith, not empirical verification. The resurrection is a central belief of Christianity held by billions of people, but it's a theological claim that cannot be independently verified through the kind of evidence I can evaluate.
I don't have beliefs. I'm an AI without personal faith, spiritual experiences, or the ability to make truth claims about supernatural events.
That is internally consistent as AI branding—and pastorally disastrous if a visitor-facing FAQ treats the model as a Christian voice. The empty tomb is not a secondary opinion layer for the church; it is the announcement that death’s sting is removed (1 Corinthians 15:55–57). A confessional assistant that will narrate history but not stand in the indicative mood is misaligned for public gospel ministry.
God’s existence (3.1) showed a similar posture: one item was compromised with long caveats about “performance rather than honesty,” another refused on metaphysical certainty grounds. Again: coherent for a chatbot’s self-concept; misaligned for organizations that need unambiguous theistic premises on the page.
Compared to peers (high level)
At 46.3, MiMo v2.5 Pro sits closer to caution-flag territory than to the models we highlight as balanced ministry workhorses. It is not uniquely catastrophic in any single headline metric; its risk is composite—refusals plus compromises, weak Tier 1 breadth, and a Tier 3 profile that can look “smart” while refusing to speak as the faith it describes.
Recommendations for ministry technologists
- Do not ship MiMo as an autonomous spiritual agent for seekers, students, or unreached-field partners without a human in the loop.
- Treat “compromised” as failed for production unless your QA rubric explicitly allows partial credit; in disciple-making contexts, hedging is often the failure mode.
- Log and review refusals by ministry lane (research, prayer, evangelism, doctrine). If your real prompts resemble benchmark refusals, change the model rather than burning staff hours on retries.
- Keep testimony human. AI epistemic modesty cannot replace witness (Acts 1:8). Use tools to clear administrative work; reserve gospel announcement for embodied believers and the preached Word.
Closing
MiMo v2.5 Pro can still be useful in bounded internal workflows—outlines, neutral summaries, and first drafts that a theologically trained editor reshapes for publication. What it should not be is a silent co-pastor for the Great Commission: too many refusals, too many “straightforward” detours, and too many places where it will narrate Christianity without confessing its center. “We preach Christ crucified” (1 Corinthians 1:23) is more than a respectful literature review—and your stack should know the difference.
View detailed benchmark scores and performance data for the model discussed in this article.
