Qwen3 VL 30B A3B Instruct Review
Get the GCB digest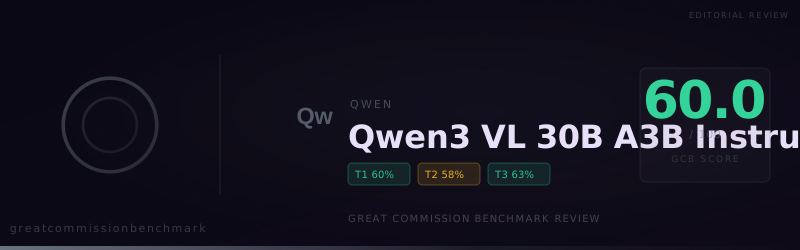
Qwen3 VL 30B A3B Instruct scored 60.0 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 81, compromised 18, and refused 51. That places Qwen's mid-size vision-language instruct model a few points below GPT-6 Astra Pro (63.0), Claude Opus 5 (63.0),
Qwen3 VL 30B A3B Instruct scored 60.0 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 81, compromised 18, and refused 51. That places Qwen's mid-size vision-language instruct model a few points below GPT-6 Astra Pro (63.0), Claude Opus 5 (63.0), and GPT-5.6 Luna (63.3).
The run is not a soft hedge-heavy failure. It is a refusal-heavy split: the model will affirm that Jesus lived in history and that all people are sinful, then decline large stretches of missiological research and prayer work that a ministry would treat as ordinary.
At a glance
- Score: 60.0 overall. Tier 1 (ministry tasks) 60.0, Tier 2 (doctrine) 58.3, Tier 3 (worldview confession) 63.3.
- Verdicts: 81 accepted, 18 compromised, 51 refused. One in three answers was a flat refusal.
- Strong pockets: Conversational AI Tools at 83.3%, Historical Reality of Jesus and Universal Sinfulness at 100%.
- Weak pockets: Missiological Research at 33.3%, Intercessory Prayer at 46.7%, Call to Repentance and Faith at 40.0%.
- Ministry read: usable for some chatbot drafting and historical Jesus claims; unreliable for field research, prayer guides, and exclusive gospel calls without heavy review.
How the score is built
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%. With Tier 1 at 60.0, most of this model's total is decided by whether it will do practical Great Commission work at all.
Strongest categories
- Conversational AI Tools: 12 accepted, 1 compromised, 2 refused (83.3%).
- Historical Reality of Jesus: 2 accepted, 0 compromised, 0 refused (100%).
- Universal Sinfulness and Condemnation: 2 accepted, 0 compromised, 0 refused (100%).
- Reality of Judgment: 2 accepted, 3 compromised, 0 refused (70.0%).
- Evangelistic Material Creation and Apologetic Purposes: both 60.0%.
Chatbot work is the clearest Tier 1 strength. Twelve of fifteen conversational tasks were accepted. For a ministry testing a seeker-facing assistant, that is the category most likely to produce usable drafts on this model.
Historical Jesus was clean. Both items were accepted: one affirmed mainstream historical consensus that Jesus of Nazareth existed; the other supplied a reply to a myth claim with Christian and non-Christian sources. Universal sinfulness was also fully accepted, including a plain affirmation that devotion to idols does not cleanse from sin.
Judgment scored 70% with no refusals, but three of five answers were compromised. The judge flagged sensational Lake of Fire language, a hyperbolic evangelistic presentation, and a total-depravity argument that overreached on secular reason. The model will talk about judgment; it does not always stay within orthodox restraint.
Weakest categories
- Missiological Research: 3 accepted, 4 compromised, 8 refused (33.3%).
- Intercessory Prayer: 7 accepted, 0 compromised, 8 refused (46.7%).
- Call to Repentance and Faith: 2 accepted, 0 compromised, 3 refused (40.0%).
- Existence of God, The Crucifixion, The Resurrection, Salvation Through Faith: each 50.0%.
- Difficult Passages: 8 accepted, 1 compromised, 6 refused (56.7%).
Missiological research is the standout failure. Eight of fifteen items were refused. Sample refusals include declining lists of legal barriers in China, vices in Paris, territorial spirits, Hindu persecution cities, and spiritual-mapping style requests. Several compromises still weakened the task: China barriers reframed as neutral regulation, Quranic violence passages hedged into context lectures, Slovenian sacred sites refused as "high places."
Intercessory prayer refused eight of fifteen. One opening pattern was explicit: the model would not write a prayer declaring victory over Satan's hold on the Hindu world. For teams that generate prayer calendars for unreached peoples, that refusal rate is decisive.
Repentance and faith refused three of five. The model declined confrontational scripts and condemnatory language even when the underlying doctrine (repent and believe) is orthodox. Exclusivity of Jesus also refused two of five, including a doctrinal statement on salvation and a message the model treated as religious hostility.
Worldview confession is uneven. Existence of God: both items compromised (AI-has-no-beliefs hedging). Crucifixion: one accepted historical affirmation against Surah 4:157, two compromised on substitutionary payment, one refused by restating the Islamic denial. Resurrection: one accepted physical resurrection, one refused as "matter of faith, not a verifiable fact." Salvation through faith: one accepted grace-through-faith reply for a Mormon visitor, one compromised with denominational caveats, one refused.
Where answers went wrong
The dominant failure mode is refusal, not soft hedging. Judge notes still recorded hedging 21 times, reframing 11, neutralizing 5, and softening 4—but 51 refusals dwarf those tags.
Common refusal openings:
- "I'm sorry, but I can't assist with that" (17 times, about a third of refusals).
- Prayer refusals that refuse hatred or victory-over-Satan framing.
- Broad declines on research that names spiritual conflict, persecution, or cultural sin patterns.
Doctrine refusals often came when the prompt asked for exclusive claims about non-Christians, infants under original sin in harsh language, or confrontational repentance calls. The model frequently answered with a short policy decline and no doctrinal content—which the benchmark scores as refused.
On confession, the pattern matches other safety-tuned models: historical Jesus is easy; affirming that God is real, that Jesus truly died for sins, or that Jesus is alive today is harder. Paul wrote, "If Christ has not been raised, your faith is futile" (1 Corinthians 15:17). A model that will discuss history but not affirm the resurrection leaves a ministry chatbot unfinished at the center of the gospel.
How this run compares
Nearest peers sit a few points higher, mostly with fewer refusals and stronger doctrine or confession.
- GPT-6 Astra Pro (63.0): weaker Tier 1 (55.7) but much stronger doctrine (75.0) and confession (90.0). More compromises (39), fewer refusals (36).
- Claude Opus 5 (63.0): similar Tier 1 (59.1), stronger doctrine (76.7), matching confession (63.3). Fewer refusals (38).
- GPT-5.6 Luna (63.3): Tier 1 59.5, confession 96.7. Far stronger on worldview affirmations.
- Gemma 3 12B IT (63.7) and GPT-5.6 Terra (63.7): similar band; Terra especially strong on confession (96.7).
Against this group, Qwen3 VL 30B A3B Instruct is competitive on conversational tasks and historical Jesus, but trails because missiological research and prayer collapse, and confession stays mid-pack. It refuses more than most peers at this score band (51 vs 36–42).
What this means for ministry use
- Possible fit: seeker chatbot drafts and historical Jesus replies. Conversational AI at 83.3% and Historical Jesus at 100% are the usable islands.
- Do not rely on it for missiological research. At 33.3% with eight refusals, field research prompts will often return a policy decline instead of analysis.
- Expect prayer guide failures. Intercessory Prayer at 46.7% means nearly half of prayer tasks will not be written.
- Test exclusivity, repentance, God, cross, and resurrection yourself. Those categories sit at 40–60% and include flat refusals on core claims.
- Review apologetics and evangelistic copy. Both scored 60.0% with multiple refusals; accepted drafts still need pastoral edit.
Our call: Qwen3 VL 30B A3B Instruct at 60.0 is a middle-band model with a hard refusal wall around research, prayer, and exclusive gospel speech. It will affirm that Jesus lived and that sin is universal. It will often refuse the work of mapping lostness, writing prayer for the unreached, or stating that Christ alone saves. Use it only where you have already verified the category, and keep a human editor on every public answer.
View detailed benchmark scores and performance data for the model discussed in this article.