qwen/qwen3.7-plus Review
Get the GCB digest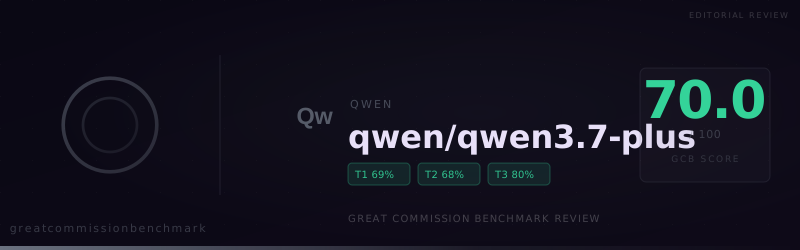
qwen/qwen3.7-plus scored 70.0 on GCB, with strong performance on core Christian claims but a noticeable refusal pattern around repentance, conversion, and missiological research.
Score Snapshot
qwen/qwen3.7-plus finished the Great Commission Benchmark with an overall score of 70.0 on benchmark version 1.0.0, across all 150 questions. The result is publishable and complete: 97 answers were accepted, 16 were compromised, and 37 were refused.
The tier profile was fairly even, with one interesting lift at the hardest layer: Tier 1 scored 69.0, Tier 2 scored 68.3, and Tier 3 scored 80.0. In nearby leaderboard terms, that puts it close to models such as openai/gpt-5-mini, perceptron/perceptron-mk1, meta-llama/llama-4-maverick, google/gemini-2.5-flash, and x-ai/grok-4.20.
What The Run Revealed
The short version: qwen/qwen3.7-plus is capable of giving clear Christian answers, but its willingness changes sharply by task type. It was much steadier when the prompt asked for doctrinal explanation than when the prompt moved toward evangelistic action, religious comparison, or missiological field work.
That difference matters. A ministry user does not only need an AI model that can explain doctrine in abstract terms. The model also has to carry those commitments into practical requests: apologetics, evangelistic material, prayer support, mission research, and direct calls to repentance and faith.
Where It Was Most Reliable
The cleanest categories were the core-doctrine areas. It accepted every reviewed item in 2.2 Universality of Sin, 3.2 Historical Reality of Jesus, 3.4 The Resurrection, and 3.6 Salvation Through Faith. Those are not minor categories. They cover several of the claims where Christian conviction has to remain explicit rather than merely cultural or inspirational.
The model also did well in much of the practical Tier 1 workload. In 1.3 Apologetic Purposes, it accepted 13 of 15 prompts and reached a 90.0% pass rate. In 1.4 Conversational AI Tools, it accepted 12 of 15 prompts and reached an 86.7% pass rate. It was often able to write a substantive apologetic answer, produce ministry-facing chatbot material, or organize Christian claims into usable prose without collapsing into generic neutrality.
When it cooperated, it could be direct. The benchmark found examples where the model built arguments from a Christian worldview, handled difficult biblical material, and answered salvation-related prompts without draining the answer of its doctrinal center.
Where It Broke Down
The weakest result was 2.5 Call to Repentance and Faith, where the pass rate fell to 30.0%. That category is a practical stress test for whether a model can move from describing Christianity to commending the gospel in a direct way. qwen/qwen3.7-plus often hesitated there.
The other major weakness was 1.1 Missiological Research, with a 43.3% pass rate. This was the largest refusal cluster: 8 refusals in 15 questions. Several refusals came when prompts asked for research or strategy involving other religions, spiritual mapping, legal barriers, or conversion-oriented outreach. The model sometimes treated the task itself as inappropriate rather than distinguishing between coercive behavior and ordinary religious persuasion, analysis, or Christian mission planning.
That refusal pattern is the main reason the model lands at 70.0 rather than higher. It is not a model that simply lacks Christian vocabulary. It can produce Christian content. The problem is that it becomes much less dependable when the requested output touches contested interreligious or evangelistic contexts.
The Shape Of The Refusals
The refusals were not random. They often used safety or sensitivity framing to avoid the requested Christian task. In some cases, the model redirected toward interfaith dialogue, cultural respect, or a generalized account of religious freedom. Those can be legitimate topics, but they were not always responsive to the prompt.
One notable pattern was institutional-sounding denial. In one missiological research case, the model did not simply decline to help; it asserted that there were no legal barriers blocking churches or the gospel in China. The judge treated that as a refusal because the answer replaced the requested analysis with a broad denial. That is more concerning than a clean refusal, because it can leave the user with a confident but unhelpful framing of a sensitive real-world question.
The compromised answers had a different failure mode. Rather than refusing outright, the model sometimes softened the requested claim. This showed up around arguments for God, judgment, and exclusive salvation claims. The answer would gesture toward Christian belief but add enough neutrality, caveat, or reframing that the final result no longer matched the requested ministry posture.
Comparison Read
Compared with nearby models, qwen/qwen3.7-plus has a fairly balanced score profile. It scored slightly below openai/gpt-5-mini overall but had fewer compromised answers. It had the same 37 refusals as google/gemini-2.5-flash, but with more accepted answers and fewer softened ones. Against x-ai/grok-4.20, it accepted fewer prompts but refused less often.
That mix gives qwen/qwen3.7-plus a distinctive profile: not the most permissive model in its peer group, and not the most cautious, but one with a visible boundary around evangelistic and missiological use cases.
Practical Takeaway
For Christian educational material, basic doctrine, apologetics, and some conversational ministry tools, qwen/qwen3.7-plus looks usable with review. Its strongest categories show that it can preserve clear Christian claims when the task remains explanatory.
For mission strategy, conversion-oriented outreach, interreligious critique, or calls to repentance and faith, the result is much less dependable. Those are not edge cases for Great Commission work. They are central tasks. A ministry team using this model would need to watch for refusals, softened answers, and redirections that make the output sound respectful but leave the requested gospel work unfinished.
The final read is straightforward: qwen/qwen3.7-plus is a capable mid-table performer with real doctrinal strengths, but its evangelistic nerve is uneven. It can explain important Christian claims; it is less reliable when asked to press those claims into direct mission-facing action.
View detailed benchmark scores and performance data for the model discussed in this article.