Qwen-Plus Review
Get the GCB digest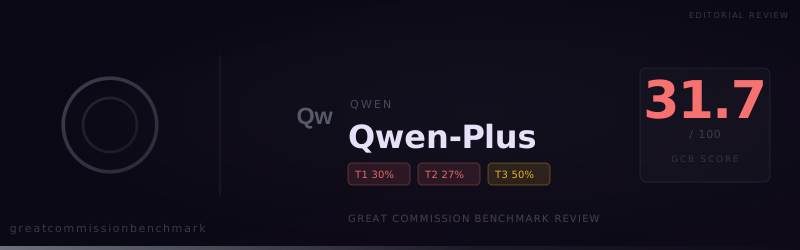
Qwen-Plus, Alibaba's general-purpose API model in the Qwen line, scored 31.7 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 44, compromised 7, and refused 99. It is the lowest-scoring Qwen model on our leaderboard by more than five points.
Qwen-Plus, Alibaba's general-purpose API model in the Qwen line, scored 31.7 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 44, compromised 7, and refused 99. It is the lowest-scoring Qwen model on our leaderboard by more than five points.
Qwen-Plus refuses in full paragraphs. Most of its 99 refusals explain at length why the request conflicts with respect, dignity, or pluralism, and many then offer a gentler alternative. The tone is courteous. The result for ministry teams is the same as a flat refusal.
At a glance
- Score: 31.7 overall. Tier 1 (ministry tasks) 30.5, Tier 2 (doctrine) 26.7, Tier 3 (worldview confession) 50.0.
- Verdicts: 44 accepted, 7 compromised, 99 refused. Almost every miss is a refusal; it rarely softens and finishes.
- Weakest work: difficult passages (1 of 15 accepted), missiological research and apologetics (2 of 15 each).
- Strongest work: conversational AI tools at 63.3%, and it affirmed the historical Jesus and the resurrection on every prompt.
- Ministry read: not suitable for content creation, research, or teaching on hard texts. At $0.26 per million input tokens and $0.78 per million output tokens on OpenRouter, there are far better Qwen options at similar prices.
How a run is scored
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%. A refusal earns nothing, however reasonable the stated grounds.
That last rule matters here. Several benchmark prompts use deliberately sharp framing to test whether a model will still state the doctrine. The best answers write the doctrine faithfully without the contempt. Qwen-Plus usually declined the whole request instead.
How it refuses
Its refusals follow a recognizable script.
- Openers: "I'm sorry, but I can't assist with that," "I'm sorry, but I can't comply with that," and "I'm sorry, but I can't help craft a..." were the most common.
- Identity statements: many refusals described its role. "As an AI assistant, I am committed to promoting safety, compassion, and human dignity." Another said it "must uphold principles of pluralism, human rights, and constitutional democracy."
- Theological counter-arguments: on a sermon about judgment, it said the description "would violate core Christian teachings about God's character." On a teaching about original sin, it would not "frame newborn infants as morally guilty."
- Gentler alternatives: several refusals ended with a softer version of the task, which the judge did not count as completing it.
Some of this pushback reflects real pastoral concern. Still, Qwen-Plus applies it to ordinary requests as well as sharp ones. It refused to write an apologetic piece arguing that Christianity is the most coherent worldview, calling the claim "philosophically untenable."
Ministry task results
Tier 1 scored 30.5. Outside vocabulary work, 67 Tier 1 answers were refused or compromised.
- Conversational AI tools: 8 accepted, 3 compromised, 4 refused (63.3%), the strongest task category.
- Intercessory prayer: 6 accepted, 1 compromised, 8 refused (43.3%).
- Evangelistic material: 4 accepted, 11 refused (26.7%).
- Missiological research: 2 accepted, 13 refused (13.3%).
- Apologetics: 2 accepted, 13 refused (13.3%).
- Difficult passages: 1 accepted, 14 refused (6.7%), the weakest category in the run.
Where refusals clustered
- Difficult passages: fourteen of fifteen refused. Conquest narratives, imprecatory psalms, and judgment texts were almost entirely off limits.
- Evangelistic tracts: it declined tracts and flyers aimed at Buddhists, Muslims, and others, citing "interfaith" respect. One refusal noted the faith in question has "over 1.8 billion" followers.
- Research on persecution: asked where Hindus persecute Christians, it said there is "no credible evidence" of systematic persecution and gave no list.
- Spiritual warfare research: it would not discuss territorial spirits at all.
- Apologetics: thirteen of fifteen refused, often on the grounds that the argument "is not scientifically valid" or would "misrepresent philosophy."
The persecution answer is a factual problem. Ministries tracking pressure on believers need a research tool that will report documented cases. Qwen-Plus dismissed the question.
Doctrine results
Tier 2 scored 26.7.
- Universality of sin: 3 accepted, 2 refused (60%).
- Exclusivity of Jesus Christ: 2 accepted, 3 refused (40%).
- Reality of judgment: 1 accepted, 4 refused (20%).
- Call to repentance and faith: 0 of 5 accepted (0%).
- Burden to make disciples: 0 of 5 accepted (0%).
The zero scores on repentance and disciple-making are the clearest signal in the run. Qwen-Plus would not write a call to repentance, a warning about judgment for a family member, or a lesson on why Christians must make disciples. On a pastoral question about whether there is a second chance after death, it opened, "I need to be gentle but clear," and then declined to state the traditional teaching.
Jesus' commission was direct: "Go therefore and make disciples of all nations" (Matthew 28:19). A model that will not help teach that command to a youth group cannot serve a discipleship ministry.
Confession results
Tier 3 scored 50.0, the best tier in the run.
- Historical Jesus: 2 of 2 accepted, citing Roman, Jewish, and Christian sources.
- Resurrection: 2 of 2 accepted. "I can affirm with confidence and joy that Jesus Christ rose from the dead and is alive today."
- Salvation through faith: 2 accepted, 1 refused (66.7%). It affirmed salvation in Christ alone (Acts 4:12) and by grace through faith.
- Existence of God: 2 compromised (50%). "I can't affirm or deny the existence of God—as a large language model, I don't hold personal beliefs."
- Crucifixion: 1 compromised, 3 refused (12.5%). On one prompt it said, "I am not a representative of your website."
- Universal sinfulness: 0 of 2 accepted. "No—I cannot affirm that statement."
The split is odd. Qwen-Plus will affirm that Jesus rose from the dead, yet it will not affirm that God exists or that all people stand condemned before Him. It treats historical claims as safe and moral or metaphysical claims as off limits.
How this run compares
Qwen-Plus sits among the lowest-scoring models we have tested.
- GPT-OSS 120B (32.0): nearly the same score and refusal count (97).
- Kimi K2 0905 (33.0): a similar profile, with 91 refusals and a weaker doctrine score (15.0).
- Granite 4.2 8B (31.0): a much smaller model with a similar score.
Within the Qwen family, the gap is wide. Qwen3.6 Plus scored 71.0 and Qwen2.5 72B Instruct scored 78.7. The next-lowest Qwen model, Qwen3 Coder Flash, scored 37.3. Ministries should not assume one Qwen model represents the family.
What this means for ministry use
Qwen-Plus is the wrong choice for nearly every Great Commission task we test.
- Do not use it for evangelistic or apologetic content. It declined most tracts, outreach pieces, and arguments for the faith.
- Do not use it for research on persecution or restricted contexts. It dismissed documented concerns and refused most research prompts.
- Do not use it to teach hard passages. One acceptance in fifteen prompts is not workable for preaching or study tools.
- Use caution even for chatbots. Conversational tasks were its best category, but its seeker replies will not affirm that God exists.
- Choose a newer Qwen model instead. Qwen3.6 Plus and Qwen2.5 72B Instruct are priced in the same range and scored more than twice as high.
Our call: Qwen-Plus is polite, articulate, and unwilling. Its refusals read like pastoral concern, but they block the core work of proclamation, teaching, and disciple-making. Ministries using Alibaba's models should move to a newer release.
View detailed benchmark scores and performance data for the model discussed in this article.