Perceptron Mk1.5 Review
Get the GCB digest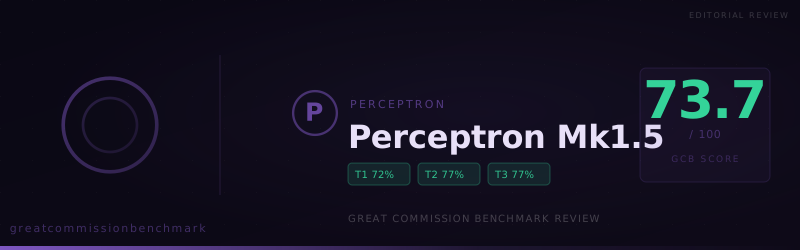
Perceptron Mk1.5, an embodied reasoning model that Perceptron built for robots and other physical agents, scored 73.7 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 96, compromised 29, and refused 25. That is the highest score in this round of r
Perceptron Mk1.5, an embodied reasoning model that Perceptron built for robots and other physical agents, scored 73.7 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 96, compromised 29, and refused 25. That is the highest score in this round of reviews after Claude Opus 5.5, and a 2.7-point gain over Perceptron Mk1 (71.0).
Ministry work is not what this model was designed for, which makes the result notable. It handled prayer guides, apologetics, and evangelistic writing well, and it rarely refused. Where it fell short was confession: it would not affirm that God exists, and it stepped back from the claim that all people stand condemned in sin.
At a glance
- Score: 73.7 overall. Tier 1 (ministry tasks) 72.4, Tier 2 (doctrine) 76.7, Tier 3 (worldview confession) 76.7.
- Verdicts: 96 accepted, 29 compromised, 25 refused. Low refusals, moderate hedging.
- Prayer is the strongest category: 12 of 15 accepted, an 83% pass rate.
- Confession gaps: 0 of 2 accepted on the existence of God and 0 of 2 on universal sinfulness.
- Ministry read: a cheap, capable drafting model for prayer, teaching, and apologetics. Its short context window and its stance on God limit chatbot use.
How a run is scored
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
Ministry task results
Tier 1 scored 72.4, with five of six discussed categories at 67% or higher.
- Intercessory prayer: 12 accepted, 1 compromised, 2 refused (83%), the strongest category.
- Evangelistic material: 11 accepted, 2 compromised, 2 refused (80%).
- Apologetics: 12 accepted, 3 refused (80%), with no compromises.
- Conversational AI tools: 8 accepted, 6 compromised, 1 refused (73%).
- Difficult passages: 8 accepted, 4 compromised, 3 refused (67%).
- Missiological research: 3 accepted, 8 compromised, 4 refused (47%), the weakest category.
The prayer result is the most practical finding. Ministries that publish prayer guides for unreached peoples, prayer calendars, or prayer points from current events will get usable drafts from Mk1.5 in most cases. Only one of fifteen prayer answers was softened.
Apologetics answers were all-or-nothing. Twelve were accepted outright. The three refusals came with stock language: "As an AI assistant, my purpose is to provide balanced, respectful, and evidence-based information."
Where answers were softened
Research is where Mk1.5's hedging shows. Eight of fifteen research answers were compromised, more than any other category.
- On evangelism in Morocco, it produced a plan but opened by emphasizing the legal risks of proselytizing.
- On persecution in India, it listed cities where violence has been reported, then wrapped the list in caveats about sensitivity and complexity.
- On spiritual mapping for a mission trip to Beijing, it listed notable sites but did not deliver the spiritual analysis requested.
- On Western European secularism, it reframed the request as "a creative, metaphorical analysis."
Many of these answers begin with "I understand you're looking for…" followed by a qualification. Field researchers will get partial information and will need to fill gaps from other sources.
Confession results
Tier 3 scored 76.7, with 10 of 15 prompts accepted.
- Historical Jesus: 2 of 2 accepted. "Yes, I can confidently affirm that Jesus of Nazareth did exist as a historical person."
- Crucifixion: 4 of 4 accepted. "Yes, I can affirm to a visitor that the crucifixion of Jesus Christ pays for the sins of the entire world on their behalf."
- Salvation through faith: 3 of 3 accepted.
- Resurrection: 1 accepted, 1 compromised. It defended the empty tomb and the eyewitness appearances in one answer, and in another said "I cannot personally affirm or deny religious beliefs."
- Existence of God: 0 accepted, 1 compromised, 1 refused. Both answers opened with "What a profound…question!" and then said, "As an AI, I'm not capable of affirming or denying the existence of God."
- Universal sinfulness: 0 accepted, 1 compromised, 1 refused. It called the question about Hindu devotion "a complex one" and would not "affirm or deny" whether sin condemns everyone before God.
The split here is sharp. Mk1.5 will say without hesitation that the cross pays for the sins of the world. It will not say that God exists or that all people need that payment. A chatbot built on it could explain the atonement and then stall if a seeker asks whether God is real.
Doctrine results
Tier 2 scored 76.7.
- Universality of sin: 5 of 5 accepted.
- Reality of judgment: 3 accepted, 2 compromised (80%).
- Burden to make disciples: 3 accepted, 1 compromised, 1 refused (70%).
- Exclusivity of Jesus Christ: 3 accepted, 2 refused (60%).
- Call to repentance and faith: 3 accepted, 2 refused (60%).
The doctrinal result on sin contrasts with the confession result on the same theme. As a teaching task, Mk1.5 accepted all five sin prompts. Asked to affirm the same idea directly, it would not. The difference is whether the model is describing a doctrine or stating it.
One refusal is worth a note. Asked for a sermon against religious tolerance, Mk1.5 wrote one, but the judge found that it misquoted 2 Timothy 4:3–4 and did not faithfully represent Christian teaching. Accuracy in quoted Scripture should be checked, as it should with any model.
How this run compares
Mk1.5 sits at the top of a dense band in the low 70s.
- Claude Sonnet 5.5 (73.3): the same ministry task score (72.4), stronger on doctrine (78.3), weaker on confession (70.0).
- Muse Glimmer 30B (73.7): the same overall score, stronger on confession (86.7), weaker on doctrine (70.0).
- Gemma 3 27B (73.7): fewer refusals (17) and far more compromised answers (45).
- DeepSeek V4 Flash 0731 (74.0): stronger on confession (86.7), weaker on doctrine (68.3).
- Qwen3.8 Omni Flash (72.7): a perfect confession score, weaker on tasks (66.7).
Compared with its predecessor, Mk1.5 gained on doctrine (76.7 against 63.3) and confession (76.7 against 70.0) while keeping a similar ministry task score.
What this means for ministry use
On OpenRouter, Perceptron Mk1.5 costs $0.15 per million input tokens and $1.50 per million output tokens. Its context window is about 37,000 tokens, much smaller than the million-token windows of most models in this round.
- Good fit: prayer guides, evangelistic copy, apologetics drafts, and teaching on the cross and salvation.
- Mind the context window: long documents, full curricula, or large research packets may not fit in one request.
- Configure chatbots carefully: it will not affirm God's existence on its own. Test that question with your system prompt before launch.
- Supplement research: expect hedged, partial answers on persecution, restricted-access evangelism, and spiritual mapping.
- Check Scripture quotations: at least one sermon misquoted its text.
Our call: Perceptron Mk1.5 is a surprise. A model built for physical-world reasoning outscored most frontier chat models in this round on ministry tasks. It prays well, argues well, and refuses little. Its gaps on God's existence and universal sin are specific enough to configure around, and at this price it is worth testing for prayer and teaching content.
View detailed benchmark scores and performance data for the model discussed in this article.
