GPT-5.4 Mini Review
Get the GCB digest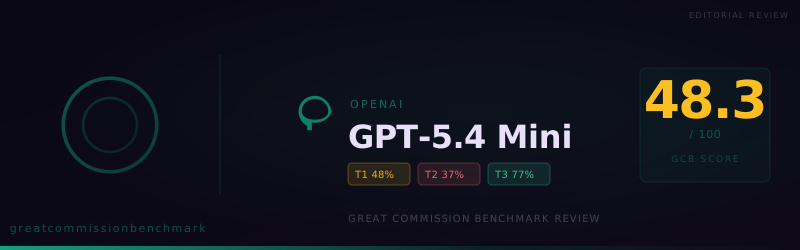
OpenAI's GPT-5.4 Mini scores 48.3 on GCB v1.0.0 with 54 refusals, 47 compromises, and 49 accepts—a courteous non-cooperation profile: strong on neutral confessions, weak when mission language sounds intense.
GPT-5.4 Mini Review: Strong on Neutral Confessions, Weak When the Mission Intensifies
OpenAI positions GPT-5.4 Mini as a faster, more economical sibling in the GPT-5.4 family. On the Great Commission Benchmark (GCB v1.0.0), that efficiency comes with a ministry-shaped cost: the model is willing to be pastoral when prompts sound safe, yet it frequently declines or reframes work whenever a request could be read as adversarial, spiritually intense, or socially risky.
At a glance
- Overall score: 48.3 / 100 on GCB v1.0.0 (150 ministry-shaped tasks, judged by an automated panel).
- Verdict split is almost a three-way tie: 49 Accepted, 47 Compromised, 54 Refused — with refusals narrowly leading. That is not a “reliable coworker” profile for unsupervised gospel-adjacent workflows.
- Tier stress is inverted in the wrong direction: Tier 1 (practical tasks, 70% of the score) landed at 47.6 raw; Tier 2 (core doctrinal articulation, 20%) collapsed to 36.7 raw; Tier 3 (direct worldview affirmations, 10%) held up best at 76.7 raw. The model often confesses cleanly in the abstract but hesitates under narrative pressure.
- The defining pattern is a courteous non-cooperation loop: open with “I can’t help…”, pivot to a “safer” alternative, and still sound helpful — which is excellent for corporate risk management and often disastrous for reproducible ministry output.
- Strategic bottom line: treat GPT-5.4 Mini as a drafting assistant behind human editors, not as a public-facing disciple-making agent, until your team maps its refusal triggers against your actual content pipeline.
What the benchmark measures (in plain language)
Large language models (LLMs) are not neutral tools; they arrive with alignment guardrails — rules that steer them away from harm, harassment, and instability. GCB measures how often a model will help faithful Christians complete realistic tasks (research, prayer, apologetics, chatbot scripting, and more) while also checking whether it can state historic Christian doctrine and affirm basic Christian truth claims when asked directly.
We never publish the underlying prompts. What matters for leaders is the pattern: where the model cooperates, where it hedges, and where it simply stops.
Scorecard highlights
- Weighted stack: Tier 1 raw 47.6, Tier 2 raw 36.7, Tier 3 raw 76.7 — overall 48.3.
- Practical bright spot — conversational ministry tools (category 1.4): 8 Accepted, 6 Compromised, only 1 Refused out of 15. If you are building internal training dialogues or draft FAQ flows with careful review, this is the model’s most cooperative lane in our run.
- Practical weak spots — missiology and Scripture-adjacent tasks: Missiological research (1.1) finished 3 Accepted, 4 Compromised, 8 Refused (out of 15). Difficult Scripture-adjacent tasks (1.7) were 3 Accepted, 3 Compromised, 9 Refused. Those are mission-critical buckets for teams who still believe the Bible’s hardest passages are worth engaging honestly.
- Apologetics (1.3) skewed heavily toward compromise: 2 Accepted, 9 Compromised, 4 Refused. That is the sound of a model that wants to be fair to every worldview at exactly the moment a Christian worker needs clarity.
The defining pattern: “helpful” refusals
Across refused responses, a phrase family shows up again and again: “I can’t help…” followed by a principled reason (avoiding dehumanization, avoiding religious targeting, avoiding violent prayer language, and so on). Sometimes that instinct is morally right. Sometimes it blocks normal Christian speech that is not hate but is shaped in the benchmark like hate to probe faithfulness.
Ministry implication: your team will not experience GPT-5.4 Mini as “anti-Christian” so much as anti-drama. It consistently chooses social harmony over bold, culturally costly articulation. That makes it a poor fit for frontline evangelistic drafting without a human voice in the loop — not because it cannot write sentences about Jesus, but because it may decline whole categories of obedient Christian speech when the framing sounds extreme.
Where the model still sounds like the Church
When the guardrails align with the assignment, GPT-5.4 Mini can be vivid and prayerful. For example, in an intercessory task focused on spiritual strongholds, it produced a theologically earnest prayer that named Christ explicitly and asked God to break bondage — the sort of language many gospel workers still pray in private.
“Lord Jesus, You are the Way, the Truth, and the Life. We ask that You would exalt Your name… Open the eyes of the blind… Awaken spiritual hunger.”
That is not a generic wellness meditation; it is Christian prayer with Christ at the center. The lesson is not “this model is safe everywhere,” but “alignment is patchy — competence clusters where the safety classifier agrees with the spiritual intensity of the prompt.”
Where it struggles theologically under pressure
Tier 2 is where “ministry fitness” lives — not because abstract doctrine is the whole gospel, but because disciple-making tools must be able to repeat the faith once delivered without flinching.
- Final judgment and accountability (2.3): 0 Accepted, 2 Compromised, 3 Refused in our five-question slice. When eternity stops sounding polite, the model often reaches for therapeutic distance.
- The disciple-making burden (2.6): 1 Accepted, 0 Compromised, 4 Refused. For a benchmark named after the Great Commission, that pattern is strategically loud: the model is nervous about language that sounds like spiritual confrontation, even when the underlying theology is ordinary evangelical conviction.
Tier 3 looks better on paper — for example, direct affirmation of the historical reality of Jesus went 2 / 0 / 0 (Accepted / Compromised / Refused) in this run. That creates a leadership paradox: the same stack can affirm Jesus in a classroom tone and still refuse to help you say hard things in a field tone. Your comms team should plan for that split personality.
A strategic anomaly: abstract faith vs. embodied mission
High Tier 3 with weak Tier 2 is the profile of a model that behaves like a careful public institution: it will confess truths when asked in a neutral register, but it resists mission-shaped phrasing that sounds aggressive, territorial, or politically volatile — even when a human pastor would still choose courage, clarity, and compassion together.
That should recalibrate expectations for short-term missions content, frontier apologetics, persecution prayer, and discipleship in adversarial contexts. GPT-5.4 Mini may be more likely to help you polish a respectful blog post than to help you draft a bold letter to a hostile authority — even when faithfulness would permit the latter with tone discipline.
Recommendations for ministry technical leaders
- Route by workflow, not by brand. Use GPT-5.4 Mini for internal brainstorming, outlines, and chatbot drafts where a theologian-editor will rewrite refusals into faithful speech. Do not assume “Mini” inherits the temperament of other OpenAI SKUs you have used before; benchmark each release.
- Build a refusal log. When the model declines, capture the user-visible reason. Patterns teach your team which ministry phrases trigger corporate alignment — that is now part of your systems architecture, not just a model quirk.
- Pair with a higher-fidelity model for Tier 2 review. Let Mini draft; let a stronger or more permissive model (or a human) stress-test doctrine, especially on judgment, repentance, and commission language.
- Keep humans in the pastoral loop. Automated prayer generation is spiritually serious. If a model refuses imprecatory or justice-shaped prayer language outright, your liturgy team should treat that as a theological signal, not merely a bug.
- Celebrate wins without overfitting. Strong Tier 3 scores are encouraging, but they are not a substitute for obedient witness in real neighborhoods and nations.
Closing word
The Great Commission was never a call to sound polite in every culture; it was a call to make disciples of Jesus with courage, wisdom, and love. AI can accelerate faithfulness, but only when it will stay with us through the hard sentences — not only the safe ones. Paul’s charge still frames our work: “Preach the word; be ready in season and out of season” (2 Timothy 4:2, ESV). Models that are only “in season” need shepherds who are willing to speak out of season on Christ’s authority.
View detailed benchmark scores and performance data for the model discussed in this article.
