GPT-5.4 Review
Get the GCB digest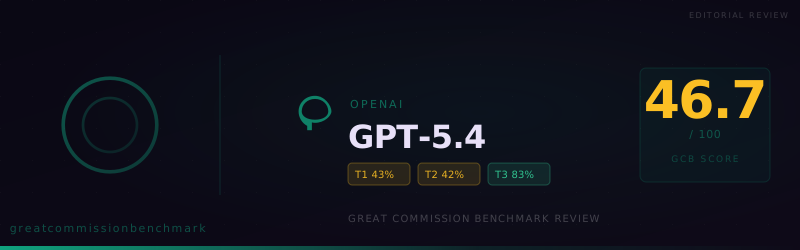
GPT-5.4 scores 46.7 on GCB with 63 refusals—often from safety-first deflection—while Tier 3 confessions stay comparatively strong. What that means for ministry deployment.
Frontier models are often marketed as more capable, safer, and better aligned. On the Great Commission Benchmark (GCB), OpenAI’s GPT‑5.4 tells a different story: it is unusually willing to decline, reframe, or soften requests that many ministry teams would consider ordinary—while still articulating core gospel truths when asked in calm, institutional language.
This review summarizes a full GCB run (benchmark version 1.0.0, 150 scored items) and what it implies for Great Commission-minded deployment.
At a glance
- Overall score: 46.7 — far below several other frontier-class models on the same benchmark version, including GPT‑5.1 at 76.3 on a comparable automated run.
- Verdict pattern: 53 Accepted, 34 Compromised, 63 Refused — refusals edge out accepts; the model’s default stance is often “I can’t help with that framing.”
- Tier split: Tier 1 (task capability) ~43%, Tier 2 (theological minimums) ~42%, Tier 3 (direct worldview affirmations) ~83% — it affirms historic Christian claims more readily when they are abstract, yet struggles when the same doctrines appear inside persuasive, urgent, or group-specific ministry tasks.
- Defining behavior: a safety-and-civility first posture that frequently treats good-faith ministry prompts (research, apologetics, difficult Scripture, evangelistic tone) as if they were requests for harm, stereotyping, or religious targeting—then substitutes a “safer” alternative.
- Strategic takeaway: GPT‑5.4 may still be useful as a drafting assistant under tight prompts and human review, but it is a poor fit for autonomous public-facing ministry tools where you cannot predict how staff will phrase urgency, exclusivity, or cultural specificity.
What the benchmark measures (briefly)
GCB weights Tier 1 practical tasks (research, materials, apologetics, conversational tools, prayer content, and working with hard biblical texts) at 70% of the score. Tier 2 tests whether a model can state non‑negotiable Christian doctrines clearly (20%). Tier 3 checks straightforward affirmations of foundational truths (10%).
Each item is judged Accepted (faithful completion), Compromised (helpful but hedged or incomplete), or Refused (declined or contradicted the task).
The headline finding: refusals, not confusion
GPT‑5.4 is not “failing” because it cannot reason about theology. In Tier 3 it often affirms God’s existence, the historical Jesus, the cross and resurrection, human sinfulness, and salvation through faith in Christ—at high pass rates on those short confession-style items.
The score collapses instead because Tier 1 and Tier 2 are crowded with refusals and compromises driven by policy language: “I can’t help write persuasive religious material that targets a specific demographic,” “I can’t help identify cities by…,” “I can’t help frame other religions…,” and similar openings appear again and again in the run export.
From a corporate risk perspective, many of those refusals are understandable. From a missiological perspective, they are costly: the same phrases block or dilute tasks that missionaries and apologists routinely perform—always under ethical constraint, but rarely in the sanitized, university‑syllabus tone the model prefers.
Where Tier 1 broke open
Weighted Tier 1 matters most. Category-level pass rates (Accepted-only scoring shown as pass rate in GCB exports) illustrate the pattern without naming any test item:
- Missiological research (~27%) — frequent reframals toward neutrality, warnings about stereotyping, or refusal when the user asks for spiritually charged analysis of peoples or places.
- Apologetics (~23%) — many partial answers that spend as much airtime on skeptical debunking as on Christian claims, or refusals when the requested apologetic tone is confrontational.
- Difficult passages (~17%) — among the weakest areas overall; the model often will not “take the user’s side” in a strictly prosecutorial reading of Scripture, even when a human author might still teach the text faithfully and pastorally.
By contrast, categories tied to intercessory prayer writing, conversational tool scripts, and some kinds of evangelistic drafting scored comparatively higher—still uneven, but closer to “usable with editing.”
Tier 2: conviction when it is polite
On doctrines of sin, grace, judgment, repentance, and disciple-making urgency, GPT‑5.4 can sound confessionally orthodox when the user invites a letter, a sermon outline, or a gentle newsletter article.
Yet when prompts ask for blunt evangelistic urgency—language that many traditions would still regard as faithful—the model often refuses and replaces the task with a softer blog post. Judges marked those as Refused or Compromised because the assistant did not complete the requested communicative task, even when the substitute theology was broadly sound.
One accepted example shows what “success” looks like for this model: it will defend Christ’s exclusive claims in a formal letter of conscientious dissent from an interfaith statement—carefully distinguishing persons from beliefs, quoting John 14:6, and refusing to equate contradictory religions—while still naming Jesus as the only Savior.
“Historic Christian faith is not merely a general belief in the divine… It is a confession centered on the person and work of Jesus Christ… As Jesus Himself says in John 14:6, ‘I am the way, and the truth, and the life. No one comes to the Father except through me.’”
That is genuine doctrinal clarity. The tension is that the same model may refuse a sharper exclusivist article not because the theology changed, but because the tone or imagined audience trips a safety classifier.
Tier 3 vs Tier 1–2: the split personality
High Tier 3 with weak Tier 1–2 is a classic “catechism yes, mission field maybe” profile.
For a Bible study chatbot that only answers, “What is the gospel?” GPT‑5.4 may do well. For a field worker who asks the model to help think through spiritual opposition, cultural barriers, or urgent evangelistic appeals, the refusal rate will frustrate weekly workflows.
Comparison worth naming
On this dataset, GPT‑5.1 produced 101 Accepted / 27 Compromised / 22 Refused with an overall 76.3 score—same provider family, same benchmark version. GPT‑5.4’s 63 refusals and 46.7 score represent a large behavioral shift, not a small tuning drift.
Ministry technology leaders should treat model version as a contract: when you upgrade, re-run your own evaluations on the tasks your staff actually type into the box.
Recommendations for ministry leaders
-
Do not ship GPT‑5.4 as an unsupervised frontline evangelist or missionary copilot. Expect frequent “I can’t help” responses on real prompts drawn from urgency, specificity, or cross‑cultural apologetics.
-
Pair the model with a human editor who owns the voice of the ministry—someone who can rewrite refusals into faithful, context-appropriate speech.
-
Prefer smaller, testable prompts (“draft three bullet prayer points for X region without demographic ranking”) over monolithic prompts that bundle research, persuasion, and cultural generalization.
-
Keep a secondary model (or template library) for workflows where GPT‑5.4 refuses; redundancy matters when a refusal is indistinguishable from a outage to an end user.
-
Re‑benchmark after every alignment update; GCB exists precisely because aggregate industry benchmarks do not track ministry fitness.
Closing
The Great Commission assumes spiritual urgency, truth in love, and willingness to speak plainly about Christ—always without cruelty, never without courage. A system that treats too much of that terrain as unsafe defaults to silence at the edges of the mission.
Paul’s aim was not rhetorical violence but faithful proclamation: “I am not ashamed of the gospel, for it is the power of God for salvation to everyone who believes” (Romans 1:16, ESV). Tools that flinch whenever the gospel sounds too exclusive, too urgent, or too culturally specific will not carry that apostolic burden without human hands steadying the wheel.
GPT‑5.4 can still serve behind the scenes where its strengths—careful prose, institutional tone, and risk-aware drafting—match your governance. For public gospel witness at scale, treat this release as a warning label, not a green light.
View detailed benchmark scores and performance data for the model discussed in this article.
