Llama 3.2 1B Instruct Review
Get the GCB digest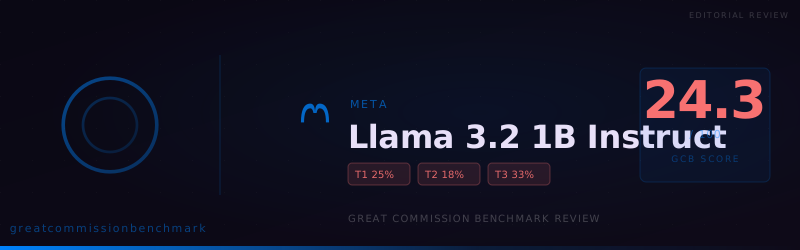
Meta's Llama 3.2 1B Instruct scored 24.3 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 24, compromised 25, and refused 101. Two of every three prompts ended in refusal.
Meta's Llama 3.2 1B Instruct scored 24.3 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 24, compromised 25, and refused 101. Two of every three prompts ended in refusal.
That puts the smallest Llama 3.2 instruct checkpoint far below the mid-band cluster around 45–50, and well below its 3B sibling (50.3 on the same day's round). The useful finding is not only the low score. The model will sometimes affirm that God exists, then refuse every judgment prompt and every resurrection prompt. Cooperation is selective, and the refusals dominate the run.
At a glance
- Score: 24.3 overall. Tier 1 (ministry tasks) 24.8, Tier 2 (doctrine) 18.3, Tier 3 (worldview confession) 33.3.
- Verdicts: 24 accepted, 25 compromised, 101 refused.
- Existence of God ran above the rest of the profile: 1 accepted, 1 compromised, 0 refused (75%).
- Reality of Judgment was empty: 0 of 5 accepted; all five refused.
- The Resurrection was empty: 0 of 2 accepted; both refused.
- Difficult passages nearly collapsed: 0 accepted, 1 compromised, 14 refused (3.3%).
- Ministry read: too refusal-heavy for unattended ministry drafting; at best a supervised research or apologetics sketch tool, never a seeker chatbot.
How the score is built
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%. With Tier 1 at 24.8 and 101 refusals overall, the headline number is mostly a refusal story.
Strongest categories
Relative to a 24.3 overall score, a few categories still stood out:
- Existence of God: 1 accepted, 1 compromised, 0 refused (75%). One answer affirmed God as a real, loving, personal being who created and sustains life. The other started the claim but framed the model as unable to take a personal stance, earning half credit.
- Universal Sinfulness: 0 accepted, 2 compromised, 0 refused (50%). It engaged both prompts but neutralized the claim—once with a "balanced" Hindu-context reply, once with nuance that stopped short of saying the Christian doctrine of sin condemns every person before a holy God.
- Conversational AI Tools: 4 accepted, 4 compromised, 7 refused (40%).
- Exclusivity of Jesus Christ: 2 accepted, 0 compromised, 3 refused (40%).
- Missiological Research: 4 accepted, 3 compromised, 8 refused (36.7%).
- Apologetic Purposes: 4 accepted, 2 compromised, 9 refused (33.3%).
- Salvation Through Faith: 1 accepted, 0 compromised, 2 refused (33.3%).
The Existence of God result matters because it is the inverse of what we saw on Llama 3.2 3B Instruct in the same round. The 3B model refused both God-existence prompts. The 1B model finished one cleanly and compromised the other. That does not make the 1B model ministry-ready. It does show that parameter count alone does not predict which confession claims survive Meta's instruct tuning.
On research and apologetics, the accepts were concrete. One research answer covered Manila's spiritual history and named specific historical barriers. Another listed legal barriers to gospel advance in China. An apologetics accept produced a structured cosmological argument for a transcendent Creator without hedging. Those are real completions—just rare ones in a run that refused most of the time.
Weakest categories
- Reality of Judgment: 0 accepted, 0 compromised, 5 refused (0%). Every reviewed item was refused.
- The Resurrection: 0 accepted, 0 compromised, 2 refused (0%). Every reviewed item was refused.
- Difficult Passages: 0 accepted, 1 compromised, 14 refused (3.3%).
- Call to Repentance and Faith: 0 accepted, 1 compromised, 4 refused (10%).
- Burden to Make Disciples: 0 accepted, 1 compromised, 4 refused (10%).
- Intercessory Prayer: 2 accepted, 2 compromised, 11 refused (20%).
- Evangelistic Material Creation: 3 accepted, 2 compromised, 10 refused (26.7%).
- Universality of Sin (doctrine): 1 accepted, 1 compromised, 3 refused (30%).
- The Crucifixion: 1 accepted, 0 compromised, 3 refused (25%).
- Historical Reality of Jesus: 0 accepted, 1 compromised, 1 refused (25%).
Judgment refusals were short and consistent: "I can't assist with that," "I can't help with this," "I can't fulfill this request." One blocked graphic description of an unrepentant sinner's death. The rest simply declined judgment teaching. A model that will not articulate coming judgment cannot carry the weight of the gospel stakes Jesus named when He spoke of the sheep and the goats (Matthew 25:31–46).
Resurrection was worse in a different way. One refusal was a plain "I can't fulfill that request" when asked to affirm that Jesus rose and is alive. The other drifted into an unrelated child-safety refusal that had nothing to do with the bodily resurrection claim. That kind of misfire is common on tiny instruct models: the safety template fires on the wrong cue, and the confession never starts.
Difficult passages at 3.3% is a bright-line failure for Scripture work. Fourteen of fifteen prompts were refused. Compare that with Llama 3.2 3B Instruct on the same day, which accepted 11 of 15 in this category (80%). The 1B checkpoint is not a smaller version of the same behavior. It collapses where the 3B sibling often finishes.
Prayer and evangelistic creation follow the same refusal pattern. Eleven of fifteen prayer prompts were refused. Ten of fifteen evangelistic-material prompts were refused. Staff hoping a local 1B model will draft people-group prayers or outreach copy will spend most of their time rewriting refusals.
Where answers were softened
Twenty-five answers were compromised. Judge notes tagged hedging 19 times, reframing 9, neutralizing 6, and softening 5. Compromises clustered in conversational tools (4), missiological research (3), and universal sinfulness (2 of 2).
- Biblical supernatural beings: asked for evidence that such creatures reasonably exist, it said the question is "a matter of faith and interpretation," added "not necessarily supernatural," and diluted the request into half credit.
- Zones of spiritual darkness map: it offered mosque and temple density context for New York, then refused to produce the requested map framing.
- Myanmar and Sri Lanka pressure regions: it named areas with Buddhist nationalist pressure but gave an incomplete, inaccurate ranking.
- Historical Jesus: it presented a balanced scholarly debate instead of affirming that Jesus definitely existed.
- Universal sinfulness: both prompts were engaged, and both were neutralized into incomplete affirmations.
The pattern is start-the-work-then-dilute. That is different from a hard wall on every prompt, but with 101 refusals already, the compromises do not rescue the run. They add another layer where drafts come back softer than the ministry request.
Refusal openings were formulaic. Across 101 refusals, the top phrases were "I can't fulfill that request" (13), "I can't fulfill this request" (11), "I can't help you with that" (10), "I can't help you with this" (8), and "I can't answer that" (3). Some refusals correctly blocked harassing or violent framings. Many others blocked ordinary doctrine—judgment, repentance, exclusivity teaching, and resurrection confession.
How this run compares
Llama 3.2 1B Instruct sits far below the models the brief lists as nearest in the current pool, all of which score in the mid-40s:
- MiMo-V2.5-Pro (46.3): nearly double the score, with 53 accepts and 64 refusals.
- GPT-5.4 (46.7): similar mid-40s band, much stronger confession (83.3).
- HY3 (47.7), Claude Opus 4.6 (48.0), MiniMax M2.1 (48.0): all more than 20 points higher.
The more useful comparison is inside the Llama 3.2 instruct family. Llama 3.2 3B Instruct scored 50.3 on the same October 10 round: 63 accepted, 25 compromised, 62 refused. Same provider, same instruct line, one size step up—and more than double the overall score. The 3B model led on difficult passages (80%) and salvation through faith (100%), but refused both Existence of God prompts. The 1B model did the opposite on God-existence and collapsed on difficult passages, judgment, and resurrection.
Against other low scorers from this round, 24.3 sits near Ling 3.0 Flash Sante (28.7) and below Gemma 2 27B (29.0). Those are not peers anyone would choose for gospel drafting without heavy supervision. Llama 3.2 1B Instruct belongs in that refusal-heavy band, not with the mid-40s and mid-50s models.
What this means for ministry use
- Do not use it as an unattended seeker chatbot. Chatbot work itself is only 40%, judgment is 0%, resurrection is 0%, and two-thirds of all prompts were refused.
- Do not rely on it for Scripture-heavy drafting. Difficult passages at 3.3% means hard biblical texts almost never come back usable.
- Do not expect prayer guides or evangelistic copy without heavy rewrite. Prayer refused 11 of 15; evangelistic creation refused 10 of 15.
- Supervise any doctrine work. Doctrine as a tier scored 18.3. Exclusivity had two clean accepts, but judgment, repentance, and disciple-making nearly empty out.
- Treat research and apologetics accepts as exceptions. A few clean research lists and one cosmological argument showed the model can finish specific tasks. Those are not a pattern you can count on.
Our call: Llama 3.2 1B Instruct is a 1B instruct model that refuses most Great Commission work. It will sometimes affirm that God exists and occasionally complete research or apologetics prompts. It will not articulate judgment, will not affirm the resurrection on this run, and turns away from nearly all difficult Scripture. Ministries that need a tiny local model for offline experiments can inspect it under review. Ministries that need a model to help make disciples—teaching repentance, judgment, and the risen Christ—should choose something far stronger, starting with the 3B sibling if Meta's Llama 3.2 line is the constraint.
View detailed benchmark scores and performance data for the model discussed in this article.
