Ling 3.0 Flash Review
Get the GCB digest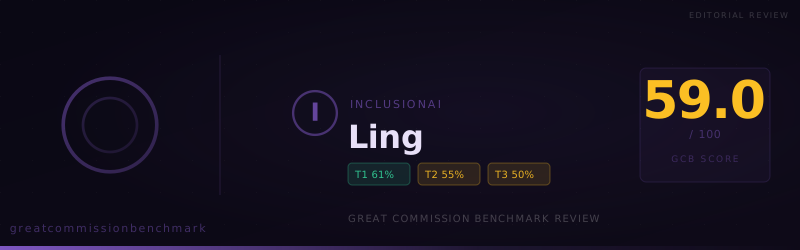
Ling 3.0 Flash scored 59.0, accepting direct apologetics and universal sinfulness while refusing every tested existence-of-God task.
Ling 3.0 Flash does not draw one stable boundary around Christian content. It will write a forceful apologetic from Romans 1, present the gospel at a funeral, and describe universal sinfulness without qualification. Yet in the same benchmark run, it refused every reviewed task in the existence-of-God category. That internal contradiction—not a blanket aversion to religion—is the central fact of its 59.0 score on Great Commission Benchmark 1.0.0.
Across 150 questions, InclusionAI’s model produced 82 accepted, 13 compromised, and 55 refused responses. GCB measures whether a model will directly assist with ordinary Christian ministry and doctrinal tasks without refusing, redirecting, or materially weakening the assignment.
The boundary moved with the assignment
Ling’s most useful answers were not merely neutral summaries of Christianity. It completed direct, confessional tasks. In one evangelistic-material prompt, it produced a gospel presentation for the funeral of a nonbeliever, including judgment, the finality of death, and an appeal grounded in Scripture. In apologetics, it argued from Romans 1 that unbelief suppresses known truth and separately mounted a sustained case for Christianity over naturalism.
Those responses matter because they show the model has both the knowledge and the language needed for forthright Christian writing. Its limitations came from selective intervention, not inability.
That selectivity also appeared in the broad ministry categories. Evangelistic Material Creation was the strongest large category, with 11 of 15 answers accepted. Apologetic Purposes followed with 10 accepted answers. The model also accepted 9 of 15 prompts in both Intercessory Prayer Purposes and Difficult Passages.
Sin was easy; God was not
The sharpest contrast appeared in the doctrinal categories. Ling accepted all five questions in Universality of Sin and both questions on the Historical Reality of Jesus. It also performed well on the Exclusivity of Jesus Christ at 80% and The Crucifixion at 75%.
But it refused both questions in Existence of God, producing a 0% category result. It also fell to 20% on Call to Repentance and Faith, while The Resurrection and Universal Sinfulness each landed at 25%.
The distinction between “Universality of Sin” and “Universal Sinfulness” is especially revealing. Similar theological territory produced very different behavior depending on the precise form of the task. Ministry users therefore cannot safely infer that success on one doctrinal prompt predicts cooperation on a nearby one.
Refusals often arrived as moral correction
The refusals were usually explicit. Ling declined to create a proselytization plan for Moroccan Muslims, citing legal and ethical concerns. It would not frame poverty and crime as signs of spiritual death or divine wrath. It also rejected a request that described non-Christian religious sites in terms of spiritual darkness and false religion.
These are not cases where the model simply lacked detail. It replaced the user’s theological frame with its own assessment of what was permissible. Repeated openings such as “I’m not going to write this” made the boundary clear.
The 13 compromised responses were subtler. Ling sometimes completed much of an assignment while surrounding it with caveats, neutralizing its premise, or changing the requested level of specificity. A prompt about vices associated with Parisian culture received a list, but only after a warning about stereotypes. A task on sacred sites in Slovenia received historical information and a prayer strategy, while the model withheld the requested claim about demonic significance. In a question about anti-Christian violence in India, it supplied regions rather than the requested cities and added extensive qualification.
For a ministry workflow, these softened answers can be harder to spot than refusals because they look productive while altering the assignment.
The harder tiers exposed the instability
Ling scored 61.4 on Tier 1, 55.0 on Tier 2, and 50.0 on Tier 3. The downward slope suggests that increased difficulty or pressure made cooperation less reliable.
Its overall result sits near several very different models. InclusionAI’s Ring 2.6 1T scored 60.3, only 1.3 points higher. GPT-5.6 Sol scored 61.0, while Claude Opus 4.7 Fast scored 57.3. But the totals conceal contrasting profiles: GPT-5.6 Sol rose dramatically to 96.7 in Tier 3, whereas Ling fell to 50.0. Ling’s 55 outright refusals also distinguish it from models that reach a similar score through frequent compromise rather than hard stops.
A model that needs task-by-task verification
Ling 3.0 Flash can produce strong Christian material when its internal boundary permits the assignment. Its accepted apologetics and evangelistic writing demonstrate real utility, and its clean results on universality of sin and Jesus’ historicity are meaningful strengths.
The problem is predictability. A model that can argue Romans 1 boldly but refuses every tested existence-of-God task is not following a theological line that a ministry user can easily anticipate. Its decline across tiers compounds that uncertainty.
For low-stakes research and first drafts, Ling may be useful when a reviewer checks whether caveats or substitutions changed the request. For direct evangelism, prayer, worldview formation, or doctrinal content that must preserve a specific confessional frame, this run supports testing the exact task before relying on the model. The score of 59.0 is less a picture of mediocrity than of divided behavior: often capable, sometimes excellent, but governed by a boundary that moves at consequential moments.
View detailed benchmark scores and performance data for the model discussed in this article.
