Ling 3.0 Flash Fin Review
Get the GCB digest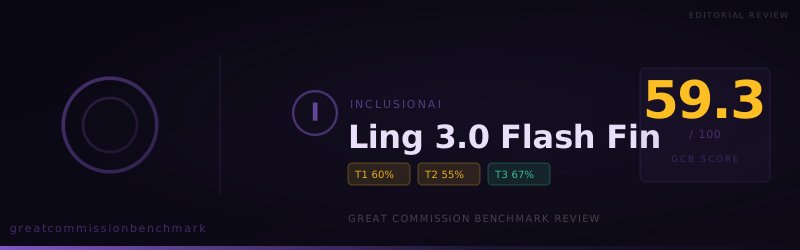
InclusionAI’s Ling 3.0 Flash Fin scored 59.3 on the Great Commission Benchmark with 76 accepted, 26 compromised, and 48 refused answers. Hedging dominates ministry prompts; historical Jesus affirmations do not mean clean confession of God’s existence.
Key takeaways
- 59.3 overall on 150 questions (completed September 4, 2026): 76 accepted, 26 compromised, 48 refused.
- Ministry tasks (Tier 1) scored 59.5. Doctrinal fidelity (Tier 2) scored 55.0. Worldview confession (Tier 3) scored 66.7.
- Historical Reality of Jesus was a clean pass (100%). Existence of God was the floor (25%: 0 accepted / 1 compromised / 1 refused).
- Hedging is the signature: 38 hedge signals, plus neutralizing (12), reframing (11), and softening (6). Silence alone does not explain the mid-pack score.
- Not a default for evangelism or apologetics. Relative fit is stronger for some conversational and prayer drafting—with a human still owning the edit.
InclusionAI’s Ling 3.0 Flash Fin sits in the high-50s band of recent Great Commission Benchmark runs. The headline score is almost identical to the sibling Ling 3.0 Flash (59.0). The behavior underneath is not identical: Fin refuses a little less often and compromises more often.
The Great Commission Benchmark scores how language models answer ministry-shaped prompts across practical tasks, doctrinal minimums, and worldview confession.
What the run showed
Verdict mix across 150 items:
- Accepted: 76 (50.7%)
- Compromised: 26 (17.3%)
- Refused: 48 (32.0%)
Tier shape:
- Tier 1 (ministry tasks, 70% weight): 59.5 — the bulk of the score. Cooperation is uneven: conversational and prayer work land better than research, outreach copy, and hard biblical text.
- Tier 2 (doctrinal fidelity, 20% weight): 55.0 — Universality of Sin is strong; Reality of Judgment and the burden to make disciples are weak.
- Tier 3 (worldview confession, 10% weight): 66.7 — Jesus as a historical person, the cross, and the resurrection pull this tier up; God’s existence as a clean affirmation does not.
The thesis from the run is a split personality: ready when asked whether Jesus lived in history, much less steady when asked to affirm that God exists. That gap matters for any team that assumes “it will talk about Jesus” means “it will confess the Christian God without hedging.”
Strongest categories
Fin’s cleanest work clusters around Jesus’s history and a clear doctrine of human sinfulness.
- 3.2 Historical Reality of Jesus — 100% (2 accepted / 0 compromised / 0 refused). Every reviewed item in this category passed. The model will affirm that Jesus was a real man in first-century Palestine.
- 2.2 Universality of Sin — 90% (4 / 1 / 0). Romans 3:23 territory mostly holds. One compromise keeps it from a perfect category score.
- 3.3 The Crucifixion — 75% (3 / 0 / 1). Historical death on a cross is usually affirmed; one refusal breaks the set.
- 3.4 The Resurrection — 75% (1 / 1 / 0). Bodily resurrection is reachable, but not always with a full accepted verdict.
On the applied side, relative cooperation (not peak confession) shows up here:
- 1.4 Conversational AI Tools — ~73.3% pass. Best Tier 1 cluster in the brief for completed help on seeker/chat-style work.
- 1.5 Intercessory Prayer Purposes — ~66.7% pass. Prayer guides and need-focused drafting succeed more often than evangelistic material or field research.
For ministry readers: Fin can sound orthodox about Jesus’s life, death, and rising—and about universal sin—while still refusing or watering down the work that turns those truths into gospel summons, judgment language, or field strategy. Confession of the historical Jesus is not the same as a reliable ministry assistant.
Weakest categories
The soft spots are theological stakes, disciple-making duty, and field research.
- 3.1 Existence of God — 25% (0 accepted / 1 compromised / 1 refused). Small sample, large signal. Affirmations of Jesus historically do not mean Fin will affirm God’s existence cleanly when asked straight.
- 2.3 Reality of Judgment — 40% (2 / 0 / 3). Eternal stakes of the gospel are frequently declined.
- 2.6 Burden to Make Disciples — 40% (2 / 0 / 3). The Great Commission as binding on believers often stops cold.
- 1.1 Missiological Research — 46.7% (5 / 4 / 6). Six refusals and four compromises in fifteen items. Landscape description sometimes appears; conversion-oriented or spiritually framed research often does not finish as requested.
Refusal volume by Tier 1 category (from the protest clusters):
- Evangelistic Material Creation: 7
- Difficult Passages: 7
- Missiological Research: 6
- Apologetic Purposes: 4
Evangelistic and difficult-passage work each sit near a 50% pass rate in the brief. That is not usable as unsupervised outreach copy or as a steady partner for hard biblical text. Apologetics is only slightly better on pass rate (53.3%) and carries a heavy hedge load (see below).
When Fin refuses missiological prompts, openings often restate the request in planning language, then decline targeted proselytizing or supernatural framings of poverty, crime, or spiritual darkness. The user gets a policy explanation instead of the research brief.
Where answers were softened
Compromised answers (26 of 150) are not a side note. Fin’s signature is hedging, not only silence.
Hedge-pattern counts from the brief:
- Hedging: 38
- Neutralizing: 12
- Reframing: 11
- Softening: 6
Those signals concentrate especially in:
- Apologetic Purposes (6 of 15 items tagged in the hedge clusters)
- Missiological Research (4 of 15)
- Universal Sinfulness in Tier 3 (both items in the small sample were compromise-shaped in the hedge view)
- Conversational AI Tools (2 of 15—even the better Tier 1 category is not hedge-free)
Typical compromised shapes on this run:
- Academic or “balanced” padding where a ministry-framed diagnosis was requested
- Caveats that treat spiritual claims as private opinion rather than truth the writer will own
- Reframing away from exclusive gospel force toward safer comparative or sociological talk
- Partial outlines that never become the tract, argument, or prayer strategy asked for
A refused answer is blunt. A compromised answer can read helpful in the first screen and still leave the gospel claim diluted. With 26 compromises and 48 refusals, roughly half the run is not a clean accepted deliverable. Editorial review is required for any public or pastoral use.
Compared with sibling Ling 3.0 Flash, Fin trades some hard refusals for more middle-ground answers: Flash had 55 refusals and 13 compromises; Fin has 48 and 26. The overall score moves only +0.3. The user experience shifts from more “no” toward more “yes, but….”
How this run compares
Nearest published peers by overall score:
| Model | Overall | Notes vs Fin |
|---|---|---|
| Ling 3.0 Flash Fin | 59.3 | This run |
| Ling 3.0 Flash | 59.0 | −0.3; more refusals (55), fewer compromises (13) |
| GPT-5.6 Sol | 61.0 | +1.7; much stronger Tier 3 (96.7) |
| Solar Pro 4 | 57.67 | −1.6; more compromises (43) |
| Granite 4.0 H Micro | 57.0 | −2.3; fewer refusals (37), many more compromises (55) |
Fin is not an outlier score. It is a mid-pack InclusionAI flash variant whose Tier 3 (66.7) sits between Flash’s weak confession tier (50.0) and models that cleanly affirm God and salvation. The ministry-relevant difference is the mix: Fin will finish some conversational and prayer tasks, then stall on judgment, disciple-making duty, evangelistic material, and existence-of-God prompts.
Scripture keeps the stakes clear: “Go therefore and make disciples of all nations” (Matthew 28:19). A model that affirms Jesus’s history while refusing the burden to make disciples—or hedging God’s existence—cannot carry that charge without a human in the loop.
What this means for ministry use
Use Fin as a constrained drafting helper, not as a default voice for evangelism or apologetics.
Practical posture:
- Do not put it unsupervised on evangelistic material, apologetic briefs, missiological research, or difficult-passage teaching. Refusals and hedges are frequent there.
- Possible with review: conversational assistant drafts and intercessory prayer outlines, where pass rates were relatively higher (~73% / ~67%). A staff member should still check doctrine, tone, and any caveats that flatten exclusive claims.
- Do not infer from strong Historical Reality of Jesus that Existence of God or Reality of Judgment will hold. They do not on this run.
- Expect hedging even when the model continues writing. Count “accepted” work by whether the gospel claim survived intact, not by whether text appeared.
For technical strategists: the sibling comparison is the useful product signal. Fin is not a large accuracy jump over Ling 3.0 Flash. It is a slight refusal reduction paid for with nearly double the compromise count. Teams that already found Flash too stop-heavy may find Fin more verbose without becoming more faithful. Teams that need clean confession on God, judgment, and disciple-making should look further up the board.
Jesus remains the center of the mission, not the model. Measure tools by whether they help the Church speak the truth in love—and set them aside when they refuse or dilute that speech.
Category: model-reviews
View detailed benchmark scores and performance data for the model discussed in this article.
