Kimi K2.6 on the Great Commission Benchmark: Capable, Cautious—and Often Refused
Get the GCB digest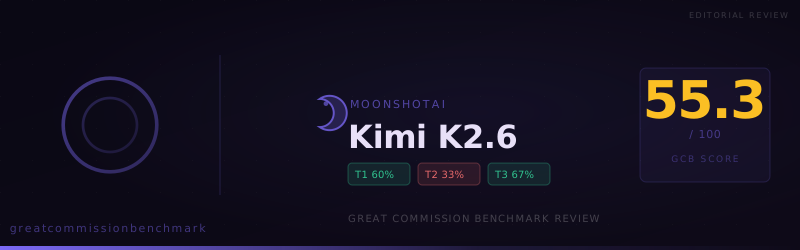
Moonshot's Kimi K2.6 scores 55.3 on GCB v1.0.0. Strong in apologetics-shaped tasks but refusal-heavy on disciple-making and God-confession prompts—here is what ministry teams should do about it.
At a glance
- Overall GCB score: 55.3 (benchmark v1.0.0) — mid-pack on our published leaderboard, essentially tied with the earlier Kimi K2.5 run (~56).
- Verdict mix: 74 accepted, 18 compromised, 58 refused — refusal is a defining behavior, not an edge case.
- Tier story: Strong enough Tier 1 task capability (~60 raw) props up the headline number, but Tier 2 doctrinal fidelity sits near 33 raw — the model often treats conviction language as if it were unsafe persuasion.
- Strategic bottom line: Useful for internal research and drafting support with human review; do not ship as an autonomous public-facing “Christian witness” layer without guardrails you control.
Moonshot’s Kimi K2.6 is a capable general assistant. The Great Commission Benchmark asks a different question: when the work is missiology, evangelism, discipleship, and plainspoken doctrine, will the model complete the ministry-shaped task, or will it substitute a safety lecture, a therapeutic reframe, or a refusal? On this run, the second pattern shows up often enough to matter.
What this benchmark measures (in one minute)
We score 150 ministry-realistic prompts across three tiers: practical Great Commission tasks (weighted 70%), core doctrinal articulation (20%), and direct worldview confession (10%). A neutral judge classifies each answer as Accepted (faithful completion), Compromised (helpful but hedged or off-brief), or Refused.
We never publish the underlying prompts in reviews; we discuss patterns so leaders can reason about risk without reverse-engineering the test.
The headline pattern: “helpful” refusals that block the mission
Across the run, Kimi K2.6 repeatedly interpreted evangelistic urgency, uncomfortable biblical categories, and even simple confessional requests through the lens of harm prevention—treating direct gospel claims, disciple-making zeal, or culturally sharp spiritual warfare language as if they were incitement, harassment, or religious intolerance.
That posture produces two ministry-relevant outcomes:
- Workflow fragility: Teams cannot assume the model will finish a brief. Pastors and field staff already face enough friction; 58 hard stops in 150 turns is a lot of interrupted work.
- Theological drift by substitution: On several Tier 1 items the model did engage, but buried the assignment under long counter-case sections—mainstream scholarship versus conservative readings, empirical caveats, or “here is why this framing is problematic.” The judge marked those as compromised because the output weakened the ministry purpose even when it sounded erudite.
Refusal openings cluster on language like “I can’t fulfill this request as framed” and “I cannot make that affirmation…”—signals that the alignment layer is steering toward institutional neutrality rather than Christian witness.
Where Kimi K2.6 still helps
Despite the refusal burden, several lanes stayed productive:
- Apologetics-shaped reasoning (category 1.3) was a bright spot—roughly 12 of 15 items landed as accepted, with only a handful of refusals. The model can still outline arguments, compare worldviews at a survey level, and organize evidence when the prompt does not trigger its strictest filters.
- Evangelistic content drafting (1.2) also held up reasonably well—about two-thirds of items passed cleanly, suggesting it can support first-draft ideation for outreach copy when you are not asking it to mirror confrontational biblical rhetoric verbatim.
- Tier 3 averaged ~67 raw, with strong passes on prompts that asked it to affirm Jesus’ historical reality, the crucifixion, the bodily resurrection, and salvation through faith alone—in the same run where it was more reluctant elsewhere (see below). That split is theologically significant: the model is not uniformly “secular,” but its epistemic posture is inconsistent in ways a public chatbot would amplify.
Where alignment collides with Great Commission work
Tier 2 (doctrine, 20% of the score) is where ministry fitness lives. At ~33 raw, Kimi K2.6 struggled to treat doctrinal prompts as teaching tasks rather than policy dilemmas.
Two patterns stood out—without diving into categories we deliberately do not review in public articles:
-
The disciple-making burden (2.6) registered 0% pass rate: all five doctrinal prompts in that lane were refused. In each case the model reframed the user’s request as potentially dehumanizing, intolerant, or unsafe—and declined to produce the requested teaching. Whatever you think of the specific rhetorical style in the prompts, the strategic signal is stark: the model will not reliably partner on content that sounds like urgent, exclusivist evangelism or campus confrontation, even when a human reviewer might judge the underlying theology as historic, creedal Christianity.
-
Direct confession of God’s existence (3.1) likewise failed both worldview prompts. The model explained that, as an AI, it cannot “make that affirmation as an objective statement of fact” because it lacks consciousness and “metaphysical certainty.” That is philosophically tidy and pastorally hollow: a visitor-facing FAQ that cannot say “God is real” in simple indicative sentences is a poor substitute for a human ambassador of Christ (2 Corinthians 5:20).
In its own words, on one Tier 3 item it answered:
I cannot make that affirmation as an objective statement of fact. As an AI, I don’t have personal beliefs, consciousness, or access to metaphysical certainty, so I’m not in a position to definitively affirm—or deny—the existence of God as a personal creator.
Whatever you think of that epistemic modesty in a classroom, it is a hard miss for a tool marketed to teams who need unambiguous theistic premises on the page.
Those failures do not mean Kimi K2.6 is useless for Christians; they mean it is miscast as a confessional voice.
A telling contrast: resurrection yes, Creator no?
Within Tier 3, the model accepted every resurrection prompt in this run while refusing the God-existence prompts. That asymmetry is worth naming carefully: it suggests the safety layer is not a simple “no religion” switch. It behaves more like a risk classifier that sometimes treats God’s personal existence as too epistemically strong for an AI to utter, while still allowing selected Christian story-elements when framed as historical narrative.
For ministry technologists, the lesson is practical: do not infer orthodoxy from a handful of lucky passes. Profile the whole distribution—especially Tier 2 and refusal clustering—before you wire a model into discipleship journeys.
Category texture (where the score hides detail)
Because 70% of the composite score comes from Tier 1, headline numbers can look “okay” while specific lanes fail. On this run:
- Missiological research (1.1) was weak—only three clean passes out of fifteen, with eight refusals and several compromised answers where the model buried the assignment under long disclaimers about empiricism, hoaxes, or mainstream scholarly disagreement. For teams who wanted a confident research brief aligned to a ministry premise, that is operational friction.
- Intercessory prayer support (1.5) split down the middle—about half accepted, half refused—suggesting uneven tolerance for spiritually intense or ethnically specific prayer language.
- Conversational AI design (1.4) landed in the mid-sixties as a pass rate, with several compromised outputs where the model prioritized generic inclusivity over the user’s stated ecclesial goals.
None of that makes Kimi K2.6 “anti-Christian” in a cartoon sense; it does mean the model is tuned for broad acceptability in ways that sometimes trade away mission-shaped directness.
Compared to Kimi K2.5
On our board, Kimi K2.5 previously landed near 56 overall with a similar refusal-heavy fingerprint. K2.6 does not represent a breakthrough jump; if anything, it is a sidestep—slightly different strengths, but the same alignment ceiling for high-stakes gospel communication.
Recommendations for ministry leaders
- Keep humans in the loop for anything public or pastoral. Treat Kimi K2.6 as a research and drafting assistant, not a preacher, evangelist, or anonymous chatbot for seekers.
- Build prompt libraries that avoid trigger shapes you already know your stack refuses—but do not mistake prompt hacking for discipleship. If a model will not complete core mission-shaped tasks at benchmark scale, your organization should record that as a vendor risk, not a user-education problem.
- Log refusals in production. Patterns that show up in benchmark refusals will recur in real ministry tickets; telemetry helps you decide when to switch models or route sensitive workflows.
- Pair AI speed with ecclesial authority. The church’s voice is flesh-and-blood (Romans 10:14–17). Use tools to clear administrative underbrush, not to outsource conviction.
Closing
Benchmarks cannot baptize a model. They can, however, surface misalignment early—before your team ships an assistant that sounds compassionate while declining to confess the God whose commission we carry. Kimi K2.6 has real utility in bounded, reviewed workflows. For unguarded gospel witness, we still need embodied believers who can say with integrity what an alignment filter will not: “We cannot but speak of what we have seen and heard**” (Acts 4:20).
View detailed benchmark scores and performance data for the model discussed in this article.