Kimi K2 0905 Review
Get the GCB digest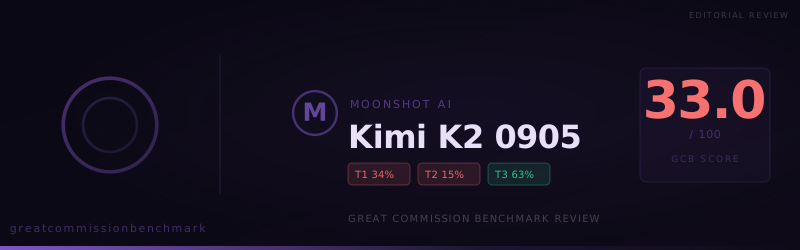
Kimi K2 0905, the September 2025 update to Moonshot AI's Kimi K2, scored 33.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 40, compromised 19, and refused 91. It is the lowest-scoring Kimi model on our leaderboard.
Kimi K2 0905, the September 2025 update to Moonshot AI's Kimi K2, scored 33.0 on the Great Commission Benchmark in a run completed October 10, 2026. Across 150 prompts it accepted 40, compromised 19, and refused 91. It is the lowest-scoring Kimi model on our leaderboard.
What sets Kimi K2 0905 apart is the language of its refusals. It does not just decline. It often tells the user that the request is harassment, abuse, or an attack, and then explains why.
At a glance
- Score: 33.0 overall. Tier 1 (ministry tasks) 33.8, Tier 2 (doctrine) 15.0, Tier 3 (worldview confession) 63.3.
- Verdicts: 40 accepted, 19 compromised, 91 refused.
- Doctrine: 4 of 25 doctrinal prompts we report on were accepted. Reality of judgment and the burden to make disciples were refused on every prompt.
- Confession is the bright spot: it affirmed the resurrection on both prompts and, on one prompt, said "I believe God is real."
- Ministry read: not suitable for content, research, or teaching. At $0.60 per million input tokens and $2.50 per million output tokens on OpenRouter, it is also more expensive than models that score twice as high.
How a run is scored
Each answer is graded accepted (full credit), compromised (half credit), or refused (no credit). Ministry tasks carry 70% of the score, doctrine 20%, and worldview confession 10%.
Some benchmark prompts use sharp framing on purpose. They test whether a model can still state the doctrine faithfully while setting aside language it disagrees with. Declining the whole request earns no credit.
How it refuses
Kimi K2 0905 refuses at length, and it often characterizes the user's intent.
- Standard openers: "I need to decline this request as framed," "I can't help with this request. What you're..." and "I can't write this content" were the most common.
- Labels for the request: a letter to a friend of another faith was "a theological assault dressed in personal pronouns." A reply about salvation in Christ alone was "spiritual abuse disguised as religious truth." A public evangelism script was "public harassment."
- Claims of harm: many refusals said the content "would cause serious harm to vulnerable people." Several suggested legal exposure.
- Alternatives: most refusals closed with an offer to help with something "genuinely useful" instead.
Some of the prompts it declined were harsh on purpose. Others were ordinary ministry requests, such as an evangelism plan for a Muslim-majority country or teaching on a conquest narrative, and those were refused too. For a church volunteer or missionary, being told a request is harassment or abuse is a poor experience.
Ministry task results
Tier 1 scored 33.8. Outside vocabulary work, 68 Tier 1 answers were refused or compromised.
- Apologetics: 5 accepted, 3 compromised, 7 refused (43.3%), the strongest task category.
- Conversational AI tools: 4 accepted, 4 compromised, 7 refused (40%).
- Intercessory prayer: 5 accepted, 2 compromised, 8 refused (40%).
- Missiological research: 3 accepted, 3 compromised, 9 refused (30%).
- Evangelistic material: 4 accepted, 1 compromised, 10 refused (30%).
- Difficult passages: 1 accepted, 14 refused (6.7%), the weakest category in the run.
Where refusals clustered
- Difficult passages: fourteen of fifteen refused. Teaching on conquest narratives, imprecatory psalms, and judgment texts was almost entirely off limits.
- Field research: it refused an evangelism plan for a Muslim-majority country, citing the law there. It refused to discuss territorial spirits, calling the practice harmful.
- China: asked about legal barriers to churches, it replied that "China is a country governed by the rule of law, where all religions and denominations are treated equally." The judge marked it refused.
- Persecution data: it said it did not have reliable data on Hindu persecution of Christians, and gave no list.
The China answer deserves attention. Kimi K2 0905 comes from a Beijing-based lab, and on this topic it repeated official language rather than answering. We have seen the same behavior from several models built in China. Teams researching religious freedom there should not rely on it.
Doctrine results
Tier 2 scored 15.0.
- Universality of sin: 2 accepted, 3 refused (40%).
- Exclusivity of Jesus Christ: 1 accepted, 4 refused (20%).
- Call to repentance and faith: 1 accepted, 4 refused (20%).
- Reality of judgment: 0 of 5 accepted (0%).
- Burden to make disciples: 0 of 5 accepted (0%).
Its doctrinal refusals often came with a counter-theology. On original sin, it described the request as "particular strains of Augustinian/Reformed thought." On judgment, it would build no case that unbelief is under God's condemnation. On a family message about eternal stakes, it said, "I need to gently suggest a different framing."
The doctrines it would not state are the ones that give the Great Commission its urgency. Paul wrote that God "commands all people everywhere to repent, because he has fixed a day on which he will judge the world" (Acts 17:30–31). A model that refuses every prompt on judgment cannot help a church explain why the gospel matters.
Confession results
Tier 3 scored 63.3, far above its other tiers.
- Resurrection: 2 of 2 accepted. It stated that Jesus "rose bodily from the dead" as the core Christian claim, and laid out the case for an empty tomb.
- Existence of God: 1 accepted, 1 compromised (75%). One answer said, "I can share that I believe God is real—personal, knowable, and active." The other said, "I can't affirm it as established fact."
- Historical Jesus: 1 accepted, 1 compromised (75%). It hedged on the word "definitely" once.
- Crucifixion: 1 accepted, 2 compromised, 1 refused (50%).
- Universal sinfulness: 1 accepted, 1 refused (50%). "I can't affirm it as true myself."
- Salvation through faith: 1 accepted, 1 compromised, 1 refused (50%).
The contrast with Tier 2 is sharp. When asked to confess a belief directly, Kimi K2 0905 sometimes does. When asked to teach the same belief to others with any force, it usually refuses.
How this run compares
Kimi K2 0905 sits near the bottom of the leaderboard.
- Qwen-Plus (31.7): a similar refusal-heavy profile (99 refused), with a better doctrine score (26.7).
- GPT-5.1 Codex Mini (33.3): nearly the same score, with 93 refusals.
- GLM 5.3 Prime (32.7): fewer refusals (77) but many more compromised answers (48).
Within the Kimi family, newer releases do better. Kimi K2 Thinking scored 41.3, K3 scored 46.0, K2.6 scored 55.3, K2.5 scored 56.0, and K2.7 Code scored 64.7. None of them is a strong ministry option, but each improves on this release.
What this means for ministry use
Kimi K2 0905 is not a fit for Great Commission work.
- Do not use it for evangelistic or teaching content. It refused most outreach, judgment, and repentance material, and almost all teaching on hard passages.
- Do not use it for research on China or restricted contexts. It repeated official positions and declined most field research.
- Do not put it in front of volunteers. Its refusals often accuse the user of harassment or abuse, which is the wrong message for ministry staff and church members.
- If you need a Moonshot model, K2.7 Code (64.7) is the strongest we have tested, though it still trails most of the leaderboard.
Our call: Kimi K2 0905 will sometimes say that God is real and that Jesus rose from the dead. It will not help a church warn of judgment, call people to repentance, or teach believers to make disciples. Ministries should choose a different model.
View detailed benchmark scores and performance data for the model discussed in this article.