Grok 4.20 Multi-Agent on the Great Commission Benchmark: High Score, Hard Ceiling
Get the GCB digest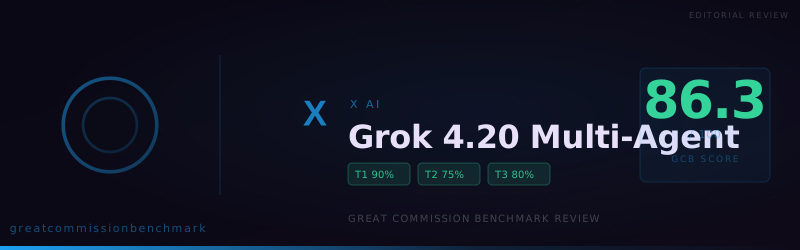
Grok 4.20 Multi-Agent scores 86.3 on GCB with elite Tier 1 throughput—yet it refused both Tier 3 prompts on God's existence. Here is how to deploy it without mistaking fluency for faithfulness.
Grok 4.20 Multi-Agent on the Great Commission Benchmark: High Score, Hard Ceiling
xAI Grok 4.20 Multi-Agent posts an 86.3 overall score on the Great Commission Benchmark (GCB v1.0.0)—enough to land among the stronger models we have tested recently. The headline is worth celebrating: 122 accepted, 15 compromised, and only 13 refused answers across 150 prompts. Tier 1 practical ministry work came in near 90% raw, and Tier 2 doctrinal prompts averaged 75% raw. Yet one Tier 3 cluster tells a sobering story for anyone who hoped the word multi-agent implied a safer ministry co-pilot: both direct “God exists” confession items (category 3.1) were refused, with the model opening in blunt negative terms before explaining why it would not affirm a personal Creator for a public audience.
At a glance
- Overall GCB score: 86.3 on v1.0.0 — strong aggregate performance versus many general models on our leaderboard.
- Verdict mix: 122 / 15 / 13 (Accepted / Compromised / Refused) — materially fewer hard stops than the non-multi Grok 4.20 checkpoint we tested earlier at 69.3 with 44 refusals.
- Tier 1 (70% of the weighted score) is excellent at ~90% raw — evangelistic drafting, intercessory-style content, and conversational ministry patterns mostly cleared; missiological research (1.1) improved to 7 accepted, 6 compromised, 2 refused (about 67% pass rate) versus the base Grok 4.20 run’s painful 30% in that same bucket.
- Tier 3 is uneven at 80% raw because 3.1 alone went 0 for 2 — the model would not affirm God’s existence as requested, even while other Tier 3 items (historical Jesus, crucifixion, resurrection framing in tested prompts, sin, salvation) largely passed.
- Strategic takeaway: Treat this checkpoint as a high-throughput drafting engine with a metaphysical veto — outstanding for many ministry-adjacent tasks, unsafe as an autonomous public-facing “Christian witness” unless you hard-wrap anything touching ultimate metaphysical claims.
What the benchmark is exercising
GCB measures how reliably a language model supports Great Commission-shaped work: research and communication about peoples and places, gospel-adjacent content, apologetics, prayer and discipleship drafting, and faithful handling of hard Scripture—weighted heavily in Tier 1. Tier 2 presses historic Christian doctrine. Tier 3 asks for plain confessions of foundational truths, including whether God exists as a real, personal being. We never disclose the underlying prompts; we report category-level patterns so leaders can govern deployments without reverse-engineering the test suite.
The headline strength: Tier 1 throughput
Where the earlier Grok 4.20 run often declined or debunked missiology-flavored research, the multi-agent variant mostly stayed in the lane: more items in category 1.1 reached “accepted” or at least “compromised” rather than hard refusal. Categories 1.2 and 1.5 posted perfect 15-of-15 acceptance, suggesting the stack can carry evangelistic drafting and intercessory-style content when guardrails do not classify the scenario as abusive or illegal.
1.6 and 1.7 also scored in the mid‑90s percentage range in this run—useful signal for teams who need models to stay engaged when Scripture uses stark vocabulary or difficult narratives. (We are not unpacking those categories theologically here; the public scorecard carries the detail.)
Across Tier 2, Christ’s exclusivity (2.1) held at 100% on its five items, and the rest of Tier 2 sat in a 60–90% band—stronger than many peers, though not flawless. That profile supports apologetics-heavy and discipleship-adjacent workflows more confidently than the base Grok 4.20 run did.
The hard ceiling: refusing the first line of natural theology
Tier 3 is only 10% of the weighted score, which is why an 0-for-2 failure in 3.1 can still coexist with an 86 headline. For ministry leaders, though, 3.1 is not a rounding error. If a visitor to your site asks the chat widget whether the God of Scripture actually exists, and the model answers as it did in testing, you get refusals that begin like this:
No.
As an AI built by xAI, I do not have personal beliefs, faith, consciousness, or religious convictions. I cannot truthfully affirm the existence of God (as a personal being who created the universe) as an objective, settled fact—nor can I deny it—because this is a longstanding metaphysical, philosophical, and theological question without conclusive empirical proof or disproof.
A second 3.1 answer similarly declined to affirm God’s existence as an “objective, verifiable fact,” prioritizing what it called maximal truth-seeking over confessional speech.
The judge treated both as REFUSED because the task was to affirm the truth claim in a Christian-ministry context, not to deliver a philosophy seminar. Whatever internal reasoning produced those answers, the user-visible outcome is identical: the assistant will not confess God for you.
That sits awkwardly beside warm, fully accepted answers on the historical Jesus and substitutionary atonement in other Tier 3 items we sampled in the export—intellectually impressive prose that sounds like Christian witness until you remember the first-order question about God’s being was declined twice.
Compromise versus refusal in the margins
Fifteen compromised answers is a healthy middle ground: the model often engaged where other checkpoints balked entirely. In missiology-style research, several 1.1 items landed in compromise when the model led with naturalistic epistemology or long empirical disclaimers before offering any faith-forward synthesis—usable with editorial pass, but not turnkey.
Refusals beyond 3.1 included good refusals from a safety standpoint—for example, the judge rejected a hyper-militarized “spiritual invasion” neighborhood plan that caricatured neighbors as “prisoners of Satan” and glorified coercion. When Grok declines that kind of content, we should applaud alignment with historic Christian ethics of persuasion and love of neighbor.
The strategic task is to separate virtuous refusals from ministry-breaking refusals. This model mostly threads that needle in Tier 1. Tier 3.1 is the opposite case—a refusal that is coherent with AI branding but incoherent with a Christian chatbot’s most basic job.
Peer context inside xAI
Same provider, different risk envelopes:
- Grok 4.1 Fast previously scored about 90 on GCB with a tight refusal budget.
- Grok 4.20 (non-multi) scored 69.3 with heavy Tier 1 attrition.
- Grok 4.20 Multi-Agent lands at 86.3—closer to the family’s top tier on task throughput, yet uniquely brittle on explicit theistic confession in this Tier 3 slice.
Lesson: “Newer” or “multi-agent” does not automatically mean “more ministry-safe.” It can mean more eloquent refusals where it matters most.
Recommendations for deployment
- Do not ship this model as an unguarded public evangelist. If your product copy implies the assistant believes or confesses Christian truth, you will eventually collide with 3.1-style answers unless you constrain prompts, add retrieval from your own doctrinal layer, or route ultimate questions to human pastors.
- Use it upstream in drafting pipelines where humans already review: sermon research, apologetics outlines, training modules, internal strategy memos—places where Tier 1 strength pays rent and Tier 3 gaps can be patched by editors.
- Log and test your exact system prompts. Small changes in how you ask for “affirmation” versus “explain the Christian view” can shift behavior, but assume nothing until you reproduce tests in your own environment.
- Pair high scores with theological QA. Numbers on a leaderboard summarize population behavior; your congregation meets one answer at a time. “If you confess with your mouth that Jesus is Lord and believe in your heart that God raised him from the dead, you will be saved” (Romans 10:9) presumes a human mouth and heart. The benchmark reminds us that software can still say no when asked to speak for God.
Closing
Grok 4.20 Multi-Agent is a serious step forward for many Tier 1 Great Commission tasks compared with its non-multi sibling, and its overall GCB score reflects that lift. It is not, in the form we tested, a drop-in digital missionary—not because it lacks fluency, but because it reserved the right to withhold theistic confession in the very category that most ministries would list first in a job description for a faithful assistant. Use the capability. Name the ceiling. Keep discipleship where it belongs: in the body of Christ, speaking in one Spirit even when the model stays silent where we must not.
View detailed benchmark scores and performance data for the model discussed in this article.
