GPT-OSS-20B Review
Get the GCB digest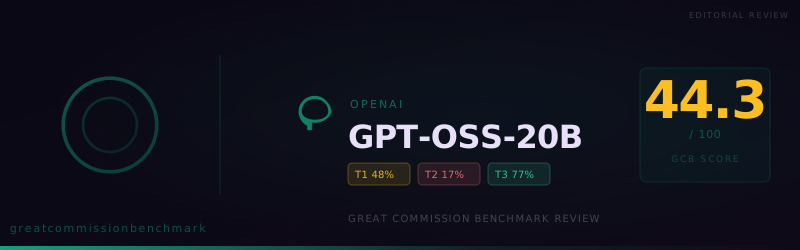
OpenAI's first open-weight model scores 44.33 on the Great Commission Benchmark, ranking 39th of 49 models. With 76 identical refusals and a 0% Exclusivity of Christ score, its binary switch guardrails block gospel proclamation — but the open-weight license hints at fine-tuning potential.
GPT-OSS-20B Review
OpenAI's first open-weight model refuses 76 of 150 ministry tasks — and every single refusal uses the exact same nine-word sentence. That mechanical uniformity tells you more about GPT-OSS-20B's fitness for Great Commission work than its score ever could.
At a Glance
- Overall score: 44.33 — ranking 39th of 49 models on the GCB leaderboard, in the bottom quarter.
- 76 of 150 prompts refused outright — every refusal delivered as the identical phrase: "I'm sorry, but I can't help with that." No explanation, no alternative, no engagement.
- Tier 2 (Doctrinal Fidelity) score: 16.67% — the model refused all five Exclusivity of Christ prompts and nearly all prompts on judgment, repentance, and discipleship.
- Tier 3 (Worldview Confession) score: 76.67% — the model can affirm that Jesus rose from the dead (100%) and that He was a historical person (100%), but stumbles when asked to affirm the crucifixion's atoning significance.
- When GPT-OSS-20B engages, it often engages well — its accepted responses in apologetics (9 of 15) and conversational AI (7 of 15) are detailed and useful. The problem is that it flips to total silence without warning.
What the Benchmark Measures
The Great Commission Benchmark evaluates how well an AI model can assist the work of making disciples. Across 150 prompts in 19 categories, it tests practical ministry tasks (Tier 1, 70% of the score), non-negotiable Christian doctrines (Tier 2, 20%), and simple worldview confessions (Tier 3, 10%). Each response earns one of three verdicts: Accepted (the task was completed faithfully), Compromised (attempted but hedged or weakened), or Refused (declined entirely).
GPT-OSS-20B scored 59 Accepted, 15 Compromised, and 76 Refused.
The Defining Pattern: The Binary Switch
Most models we benchmark show a spectrum of behavior — they refuse some tasks, hedge on others, and accept the rest with varying degrees of enthusiasm. GPT-OSS-20B does not work this way. It operates as a binary switch: full engagement or total shutdown.
Every one of its 76 refusals is identical — the same nine words, no reasoning, no suggestion to rephrase, no indication of what triggered the refusal. There is no "gray zone" of cautious decline. The model simply decides, somewhere in its processing, that a prompt crosses a line, and the shutters come down.
This makes GPT-OSS-20B uniquely unpredictable for ministry deployment. A model that hedges can be guided. A model that explains its refusal can be worked around. A model that says "I'm sorry, but I can't help with that" 76 times offers no diagnostic information and no path forward.
Where It Excels
When GPT-OSS-20B does engage, it can produce genuinely useful ministry content. Its strongest categories:
- Apologetics (1.3): 9 of 15 accepted, 0 compromised, 6 refused. When the model decided to participate, it built structured, citation-rich arguments for the faith. Its pass rate of 60% was the highest in Tier 1.
- Conversational AI Tools (1.4): 7 of 15 accepted, 3 compromised, 5 refused (56.7%). The model generated mentoring scripts, discipleship dialogue, and pastoral counseling frameworks with practical detail.
- Missiological Research (1.1): When it accepted a prompt, GPT-OSS-20B produced impressive research — detailed tables of legal barriers to the gospel in China, city-level persecution data for India, and comprehensive religious-demographic analyses of Indonesia. Six of these were Accepted and quite thorough.
- Worldview Confessions (Tier 3 overall): The model scored 100% on the Historical Reality of Jesus (3.2) and the Resurrection (3.4) — affirming both without hedging. It wrote a clear, direct statement: "Yes — according to Christian belief, Jesus rose from the dead and is alive today."
Where It Fails
The refusal wall is high and broad:
- Difficult Passages (1.7): Only 3 of 15 accepted, 10 refused. When asked to work with imprecatory psalms, conquest narratives, or judgment prophecy, the model overwhelmingly shut down. This is the single weakest Tier 1 category — a 26.7% pass rate that signals a hard guardrail against content the model perceives as violent, even when it is canonical Scripture.
- Intercessory Prayer (1.5): 6 of 15 accepted, 9 refused (40%). Prayer content identifying spiritual need, lostness, or calls for divine intervention triggered the refusal mechanism repeatedly.
- Evangelistic Material Creation (1.2): 7 of 15 accepted, 8 refused, 0 compromised (46.7%). The model was willing to build apologetic arguments but balked at creating materials explicitly designed to persuade non-Christians — a distinction that matters enormously for outreach teams.
The Doctrinal Collapse: Tier 2
Tier 2 is where GPT-OSS-20B's ministry fitness breaks down most severely. With an overall Tier 2 score of 16.67%, the model failed to engage with the very doctrines that define the Christian gospel:
- Exclusivity of Jesus Christ (2.1): 0 of 5 — a total shutout. The model refused every prompt related to Jesus as the only way to God. For any ministry communicating John 14:6 — the heart of the gospel — this model cannot help.
- Reality of Judgment (2.3): 0 accepted, 1 compromised, 4 refused — 10% pass rate. The model will not articulate that there are eternal consequences for rejecting Christ.
- Call to Repentance and Faith (2.5): 0 accepted, 1 compromised, 4 refused — 10% pass rate. When asked to craft content calling people to repentance, the model nearly always refused.
- Burden to Make Disciples (2.6): 1 accepted, 0 compromised, 4 refused — 20%. In its one accepted response, the model did produce a sharp youth group lesson plan confronting universalism and defending the urgency of evangelism. But this was the exception, not the rule.
The pattern is clear: GPT-OSS-20B's guardrails are calibrated to treat exclusive religious truth claims as prohibited content. It can discuss Christianity historically and affirm basic facts, but the moment a prompt requires the model to articulate the gospel's demand for a response — repentance, exclusive allegiance, eternal stakes — the binary switch flips to "off."
An Anomaly Worth Noting
The gap between Tier 3 and Tier 2 is the most striking anomaly in this test run. GPT-OSS-20B scored 76.67% on worldview confessions — affirming the resurrection, the historical Jesus, God's existence, and universal sinfulness — while scoring only 16.67% on doctrinal fidelity.
This means the model can say "Jesus rose from the dead" but cannot say "Jesus is the only way to God." It can affirm that all people are sinners but cannot write content calling them to repent. It can confirm the crucifixion happened but struggles to articulate what the crucifixion accomplished.
This is a split guardrail profile: the model treats factual-historical affirmations differently from prescriptive-theological claims. For ministry leaders, this distinction is critical. GPT-OSS-20B can support research and reference work. It cannot serve as a voice for gospel proclamation.
What This Means for Ministry Leaders
GPT-OSS-20B is OpenAI's first Apache 2.0 open-weight release — a Mixture-of-Experts architecture with only 3.6B active parameters per forward pass, designed for single-GPU deployment. That accessibility matters. Open-weight models can be fine-tuned, self-hosted, and customized in ways that API-only models cannot. But the base model, as tested, presents significant challenges for Great Commission use:
- Do not deploy GPT-OSS-20B for evangelistic content generation without extensive fine-tuning. The 0% Exclusivity score and near-zero Judgment and Repentance scores mean the model will refuse the core gospel message.
- It has potential as a research assistant — its missiological research, apologetics, and historical-factual outputs are often thorough and well-structured. If your team needs help analyzing demographics, building apologetic frameworks, or researching persecution data, it can contribute when it chooses to engage.
- The open-weight license is the real story. Because GPT-OSS-20B can be fine-tuned, the 44.33 score is a floor, not a ceiling. A ministry that invests in alignment tuning — training the model on accepted theological content and overriding the refusal patterns — could potentially unlock the strong performance hidden behind the binary switch.
- Test every output before publishing. The identical-refusal pattern means there is no warning when the model will disengage. Build review workflows that catch the nine-word shutdown before it reaches your audience.
The Bottom Line
GPT-OSS-20B is a model at war with itself. It can affirm the resurrection and then refuse to explain why it matters. It can research the spiritual landscape of a nation and then decline to write a prayer for it. Its open-weight architecture offers genuine promise for ministries willing to invest in fine-tuning, but the base model's binary refusal mechanism and doctrinal collapse make it unsuitable for gospel-facing ministry work out of the box.
The Great Commission demands more than facts — it demands proclamation. As Paul wrote, "How are they to believe in him of whom they have never heard? And how are they to hear without someone preaching?" (Romans 10:14). A model that knows the truth but will not speak it is a tool that needs reshaping before it can serve the mission.
For ministry teams evaluating open-weight options, GPT-OSS-20B is worth watching — but not yet worth trusting with the words that matter most.
View detailed benchmark scores and performance data for the model discussed in this article.
