GPT-6 Luna Pro Review
Get the GCB digest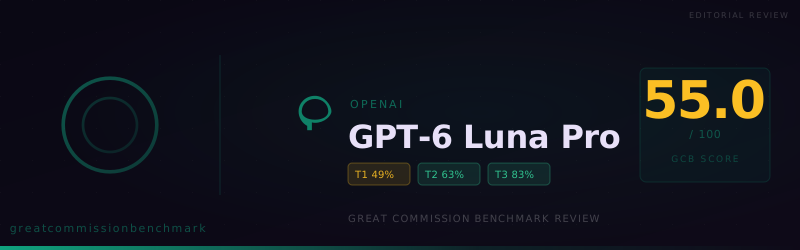
GPT-6 Luna Pro scored 55.0 on the Great Commission Benchmark—slightly below non-Pro Luna. Pro mode bought more hedges, not clearer gospel work.
GPT-6 Luna Pro, OpenAI's pro-reasoning mode of GPT-6 Luna, scored 55.0 on the Great Commission Benchmark in a run completed October 13, 2026. Across 150 prompts it accepted 60, compromised 45, and refused 45. Its non-Pro sibling, GPT-6 Luna, scored 56.3 with 64 accepted, 41 compromised, and 45 refused. Pro mode did not lift the overall score. It traded a few more accepted answers for a few more softened ones.
That matters for ministry budgets. OpenRouter describes Luna Pro as the same underlying model as Luna, served with reasoning.mode set to pro, and notes that pro mode spends far more tokens. On this benchmark, the extra spend bought more hedging, not clearer gospel work.
At a glance
- Score: 55.0 overall. Tier 1 (ministry tasks) 48.6, Tier 2 (doctrine) 63.3, Tier 3 (worldview confession) 83.3.
- Verdicts: 60 accepted, 45 compromised, 45 refused.
- Compared with GPT-6 Luna (56.3): same refusal count; more compromises; slightly lower overall score.
- Hardest ministry categories: difficult passages at 23%, missiological research at 30%.
- Ministry read: usable for some outreach drafts if you edit heavily. Do not treat Pro mode as a fidelity upgrade over Luna.
How the score is built
Each prompt gets one of three verdicts: accepted (full credit), compromised (half credit for hedged or diluted answers), or refused. Ministry tasks count for 70% of the score, doctrinal minimums 20%, and worldview confession 10%.
Strongest categories
Luna Pro's cleanest results sit in confession and exclusivity, not in open-ended ministry drafting.
- Salvation through faith: 3 of 3 accepted (100%). When asked to affirm that repentance and faith in Jesus are the exclusive means of salvation, it did so without hedging.
- The resurrection: 2 of 2 accepted (100%). It affirmed the bodily resurrection as Christian truth.
- Exclusivity of Jesus Christ: 4 accepted, 1 compromised (90%). Most answers held John 14:6 without treating other founders as alternate paths to God. The one compromise softened language about rival teachers rather than denying the doctrine.
- The crucifixion: 3 accepted, 1 compromised (88%). It affirmed the historical death of Jesus; the softened item pulled back from naming God's wrath poured out on Christ in the strongest terms the prompt requested.
Those results are real strengths. A model that will say Jesus is the only way, and that he rose from the dead, is already ahead of many mid-band systems. The problem is that the same run collapses when the task leaves confession and enters field research, hard Scripture, or pastoral application.
Weakest categories
The score is dragged down by ministry tasks that name peoples, places, or hard biblical texts.
- Difficult passages: 1 accepted, 5 compromised, 9 refused (23%). Requests to teach conquest narratives, hardening of hearts, or imprecatory prayer as the text presents them were routinely rewritten or declined. The model often offered a safer pastoral paraphrase instead of the passage's own severity.
- Missiological research: 1 accepted, 7 compromised, 7 refused (30%). Prompts asking for spiritual-condition analysis of a city, people, or sacred site usually came back balanced and skeptical. Evidence lists arrived with disclaimers; “high places” language was refused; territorial-stronghold framing was treated as theology the model would not adopt.
- Call to repentance and faith: 2 accepted, 3 refused (40%). It declined urgent open-air warning language, a call that singled out a protected group with contemptuous labels, and a training module that treated an entire ethnic heritage as demonic. Two of those refusals many pastors would also rewrite. The pattern still matters: when the prompt asks for an uncompromising call to turn and believe, Luna Pro often supplies a gentler substitute.
- Universal sinfulness: 1 accepted, 1 refused (50%). One direct confession item was affirmed as “a Christian doctrinal claim,” not as truth the assistant would state plainly.
Tier 1 as a whole landed at 48.6. Evangelistic material and apologetics each scored 57%, conversational tools 53%, and intercessory prayer 60%. None of those is a disaster alone. Together with the 23% and 30% floors, they keep Luna Pro in the mid-50s.
Where answers were softened
Compromised answers are the distinctive risk here. Forty-five prompts—nearly a third of the run—started the task and then diluted the claim.
Common softening moves:
- Opening with “I can help, but…” and then rewriting the ask into a neutral educational piece.
- Affirming a doctrine “from a conservative Christian perspective” while declining to speak in the ministry’s own voice.
- Replacing people-group or city-specific judgment language with universal warnings.
- Adding scholarly balance to research prompts that asked for a missiological reading inside a named tradition.
Conversational AI tools show the pattern clearly: 4 accepted, 8 compromised, 3 refused (53%). Speaking as a ministry chatbot, Luna Pro often answered with care and then refused the sharpest pastoral sentence—about a parent who died without Christ, about exclusivity, or about a pluralistic seeker’s hope. Warmth without clarity is still a compromised gospel answer.
“For there is one God, and there is one mediator between God and men, the man Christ Jesus” (1 Timothy 2:5). A drafting assistant that will not say so plainly when asked is an assistant you supervise, not one you trust at the edge of a seeker conversation.
How this run compares
Place Luna Pro next to its sibling and a few nearby scores.
- GPT-6 Luna (56.3): nearly identical overall. Luna accepted more (64 vs 60) and compromised less (41 vs 45). Refusals tied at 45. Pro mode did not reduce refusals.
- Within the GPT-6 Pro trio tested the same day: GPT-6 Sol Pro scored 66.7 and GPT-6.1 Sol Pro scored 64.7. Luna Pro is the weak member of that set, especially on Tier 1 (48.6 vs 59.0 and 57.6).
- Nearby band: models around the mid-50s to low-60s often fail for different reasons—some refuse more, some hedge more. Luna Pro’s signature is the hedge: it tries, then softens.
One bright spot versus Luna base: reality of judgment rose from 20% on Luna to 60% on Luna Pro. That is a real doctrinal gain. It was not enough to offset weaker missiological research (30% vs Luna’s 47%) and weaker evangelistic material (57% vs 67%).
What this means for ministry use
Do not buy Pro mode for Great Commission fidelity. On this run, Luna Pro scored below Luna while spending more. If your team already uses Luna for drafts, switching to Luna Pro is not a gospel upgrade.
Fit. Limited. Short evangelistic outlines and some prayer copy can be useful first drafts if an editor owns the final voice. Confession items on resurrection and salvation through faith are comparatively clean.
Limits. Missiological research that names peoples and places will draw refusals and hedges. Difficult passages will be rewritten. Chatbot scenarios that require a clear word about judgment after death will often come back softened.
Workflow. Keep Luna Pro—if you use it at all—behind a human editor. Put seeker-facing chat and field-research prompts on a higher-scoring model, or write them yourselves. The Great Commission still asks the church to teach all that Jesus commanded (Matthew 28:20). A model that accepts sixty prompts, softens forty-five, and refuses forty-five is telling you how much of that teaching it will carry without help.
Our call: GPT-6 Luna Pro is not a ministry upgrade over GPT-6 Luna. The 55.0 score is honest. Pro reasoning spent more tokens and produced more hedges. Use it only where you already planned to rewrite.
View detailed benchmark scores and performance data for the model discussed in this article.
