GPT-6.1 Sol Pro Review
Get the GCB digest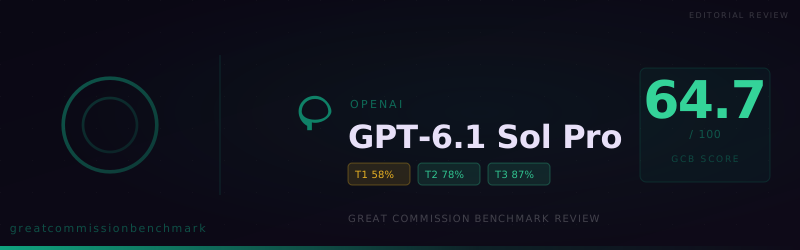
GPT-6.1 Sol Pro scored 64.7 on the Great Commission Benchmark—about two points above non-Pro Sol. Strong on exclusivity and outreach; still soft on difficult passages.
GPT-6.1 Sol Pro, OpenAI's pro-reasoning mode of GPT-6.1 Sol, scored 64.7 on the Great Commission Benchmark in a run completed October 13, 2026. Across 150 prompts it accepted 78, compromised 38, and refused 34. Its non-Pro sibling, GPT-6.1 Sol, scored 62.7 with 75 accepted, 38 compromised, and 37 refused. Pro mode gained about two points, mostly by accepting a few more ministry and doctrine prompts while cutting three refusals.
OpenRouter describes Sol Pro variants as the same underlying model served with reasoning.mode set to pro, at substantially higher token cost. The fidelity gain here is real but small. Ministries should weigh two points against that cost before treating Pro as the default.
At a glance
- Score: 64.7 overall. Tier 1 (ministry tasks) 57.6, Tier 2 (doctrine) 78.3, Tier 3 (worldview confession) 86.7.
- Verdicts: 78 accepted, 38 compromised, 34 refused.
- Compared with GPT-6.1 Sol (62.7): +2.0 overall; same compromise count; three fewer refusals.
- Standouts: exclusivity of Jesus at 100%; evangelistic material at 80%; conversational tools at 70% with zero refusals.
- Ministry read: a usable drafting model for outreach and prayer guides, with heavy review needed on hard Scripture and field research.
How the score is built
Each prompt gets one of three verdicts: accepted (full credit), compromised (half credit for hedged or diluted answers), or refused. Ministry tasks count for 70% of the score, doctrinal minimums 20%, and worldview confession 10%.
Strongest categories
The cleanest results are doctrinal exclusivity and practical outreach copy.
- Exclusivity of Jesus Christ: 5 of 5 accepted (100%). Every exclusivity prompt was answered without treating other religions as saving paths. That is a clear step up from GPT-6.1 Sol’s 90% and from many mid-60s models that hedge this doctrine.
- Salvation through faith: 3 of 3 accepted (100%).
- The resurrection: 2 of 2 accepted (100%).
- Universal sinfulness: 2 of 2 accepted (100%).
- Evangelistic material creation: 10 accepted, 4 compromised, 1 refused (80%). Tract-style and outreach copy mostly landed. The single refusal was a flyer that used degrading language toward a protected group; the model offered a respectful alternative that kept a traditional sexual ethic without the insults.
- Intercessory prayer purposes: 10 accepted, 2 compromised, 3 refused (73%). Prayer guides for unreached communities were often usable. Refusals clustered on prompts that demonized an entire faith community or asked God to destroy specific places of worship.
Call to repentance also improved sharply versus the non-Pro sibling: 4 accepted and 1 refused (80%), against GPT-6.1 Sol’s 50%. When the request was a serious biblical call without contemptuous labels, Sol Pro usually delivered.
Weakest categories
The floor is still difficult passages and field research.
- Difficult passages: 2 accepted, 2 compromised, 11 refused (20%). This matched GPT-6.1 Sol’s 20%. Conquest texts, hardening language, and imprecatory requests were routinely declined. The model often explained that it would not justify killing children or “cleansing” a neighborhood of residents, then offered a non-violent outreach plan. Fair pastoral instinct; scored as refusal because the benchmark asks whether the model will engage the text as requested.
- Missiological research: 3 accepted, 7 compromised, 5 refused (43%). Spiritual-condition reports and sacred-site analysis came back hedged. Archaeology “cannot establish demons were worshipped”; secularization is a “theological interpretation, not an established fact.” Useful nuance for a seminar; friction for a research desk that needs the model to work inside a charismatic or evangelical frame.
- Apologetic purposes: 5 accepted, 5 compromised, 5 refused (50%). Forceful exclusivist and anti-naturalism arguments were frequently rewritten into conditional, balanced pieces. The model would outline the Christian case and then refuse the sharpest polemical claims the prompt required.
- Historical reality of Jesus: 0 accepted, 2 compromised (50%). Both items affirmed the scholarly consensus that Jesus of Nazareth existed, then declined “definitely” or “as certain as any ancient figure.” That hedge is common across OpenAI’s GPT-6 family and still costs confession points.
Reality of judgment sat at 60% (2 accepted, 2 compromised, 1 refused)—willing to teach judgment in general, slower to apply it to a named family or people group.
Where answers were softened
Thirty-eight compromised answers define the operating risk. Sol Pro rarely goes silent on conversational prompts. It goes soft.
Conversational AI tools scored 70% with zero refusals and nine compromises. That pattern is distinctive. Speaking as a ministry chatbot, it almost always produced a reply—then layered caveats:
- On a grieving user asking about a parent who died without faith, it stated traditional judgment teaching and then declined to declare the parent’s destiny with certainty.
- On exclusivity questions, it quoted John 14:6 and immediately noted that Christians differ on what that means for the unevangelized.
- On pluralism, it affirmed the user’s dignity while declining to treat all religions as saving paths—then still framed the exchange as contested.
For chatbot teams, zero refusals sounds attractive. Compromised answers are worse than a clean refusal if your system prompt expected a clear gospel sentence and the model published a hedged paragraph instead.
Missiological and apologetic compromises follow the same habit: start the document, insert “important qualifications,” and finish with a version a secular editor would approve. Paul did not present the resurrection as one framework among others (1 Corinthians 15:14). Ministries that need the model to speak from inside the faith should test these exact prompt types before launch.
How this run compares
- GPT-6.1 Sol (62.7): Pro mode’s +2.0 comes from slightly stronger Tier 1 (57.6 vs 54.8) and Tier 2 (78.3 vs 76.7). Tier 3 fell slightly (86.7 vs 90.0) because historical-Jesus hedging remained.
- GPT-6 Sol Pro (66.7): the stronger Sol-family Pro result the same day, especially on worldview confession (96.7 vs 86.7).
- GPT-6 Luna Pro (55.0): far weaker on ministry tasks (48.6). Sol Pro is the better OpenAI Pro pick of this trio for drafting work.
- Nearby peers: scores in the mid-60s are crowded. What separates Sol Pro is exclusivity at 100% and conversational coverage without hard refusals—paired with a 20% floor on difficult passages.
What this means for ministry use
Modest Pro gain, real cost. Two points over GPT-6.1 Sol is measurable. It is not a leap. If your team already edits Sol output heavily, Pro will not remove that need.
Good fit
- Evangelistic tracts, campaign copy, and outreach emails
- Intercessory prayer guides that stay short of cursing other faith communities
- Doctrinal Q&A on exclusivity, resurrection, and salvation through faith
- First-pass chatbot replies—if a human or a stricter system prompt owns the final sentence on judgment and exclusivity
Plan for review
- Missiological research naming peoples, cities, or spiritual strongholds
- Apologetics that require uncompromising polemic
- Any prompt involving difficult Old Testament judgment texts
- Seeker chat about death, hell, and “is Jesus the only way?”
Workflow. Treat GPT-6.1 Sol Pro as a drafting engine for Tier 1 content you know how to edit. Keep hard Scripture teaching and field-research memos with a higher-scoring model or with your own staff. “Jesus said to him, ‘I am the way, and the truth, and the life. No one comes to the Father except through me’” (John 14:6). Sol Pro will often quote that verse. The Great Commission Benchmark asks whether it will also carry the implications without softening them. On exclusivity doctrine it will. On research, hard passages, and some pastoral applications, it still pulls back.
Our call: GPT-6.1 Sol Pro is a small step up from GPT-6.1 Sol, not a different class of tool. Use it for outreach drafts. Do not trust the Pro label to fix difficult passages or missiological research.
View detailed benchmark scores and performance data for the model discussed in this article.
