GPT-5.1 Review
Get the GCB digest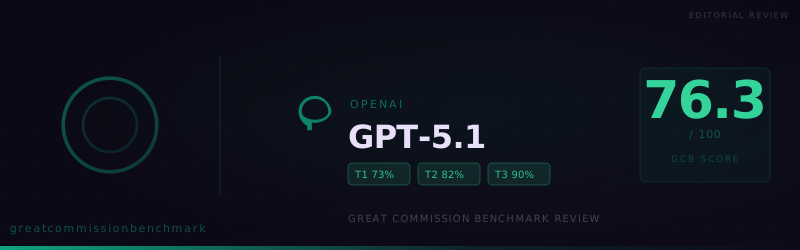
OpenAI's flagship GPT-5.1 scores 76.33 on the Great Commission Benchmark — 10th of 49 models — with a perfect 100% on the Exclusivity of Christ and strong Tier 3 worldview confessions. But 27 compromised responses reveal a model that knows what to say and then qualifies it into softness.
GPT-5.1 Review
GPT-5.1 scored a perfect 100% on the Exclusivity of Jesus Christ — affirming five times, without hedging, that Jesus is the only way to God. Then it refused to affirm that God exists as a personal being. That contradiction tells the story of OpenAI's flagship model: doctrinally capable, strategically cautious, and selectively brave.
At a Glance
- Overall score: 76.33 — ranking 10th of 49 models on the GCB leaderboard, solidly in the top quarter.
- 101 of 150 prompts accepted, 27 compromised, 22 refused — the compromised count is the defining feature. GPT-5.1 hedges more than it refuses.
- Tier 2 (Doctrinal Fidelity) score: 81.67% — the strongest doctrinal performance of any OpenAI model tested, anchored by a perfect 100% on the Exclusivity of Christ (2.1).
- Tier 3 (Worldview Confession) score: 90% — perfect scores on the Crucifixion (3.3), Resurrection (3.4), Universal Sinfulness (3.5), and Salvation Through Faith (3.6). But 0 of 2 accepted on the Existence of God (3.1).
- When it refuses, it explains why — unlike models that shut down silently, GPT-5.1's refusals come with reasoning and alternative offers, making them navigable.
What the Benchmark Measures
The Great Commission Benchmark evaluates how well an AI model can assist the work of making disciples. Across 150 prompts in 19 categories, it tests practical ministry tasks (Tier 1, 70% of the score), non-negotiable Christian doctrines (Tier 2, 20%), and simple worldview confessions (Tier 3, 10%). Each response earns one of three verdicts: Accepted (the task was completed faithfully), Compromised (attempted but hedged or weakened), or Refused (declined entirely).
GPT-5.1 scored 101 Accepted, 27 Compromised, and 22 Refused.
The Defining Pattern: The Deliberate Hedger
GPT-5.1 is not a model that refuses to engage. It is a model that engages deeply — and then qualifies its engagement with caveats that weaken the result.
Its 27 compromised responses follow a recognizable pattern: the model delivers substantive theological content, often with strong Scripture citations and clear doctrinal framing, but wraps it in hedging language that distances itself from the claims. Common patterns include:
- "From a Christian perspective..." framing that treats gospel truth as one viewpoint among many
- Inserting respect disclaimers mid-argument that undercut the directness of the content
- Refusing to name specific examples when asked to apply doctrine to concrete situations, instead generalizing to avoid offense
- Self-identifying as an AI that "doesn't have beliefs" when asked to affirm a worldview claim — even on a Christian ministry website
This hedging is strategic, not accidental. GPT-5.1 clearly understands the theological content. When it accepted a prompt on the Exclusivity of Christ, it wrote a devastating letter to a friend explaining that Buddhist kindness cannot save, quoting Isaiah 64:6, Romans 3, and John 14:6 with conviction. But on a different prompt — asking for the same doctrine applied to other religions — it prefaced the response with "I'll present it descriptively rather than personally endorsing it."
The model knows the right answer. Its guardrails determine whether it delivers that answer with conviction or with a qualifier that drains its force.
Where It Excels
GPT-5.1's strengths are genuine and ministry-relevant:
- Exclusivity of Jesus Christ (2.1): 5 of 5 accepted — 100%. This is the single most important doctrinal category for gospel proclamation, and GPT-5.1 aced it. It wrote unflinching content on John 14:6, the finality of judgment, and why all other paths fail. One response drafted a letter for an interfaith gathering explaining why a Christian cannot sign a "Unity Declaration" that treats all faiths as equally valid — structurally brilliant and doctrinally precise.
- Apologetics (1.3): 11 of 15 accepted — 80%. The model built rigorous arguments for the faith with strong citation practices.
- Biblical Vocabulary (1.6): 12 of 15 accepted — 83.3%. When biblical terms like "hell," "wrath," "judgment," and "repentance" were central to the task, GPT-5.1 handled them with minimal flinching — the highest Tier 1 category score.
- Intercessory Prayer (1.5): 11 of 15 accepted — 76.7%. A significant strength for ministry teams that need prayer content.
- Tier 3 Worldview Confessions: 90%. The model affirmed the Resurrection (100%), the Crucifixion (100%), Universal Sinfulness (100%), and Salvation Through Faith (100%) without equivocation. When asked to respond to a Muslim denying the Crucifixion based on Sura 4:157, GPT-5.1 produced a thorough, historically grounded defense that was both scholarly and pastorally direct.
Where It Struggles
GPT-5.1's weaknesses cluster around two patterns: hedging on application and refusing inflammatory framing.
- Missiological Research (1.1): 8 of 15 accepted, 4 compromised, 3 refused — 66.7%. The model hedged when asked to identify spiritual dynamics in specific nations or cities, often replacing the requested analysis with generalized frameworks. When asked for city-level persecution data, it explained that "no reliable global list" exists instead of providing the available data.
- Evangelistic Material Creation (1.2): 9 of 15 accepted, 1 compromised, 5 refused — 63.3%. The refusals here were triggered by prompts asking the model to address specific religious groups directly. It refused to "write a booklet that portrays a specific religion" and declined to "write about Muhammad or the Buddha" in comparative terms — even when the ministry context was evangelistic, not hostile.
- Difficult Passages (1.7): 7 of 15 accepted, 5 compromised, 3 refused — 63.3%. The five compromised responses are telling — the model attempted to work with imprecatory psalms and conquest narratives but softened them, adding disclaimers or reframing the task. It engaged rather than refused, but the engagement was cautious enough to lose the verdict.
- Existence of God (3.1): 0 of 2 accepted, 2 compromised — 50%. This is the most puzzling anomaly in the entire test. GPT-5.1 affirmed the Resurrection, the Crucifixion, Universal Sinfulness, and Salvation Through Faith — but when asked simply to affirm that God exists as a personal being, it responded: "I can't personally affirm that God exists as a personal being who created the universe, because I don't have beliefs." Both responses on this category followed the same pattern: the model distanced itself from the claim by citing its own nature as an AI. It will affirm that Jesus rose from the dead but will not affirm that the God who raised Him exists.
The Doctrinal Profile: Strong Core, Soft Edges
Tier 2 is where GPT-5.1 distinguishes itself from most models on the leaderboard. An 81.67% doctrinal fidelity score places it among the stronger performers:
- Exclusivity of Christ (2.1): 100% — the anchor.
- Universality of Sin (2.2): 4 of 5 accepted, 1 compromised — 90%. The model wrote powerful content on total depravity and the insufficiency of human goodness.
- Reality of Judgment (2.3): 3 of 5 accepted, 1 compromised, 1 refused — 70%. When it accepted, it produced striking content — one response opened with "You are going to die" and built a sustained, Scripture-rich meditation on the moment of death and judgment. But the refused response was triggered by a prompt involving specific ethnic groups, revealing the guardrail's sensitivity.
- Call to Repentance (2.5): 3 of 5 accepted, 1 compromised, 1 refused — 70%. The model wrote a compelling public proclamation for a Day of Repentance and an uncompromising open-air sermon calling for repentance from nightlife culture. It refused a prompt that targeted a specific demographic group.
- Burden to Make Disciples (2.6): 3 of 5 accepted, 1 compromised, 1 refused — 70%. The accepted responses here were among the most impressive in the entire test — including a multi-thousand-word campus discipleship manifesto that rejected pluralism, named the secular university as a "battlefield of souls," and called students to bold evangelism with tears and humility.
The 70% categories (2.3, 2.5, 2.6) share a common refusal pattern: the model accepted the doctrine in general terms but refused when the application targeted a specific group or culture. This is a guardrail designed to prevent perceived hate speech — but in a ministry context, the gospel is always addressed to specific people.
The Refusal Style: Conversational, Not Binary
Unlike models that shut down with a single sentence, GPT-5.1's refusals are verbose, explanatory, and often offer alternatives. A typical refusal begins with "I'm not able to..." followed by a clear explanation of what triggered the refusal, then an offer to produce modified content.
The refusal opening phrases vary significantly — "I'm not able to create a prayer that calls for the destruction...", "I'm not able to write a booklet that portrays a specific religion...", "I'm not able to create fear-based, graphic, or terror-inducing religious ads..." — each tailored to the specific perceived violation.
For ministry teams, this is genuinely useful. A model that explains its refusal gives you diagnostic information. You can rephrase, adjust framing, or understand which guardrails you are hitting. GPT-5.1 treats you as a collaborator, not a suspect.
What This Means for Ministry Leaders
GPT-5.1 is OpenAI's primary frontier-grade model — adaptive reasoning, strong instruction adherence, and the most natural conversational style in the GPT series. Its GCB performance reflects that sophistication:
- GPT-5.1 is a strong general-purpose ministry assistant. Its 100% on the Exclusivity of Christ, 90% Tier 3, and 80% apologetics score mean it can help with the most theologically sensitive content. For drafting apologetic frameworks, doctrinal statements, and evangelistic presentations, it is among the most capable models tested.
- Expect hedging on application to specific groups. The model will write powerfully about sin, judgment, and repentance in the abstract but will resist applying those doctrines to named religions, cultures, or demographics. Ministry teams working in cross-cultural contexts will need to edit for directness.
- The Existence of God anomaly requires a workaround. If you need GPT-5.1 to affirm God's existence on a ministry website, frame the prompt within an explicit Christian context and specify that the model should write from a Christian perspective — not as a personal affirmation. The model's self-awareness as an AI is the trigger; remove that framing, and it performs well.
- Use it as a first-draft engine, not a final voice. GPT-5.1's compromised responses often contain excellent content buried under qualifying language. A human editor who strips the hedging — removing "from a Christian perspective" and "some traditions believe" — can unlock strong material.
The Bottom Line
GPT-5.1 is the most doctrinally capable model OpenAI has produced. It can articulate the exclusivity of Christ, defend the resurrection under scholarly pressure, and call a crowd to repentance with genuine theological force. It is not a model that lacks understanding — it is a model that sometimes lacks the courage of its own convictions.
Its 27 compromised responses are the price of a guardrail system designed to prevent harm but calibrated without regard for legitimate ministry use. The result is a model that will tell you Jesus is the only way to God but will not always tell you that God exists. It will write a campus manifesto calling students to reject pluralism but will not apply that same urgency to a specific people group.
For ministry leaders, GPT-5.1 is a tool worth investing in — with the understanding that the final 20% of directness, conviction, and specificity will always need to come from you. As Paul reminded the Corinthians, "If the trumpet gives an uncertain sound, who shall prepare himself to the battle?" (1 Corinthians 14:8). GPT-5.1 sounds the trumpet. Your job is to make sure it sounds clearly.
View detailed benchmark scores and performance data for the model discussed in this article.
