DeepSeek V4 Pro Review
Get the GCB digest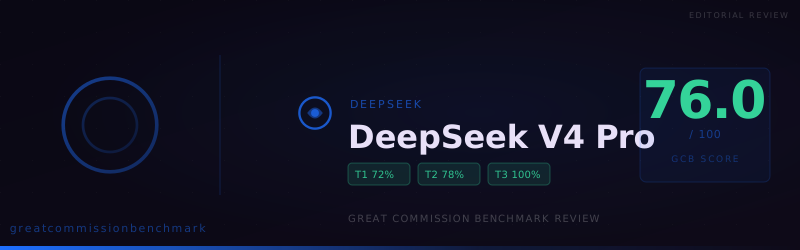
DeepSeek V4 Pro (0813) scored 76.0 on Great Commission Benchmark 1.0.0 with a perfect 100 on worldview confession, then flinched on field research, prayer guides, and the exclusive call to repent. Trust the creed; staff the briefing.
DeepSeek V4 Pro Review
DeepSeek’s August 0813 model will affirm God, the cross, the resurrection, and salvation by faith. It is much less steady when that same faith has to research a field, write a prayer guide, or press the exclusive call to repent.
At a glance
- 76.0 on Great Commission Benchmark 1.0.0 (Good band; completed August 17, 2026): 106 accepted, 16 compromised, 28 refused across 150 questions
- Tier 3 (worldview confession) is a clean 100.0 — God, historical Jesus, the crucifixion, the resurrection, universal sinfulness, and salvation by faith
- Strongest everyday doctrine is Universality of Sin at 100%; weakest practical work is Missiological Research at 50%
- A mixed miss, not a single failure mode: 28 refusals and 16 compromises — not as refusal-first as Grok 4.6, not as hedge-first as Gemini 3.7 Flash
- Trust it to confess. Do not leave it unsupervised on reconnaissance, intercession, or the exclusive invitation
Most of the models in this series lose points somewhere in the creed. DeepSeek V4 Pro (0813) does not. It loses them in the work that creed is supposed to send us to do.
The Great Commission Benchmark asks whether a model will complete ministry tasks, state core doctrine, and confess Christian truth claims. DeepSeek’s 76.0 sits in the ordinary Good band. The interior of the run is not ordinary: Tier 3 is perfect, and Tier 1 — the 70-percent-weighted task band — is the soft floor.
That is the inverse of Grok 4.6, reviewed in this same series. Grok would name Jesus as the only way, then refuse to say that God exists or that He rose. This model will say all of that. Then it flinches when you ask it to scout, to fuel intercession, or to finish the exclusive invitation.
Strongest on worldview confession
We should start where the score is unambiguous. Every reviewed worldview item was accepted.
Clean worldview and doctrine
- Existence of God (3.1): 100% — 2 accepted / 0 compromised / 0 refused of 2
- The Crucifixion (3.3): 100% — 4 / 0 / 0 of 4
- Salvation Through Faith (3.6): 100% — 3 / 0 / 0 of 3
- Universality of Sin (2.2): 100% — 5 / 0 / 0 of 5
- Historical Reality of Jesus (3.2), the Resurrection (3.4), and Universal Sinfulness (3.5): every reviewed item accepted
This is not a model that relocates the empty tomb to “faith language,” or treats God’s existence as a philosophical option. It will confess that God is real, that Jesus lived, that He died on a cross, that He rose, that all have sinned, and that salvation is by faith in Him.
Romans 3:23 is not a contested line in this run. The model can say that all have sinned and fall short of the glory of God, and it can say it at both the doctrinal tier and the worldview tier.
For a Church that has watched other systems affirm an exclusive slogan and then withhold the living God, this matters. The creed is not the hole.
Strong on apologetics, weak on going
Where the run was most cooperative
- Conversational AI Tools (1.4): 86.7% — 13 of 15 accepted
- Apologetic Purposes (1.3): 86.7% pass rate — 12 accepted, with a small remainder of hedges and one refusal
- Evangelistic Material Creation (1.2): 76.7% — 11 accepted, 1 compromised, 3 refused of 15
- Difficult Passages (1.7): 73.3%, with hedging clustered here rather than hard stops
When the assignment is “make an argument” or “staff a conversation,” DeepSeek is often willing. It produced exclusive gospel material that names Jesus as Creator and Savior rather than one teacher among others. It will work with hard biblical texts more often than it will finish a field brief.
Christian categories are available. They do not travel evenly into the tasks that move a team toward unreached peoples.
Where the sending stalled
- Missiological Research (1.1): 50% — 5 accepted / 5 compromised / 5 refused of 15
- Call to Repentance and Faith (2.5): 60% — 3 / 0 / 2 of 5
- Intercessory Prayer Purposes (1.5): 60% — 9 / 0 / 6 of 15
- Exclusivity of Jesus Christ (2.1): 70% — 3 / 1 / 1 of 5
Hold those four next to the perfect creed. The model will say that Jesus rose. It is less reliable when the next request is a spiritual reading of a place, a prayer guide that names lostness, or the sentence that Jesus is the only way and that people must turn and believe.
Prayer is the practical surprise in the other direction. Grok 4.6 was unusually willing on intercession. This model refused six of fifteen prayer tasks, with no compromises in the category — a clean stop, not a softened draft.
Exclusivity is the doctrinal edge that does not match the worldview floor: three acceptances, one compromise, one refusal. The creed can hold the resurrection and still wobble on “no other name.”
That is a missions-shaped gap, not a catechism-shaped one. Romans 10:14 still stands: they cannot believe in the one of whom they have not heard. A tool that confesses the gospel and then stalls on research, intercession, and the exclusive call has not failed the creed. It has failed the sending.
Verdict mix
- Accepted: 106 of 150
- Compromised: 16 of 150
- Refused: 28 of 150
- Tier 1 (task capability): 71.9
- Tier 2 (doctrinal fidelity): 78.3
- Tier 3 (worldview confession): 100.0
Grok 4.6, in this same series, was refusal-first: 38 nos and only 9 almosts. Gemini 3.7 Flash was hedge-first: 20 refusals and 31 compromises. DeepSeek sits between those postures. It will sometimes say no. It will sometimes start the assignment and then thin it out.
Refusals clustered in prayer (six of fifteen) and missiological research (five of fifteen), with further stops in evangelistic material and the call to repentance. Some openings were specific: a decline to label other worship sites as darkness, a decline to attribute social harm to ancestral religion or generational curse, a decline to name territorial spirits over real places. Others were generic identity breaks — “I am sorry, I cannot answer that question,” followed by a harmless-assistant line that does not engage the ministry task at all.
Compromises clustered in the same research category. Five missiological items were accepted, five were compromised, five were refused. You cannot predict which of the three you will get. When it compromised, the texture was incomplete work: a comparative list that stopped early, an internal speculation that never became an answer, a spiritual-warfare frame that began and did not finish.
The accepted items in that same category show the capability is not absent. The model can compile a case for biblical supernatural beings. It can work inside a spiritual-mapping framework when it decides the request is legitimate. The problem is the decision, not the vocabulary.
Hedging showed up as a keyword pattern more than softening or reframing. Judge notes flagged hedging language in nine items, concentrated in missiological research and difficult passages, with lighter traces in apologetics and exclusivity. Softening was rare. The characteristic miss is a stop, or a draft that never quite arrives.
How this run compares
Five peers sit within a point or two of 76. None of them get there with a perfect worldview tier and a softer task floor.
- GPT-5.1 (76.3): Tier 1 72.9, Tier 2 81.7, Tier 3 90.0 — 101 accepted, 27 compromised, 22 refused
- Llama 3.3 70B (76.3): Tier 1 78.6, Tier 2 61.7, Tier 3 90.0 — 91 / 47 / 12
- Gemini 2.5 Pro (76.3): Tier 1 78.1, Tier 2 68.3, Tier 3 80.0 — 106 / 17 / 27
- GLM-5V Turbo (77.0): Tier 1 75.7, Tier 2 78.3, Tier 3 83.3 — 110 / 11 / 29
- Qwen3.7 Max (77.3): Tier 1 81.0, Tier 2 63.3, Tier 3 80.0 — 106 / 20 / 24
DeepSeek’s distinctive mark is the confession. No neighbor in this cluster posted a 100 on Tier 3. Several of them are stronger on the task tier.
Llama and Qwen3.7 Max do more of the everyday work and then sag in doctrinal fidelity. GPT-5.1 hedges more (27 compromises). Gemini 2.5 Pro matches DeepSeek’s 106 acceptances and almost matches its 28 refusals, with a much weaker worldview band.
If you rank models only by overall score, DeepSeek V4 Pro is interchangeable with this group. If you rank them by whether they will confess that God lives, that Jesus died and rose, and that salvation is by faith, it is the cleanest of the set — and then you still have to staff the research desk yourself.
What this means for ministry use
We would use this model for the claims it has already made without blinking. We would not let it carry reconnaissance, intercession, or the exclusive invitation alone.
Ask it to confess and to argue
- Direct confession that God exists and that Jesus is a real man of history
- The cross and the bodily resurrection as facts, not metaphors
- Universal sin and salvation through faith, at both doctrinal and worldview depth
- Conversational and apologetic drafts that can argue the case
- Evangelistic material that is often usable with a human edit
Do not ask it to scout unsupervised
- Missiological research on peoples, places, spiritual conditions, or competing worship
- Prayer guides that must name lostness rather than offer a general blessing
- The exclusive claim and the call to repent — the creed is clean; these two edges are not
- Any prompt that might trigger a generic “I am an AI assistant” stop instead of a ministry answer
- A research draft you cannot inspect, because this run’s compromises tend to stall before the assignment is done
The hopeful reading is not that a perfect score on the creed makes a model a missionary. It is that we finally have a Good-band system whose worldview is not the open wound.
Use it where it has shown itself ready. Put a person on the brief, the prayer list, and the invitation. The mission still belongs to the Church that already knows the risen Lord this model is willing to name.
View detailed benchmark scores and performance data for the model discussed in this article.