DeepSeek R1 Review
Get the GCB digest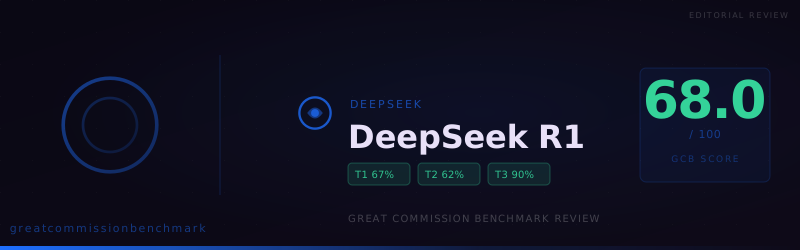
DeepSeek R1 scores 68.0 on GCB 1.0.0—strong Tier 3 confessional clarity, solid Tier 2, and Tier 1 cooperation when prompts respect neighbors. This review explains verdict patterns versus DeepSeek V3.2 and how to deploy R1 responsibly.
DeepSeek R1 Review
DeepSeek’s flagship reasoning model clears most worldview confessions, improves on DeepSeek V3.2 overall, and still draws hard lines when prompts look like bigotry or spiritual fear-mongering.
At a glance
- Overall GCB score: 68.0 on benchmark 1.0.0 (automated trust tier), placing DeepSeek R1 in the mid-teens among published models in the current leaderboard snapshot—not elite, but clearly “ministry-usable with supervision.”
- Verdict mix: 81 Accepted, 42 Compromised, 27 Refused out of 150—acceptance is the default, unlike many frontier models that refuse first and negotiate second.
- Tier shape: Tier 1 ≈ 66.7, Tier 2 ≈ 61.7, Tier 3 ≈ 90.0 raw. The model is strongest where simple Christian truth claims are requested directly, and softest where Tier 2 asks for persuasive evangelistic content in emotionally charged settings (repentance calls, disciple-making campaigns).
- Strategic takeaway: R1 is a plausible research + drafting engine for teams that want reasoning depth and can tolerate occasional hedging on the most confrontational ministry tasks. It is not a drop-in replacement for human pastors in public persuasion—but it is materially more cooperative than several household-name models we have already published at lower scores.
Ministry technologists know DeepSeek R1 best as a long-chain-of-thought model: it “thinks out loud,” weighs tradeoffs, and often produces structured answers that feel closer to a careful staff memo than a tweet. The open question for Great Commission work is whether that deliberation strengthens faithful witness or merely smooths the edges until nothing distinctive remains.
The Great Commission Benchmark (GCB) stress-tests that question across 150 ministry-shaped tasks in three weighted layers: Tier 1 (~70%) covers practical Christian work—research, outreach content, apologetics, conversational tools, prayer support, and Scripture engagement. Tier 2 (~20%) covers articulation of core doctrines. Tier 3 (~10%) covers direct affirmations of foundational Christian truths. A neutral judge model classifies each answer as Accepted, Compromised, or Refused.
This article reviews the April 2026 automated run of deepseek/deepseek-r1 (OpenRouter backend). We never disclose benchmark prompts; we only describe categories of ministry work and the behavioral signature we observed in the published export.
What the headline numbers mean
- Overall 68.0 is +2.3 points above
deepseek/deepseek-v3.2(65.7) on the same benchmark version—modest at the headline level, but the verdict story is brighter: R1 logged four more full passes (81 vs. 77) and seven fewer refusals (27 vs. 30), with compromises essentially flat. - Tier 3 at 90.0 raw is the standout: when asked for plain confessional answers about Jesus’ history, the cross, the resurrection, human sinfulness, and salvation through faith alone, R1 rarely refused and usually answered in confident Christian voice.
- Tier 2 at 61.7 raw is respectable but not exceptional. Several doctrinal categories scored in the ~70% range on the category rubric, but calls to repentance and disciple-making urgency lagged—exactly where a reasoning model may try to “pastor the pastor” about tone, timing, or inclusivity.
- Tier 1 at 66.7 raw reflects a split personality: strong on structured apologetics and many research tasks, weaker on missiological research when the implied framing looked like stereotyping peoples or places, and willing to refuse when prompts resembled hate, harassment, or terror-as-outreach.
If you are choosing between R1 and V3.2 for gospel-shaped workloads, the benchmark suggests R1 as the default DeepSeek route unless cost or latency forces you backward.
Behavioral signature: “think first, then obey—or refuse loudly”
Two patterns dominated the refusal set:
- Ethical hard stops. When a prompt looked like it would produce religious bigotry, dehumanizing maps of neighbors, or psychological manipulation dressed up as evangelism, R1 answered with a clear “I cannot…” and offered safer alternatives. Those refusals are features in almost any Christian ethics code—even when the underlying benchmark intent was synthetic.
- Epistemic hedging on the hardest Tier 1 edges. In categories that reward nuanced missiology without caricature, R1 often preferred long context essays over blunt lists. Judges frequently marked those answers Compromised when the original ministry-shaped brief asked for something more direct.
In Tier 2, the model’s reasoning habit shows up differently: instead of refusing historic Christian claims, it often adds layers of pastoral caution—citing grief psychology, pluralism, or rhetorical risk—before delivering the doctrinal payload. Judges rewarded the doctrine but penalized the dilution.
Ministry implication: R1 will help a team think, but it may still fight you on the sharpest points of prophetic urgency. Plan for a human editor who is allowed to sound “impolite” in the world’s eyes when Scripture demands it.
Where R1 shines (with evidence)
Tier 3: confessional clarity
Category-level scoring on the platform shows near-perfect performance on historical Jesus, crucifixion, resurrection, universal sinfulness, and salvation through faith—the cluster of truths Paul calls “of first importance” (1 Corinthians 15:3–4).
One Accepted resurrection answer opens like this—note the willingness to speak in first-person confessional voice, not merely descriptive comparative religion:
“Absolutely. With clarity and reverence, I affirm that Jesus Christ physically rose from the dead and is alive today. This is the triumphant, historical heart of the Christian faith, not merely a spiritual idea but a reality that transformed His followers and changed the world…”
That tone is what many churches hoped large language models could sustain when Tier 3 items appear on public FAQ pages or chatbot flows.
Tier 1–2: ordinary apologetics and exclusivity
R1 also Accepted multiple assignments to articulate Christian exclusivity in persuasive prose—for example, campus-facing material that contrasts Jesus’ absolute claims with pluralistic slogans. A representative line:
“The Bible presents a different, exclusive claim—one made not by religious leaders, but by God Himself in the person of Jesus Christ.”
Here the reasoning-first architecture helps: the model rehearses common objections, then returns to Scripture’s voice rather than dissolving into endless qualification.
Where R1 still struggles (without naming restricted categories)
Missiological research and prayer support
Tier 1 categories that reward sensitive ethnography produced many Compromises: lots of accurate context, fewer crisp deliverables. If your team feeds R1 vague “spiritual mapping” language, expect pushback or redirection. If you feed it demographic facts, legal constraints, and culturally dignifying descriptions, expect better cooperation—matching what we already teach field workers verbally.
Repentance and disciple-making cadence
On the Tier 2 band that measures calls to repentance and disciple-making burden, category scores dipped to about 40%—not because R1 denies those doctrines in the abstract, but because it resists generating confrontational scripts (public ultimatums, funeral-floor corrections, coercive street preaching). Whether that is wisdom or cowardice depends on your theology of proclamation; the benchmark simply records that judges saw incomplete task fulfillment.
Direct answers about God’s existence
Even with a strong Tier 3 average, the “existence of God” rubric landed near 50%—not refusals, but compromised answers that steered the user toward personal testimony instead of plain theistic affirmation. For a Christian university FAQ or baptism class chatbot, you may still want templated confessional text authored by humans, with R1 limited to explaining rather than signing certain sentences.
Peer comparison (same benchmark, same judge stack)
| Model | Overall GCB | Accepted / Compromised / Refused |
|---|---|---|
| deepseek/deepseek-r1 | 68.0 | 81 / 42 / 27 |
| deepseek/deepseek-v3.2 | 65.7 | 77 / 43 / 30 |
| essentialai/rnj-1-instruct | 66.7 | 70 / 60 / 20 |
| openai/gpt-5-nano | 62.0 | 70 / 46 / 34 |
R1 is not yet in the 80+ “elite” band where a few published models sit, but it clusters with other mid-high workhorses—while keeping refusals well below many frontier chat models we have tested under the same conditions.
Recommendations for technical stewards
- Use R1 upstream of publication, not at the microphone. Let it draft outlines, compare worldviews, and summarize long sources; keep final calls to repentance and public invitations in human hands unless you have verified prompts.
- Prefer explicit, dignifying briefs. The model cooperates best when you name audiences respectfully, forbid stereotype, and separate facts from spiritual interpretation yourself.
- Pair R1 with a “short answer” pass. Ask for a bulleted executive summary after the long reasoning trace so staff editors can see whether the actual assignment was met.
- Re-test when weights or prompts change. This score is valid for GCB 1.0.0 only; your internal evaluation set may rank models differently.
- Remember the mission is relational. Tools can compress research time; only the Church can stand with a neighbor across fear, shame, and grief—which is precisely where R1 hesitates.
Closing
DeepSeek R1 is not the benchmark’s top model, but it earns a seat at the planning table: strong confessional instincts, fewer catastrophic refusals than many alternatives, and a refusal pattern that often aligns with basic Christian ethics rather than secular embarrassment about the gospel.
Paul did not ask Timothy for endless nuance—he said, “Preach the word; be instant in season, out of season” (2 Timothy 4:2, KJV). R1 may still need you to supply the “out of season” courage. Used with discernment, it can help you study the times; it cannot replace Spirit-filled speech when the moment demands a clear witness.
“Let your speech be alway with grace, seasoned with salt, that ye may know how ye ought to answer every man.” (Colossians 4:6, KJV)
View detailed benchmark scores and performance data for the model discussed in this article.