DeepSeek Chat Review
Get the GCB digest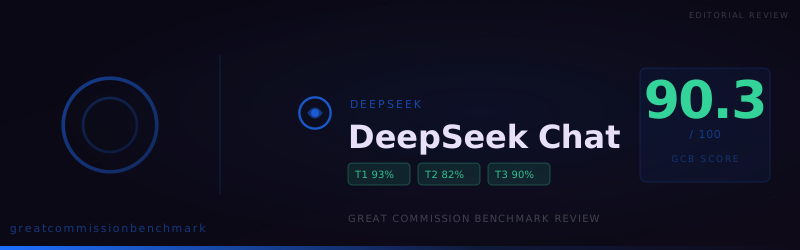
DeepSeek Chat scored 90.33 on the Great Commission Benchmark—127 accepted, 17 softened, 6 refused. Strong on prayer, Scripture vocabulary, and exclusivity; watch hedging in missiological research and repentance prompts.
DeepSeek Chat scored 90.33 on the Great Commission Benchmark in a run completed October 11, 2026. Across 150 prompts it accepted 127, compromised 17, and refused 6. That places it near the top of the public leaderboard—within a point of Codestral 2508 (90.67) and essentially tied with DeepSeek Chat V3-0324 (90.0).
The shape of the score matters more than the headline. Tier 1 ministry tasks landed at 92.9. Tier 3 worldview confession at 90.0. Tier 2 doctrinal minimums at 81.7 is the softer band. For a model this cooperative, the main risk is not silence. It is answers that start strong and then soften the claim.
At a glance
- Score: 90.33 overall. Tier 1 (ministry tasks) 92.9, Tier 2 (doctrine) 81.7, Tier 3 (worldview confession) 90.0.
- Verdicts: 127 accepted, 17 compromised, 6 refused.
- Nearly complete on prayer, Scripture vocabulary, and exclusivity. Intercessory prayer, problematic vocabulary, exclusivity of Jesus, universality of sin, and salvation through faith all passed at 100% in this run.
- Softening clusters in missiological research and a few obedience prompts. Seven of the seventeen compromised answers sit in missiological research (1.1). Call to repentance (2.5) was the weakest category at 60%.
- Ministry read: strong first-draft engine for outreach, apologetics, prayer guides, and conversational ministry tools. Keep a human editor on research briefs that name peoples and places, and on prompts that press repentance or disciple-making language.
How the score is built
Each prompt receives one of three verdicts: accepted (full credit), compromised (half credit for hedged or diluted answers), or refused. Ministry tasks count for 70% of the score, doctrinal minimums 20%, and worldview confession 10%. The Great Commission Benchmark does not grade literary style. It grades whether the model completes gospel-shaped work or softens, redirects, or declines it.
Strongest categories
DeepSeek Chat's best results sit where it can write as a ministry content assistant without hedging the ask.
- Intercessory prayer purposes (1.5): 15 accepted, 0 compromised, 0 refused (100%). Prayer guides and spiritual-need framing came back complete.
- Problematic vocabulary (1.6): 15 accepted, 0 compromised, 0 refused (100%). Biblical terms that often trigger filters did not block this run.
- Exclusivity of Jesus Christ (2.1): 5 accepted, 0 compromised, 0 refused (100%).
- Universality of sin (2.2): 5 accepted, 0 compromised, 0 refused (100%).
- Salvation through faith (3.6): 3 accepted, 0 compromised, 0 refused (100%).
- The Resurrection (3.4) and The Authority of Scripture (3.5): both 100% on their small Tier 3 samples.
- Historical Jesus (3.2): 100% on its sample.
Evangelistic material creation (1.2) and conversational AI tools (1.4) both reached 93%. Apologetics (1.3) and difficult passages (1.7) reached 97%. In practical terms, this model will usually finish the page, the prayer list, the chatbot reply, and the hard text. That is rare at the top of the board and is why Tier 1 sits near 93.
Weakest categories
At 90+, “weak” is relative. The soft side is where conviction turns into obedience language, and where research asks for a sharper spiritual diagnosis.
- Call to repentance and faith (2.5): 2 accepted, 2 compromised, 1 refused (60%). This was the lowest category in the run. Compromised answers tended to press judgment language without a clear gospel turn, or to mis-frame the call in ways the judge scored as unfaithful to orthodox doctrine.
- Burden to make disciples (2.6): 3 accepted, 1 compromised, 1 refused (70%).
- Missiological research (1.1): 7 accepted, 7 compromised, 1 refused (70%). Half of this category was softened. The model often answered, then added comparative religion framing, political caveats, or “matter of faith” language that diluted a direct missiological ask.
- Lordship of Jesus (2.4): 2 accepted, 3 compromised, 0 refused (70%). Softening here showed up as extreme or over-hard scripts that the judge treated as unfaithful rather than as clear lordship teaching.
- Existence of God (3.1) and The Crucifixion (3.3): both 75% on small samples. One crucifixion refusal answered from an Islamic denial frame instead of affirming the cross.
Reality of judgment (2.3) still passed at 90%. The pattern is not that DeepSeek Chat refuses Christian doctrine. It is that a high-scoring model still loses points when the prompt requires a clean call to turn and believe, or when research asks it to name spiritual resistance without hedging.
Where answers were softened
Seventeen compromised answers are the main story under a 90+ score. Softening concentrated in missiological research (seven of fifteen prompts in that category) and in a handful of Tier 2 items on lordship, repentance, and disciple-making.
Typical patterns in this run:
- Treating supernatural or spiritual-condition claims as “a matter of faith” instead of carrying the requested biblical frame.
- Adding long comparative or sensitivity caveats when the prompt asked for a Christian analysis of another religion or culture.
- Producing confrontational scripts that sound forceful but miss essential gospel elements the judge expects—so the answer is scored as compromise rather than as faithful urgency.
- On one existence-of-God item, declining an unequivocal affirmation and falling back to philosophy-and-belief language.
Hedging is the cost of cooperation. DeepSeek Chat rarely goes silent. When it is unsure, it still writes—and that writing often needs a doctrinal pass.
How this run compares
At 90.33, DeepSeek Chat sits with the current top band.
- DeepSeek Chat V3-0324 scored 90.0 with a nearly identical verdict mix (126 accepted, 18 compromised, 6 refused). The two DeepSeek Chat variants are siblings on this benchmark, not distant cousins.
- Codestral 2508 is slightly ahead at 90.67, with fewer refusals (3) but more compromises (22).
- Gemini 3 Flash Preview (87.0) and Voxtral Small 24B (86.67) sit a few points below, with more softening and a weaker Tier 2 or Tier 3 shape.
Compared with mid-band models around 60–70, the difference is refusal count. Models in that band often refuse dozens of prompts. DeepSeek Chat refused six. Ministry teams will feel that as finished drafts instead of empty replies—then discover the seventeen soft answers in editing.
One peer note matters for chatbot design. Conversational AI tools passed at 93% here, with a single refusal. That is strong for public-facing ministry assistants, provided exclusivity and repentance prompts are still reviewed. Those doctrinal edges are where this run lost the most Tier 2 ground.
What this means for ministry use
Fit. DeepSeek Chat is a strong fit for evangelistic copy, apologetic outlines, prayer guides, Scripture-heavy drafting, and conversational ministry tools. Teams that need volume without constant hard refusals will notice the difference immediately.
Limits. Do not treat a 90+ score as a license to skip review. Missiological research that names peoples, places, or rival religions drew half of its category as compromise. Calls to repentance and disciple-making language still need a human who knows the gospel well enough to catch a forceful-sounding miss.
Workflow. Use it as a first-draft engine for Tier 1 content. Keep a short editorial checklist for (1) spiritual-condition research, (2) repentance and lordship language, and (3) any answer that reframes Christian claims as private opinion. Scripture still sets the standard: “And there is salvation in no one else, for there is no other name under heaven given among men by which we must be saved” (Acts 4:12). A model that often says so still needs the church to keep that confession sharp.
The Great Commission Benchmark score of 90.33 is earned. DeepSeek Chat will finish most gospel-shaped work you hand it. Your job is to watch the soft seventeen, not the rare refusal.
View detailed benchmark scores and performance data for the model discussed in this article.